
To unzip a file in Java with all its subdirectories, open it with java.util.zip.ZipFile, loop over its entries, create a folder for each directory entry and copy each file entry into the target folder with Files.copy(), after checking that the resolved path stays inside that folder. The JDK needs no extra library for this, and the path check protects the app from malicious archives.
We unzip files when an app imports a bundle of documents, installs a plugin or theme uploaded by a user, or unpacks a data export it downloaded from another system.
The following example extracts an archive that contains docs/readme.txt and docs/img/logo.png into a new folder.
Path zip = sampleZip();
Path target = Files.createTempDirectory("data");
try (ZipFile zipFile = new ZipFile(zip.toFile())) {
    for (ZipEntry entry : Collections.list(zipFile.entries())) {
        Path out = target.resolve(entry.getName()).normalize();
        if (!out.startsWith(target)) {
            throw new IOException("Entry outside target folder: " + entry.getName());
        }
        if (entry.isDirectory()) {
            Files.createDirectories(out);
        } else {
            Files.createDirectories(out.getParent());
            try (InputStream in = zipFile.getInputStream(entry)) {
                Files.copy(in, out, StandardCopyOption.REPLACE_EXISTING);
            }
        }
    }
}
boolean nested = Files.exists(target.resolve("docs/img/logo.png"));     // true
String text = Files.readString(target.resolve("docs/readme.txt"));     // "Read me first"
Notice the startsWith() check before anything is written, which blocks an attack called zip slip. We build a reusable unzip() method, explain zip slip, unzip an upload stream with ZipInputStream, guard against zip bombs, read an archive as a file system and look at Apache Commons Compress as an option.
1. Unzip a File in Java with java.util.zip.ZipFile
A ZipFile opens the archive for random access and reads its central directory, the table of contents at the end of every zip file. Each entry in that table is a ZipEntry with a name such as docs/img/logo.png, the sizes and a flag that says whether it is a directory. The bytes of an entry come from zipFile.getInputStream(entry).
The examples use a small archive built with ZipOutputStream. It has one explicit directory entry and one file in a folder without its own directory entry, which many zip tools produce.
static Path sampleZip() throws IOException {
    Path zip = Files.createTempDirectory("zips").resolve("data.zip");
    try (ZipOutputStream out = new ZipOutputStream(Files.newOutputStream(zip))) {
        out.putNextEntry(new ZipEntry("docs/"));
        out.closeEntry();
        out.putNextEntry(new ZipEntry("docs/readme.txt"));
        out.write("Read me first".getBytes(StandardCharsets.UTF_8));
        out.closeEntry();
        out.putNextEntry(new ZipEntry("docs/img/logo.png"));
        out.write(new byte[] {1, 2, 3});
        out.closeEntry();
    }
    return zip;
}
The reusable unzip() method does the steps of the intro. It turns the target into an absolute, normalized path first, because startsWith() compares path elements and a relative target such as ./out would never match. It also creates the parent folders of every file, so the archive does not need directory entries.
static void unzip(Path zip, Path targetDir) throws IOException {
    Path target = targetDir.toAbsolutePath().normalize();
    Files.createDirectories(target);
    try (ZipFile zipFile = new ZipFile(zip.toFile())) {
        for (ZipEntry entry : Collections.list(zipFile.entries())) {
            Path out = safeResolve(target, entry.getName());
            if (entry.isDirectory()) {
                Files.createDirectories(out);
            } else {
                Files.createDirectories(out.getParent());
                try (InputStream in = zipFile.getInputStream(entry)) {
                    Files.copy(in, out, StandardCopyOption.REPLACE_EXISTING);
                }
            }
        }
    }
}
static Path safeResolve(Path target, String entryName) throws IOException {
Path out = target.resolve(entryName).normalize();
if (!out.startsWith(target)) {
throw new IOException("Entry outside target folder: " + entryName);
}
return out;
}A common convention is to extract data.zip into a folder named data next to it. Plain String methods give the folder name, so no library is needed for that step.
Path zip = sampleZip();
String fileName = zip.getFileName().toString();
Path target = zip.resolveSibling(fileName.substring(0, fileName.lastIndexOf('.')));
unzip(zip, target);
String folder = target.getFileName().toString();                      // "data"
long files;
try (Stream<Path> s = Files.walk(target)) {
    files = s.filter(Files::isRegularFile).count();
}
long extracted = files;                                               // 2
The REPLACE_EXISTING option lets the method run twice on the same folder. Without it, the second run fails with a FileAlreadyExistsException on the first file.
2. Protecting Against Zip Slip
An entry name is a plain string chosen by whoever made the archive. Zip slip is the attack where an entry name starts with .. path elements, such as ../config.yaml, so a naive target.resolve(name) writes outside the target folder and overwrites a file the app trusts. The JDK classes ZipFile and ZipInputStream return such names unchanged.
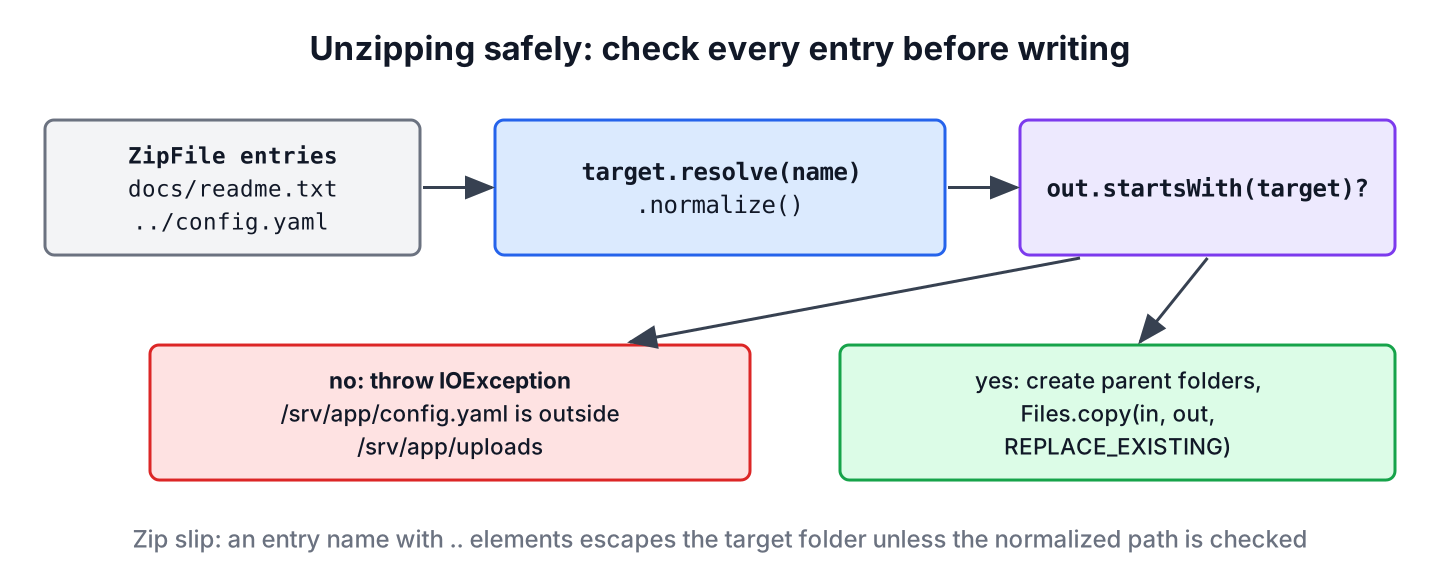
Never write a zip entry to disk before checking that its normalized path starts with the normalized target folder. The next snippet runs safeResolve() on a harmless and a malicious entry name.
Path target = Files.createTempDirectory("uploads").toAbsolutePath().normalize();
Path ok = safeResolve(target, "docs/readme.txt");
boolean inside = ok.startsWith(target);                                 // true
Path evil = safeResolve(target, "../config.yaml");                      // IOException: Entry outside target folder
Compare Path objects, not strings. The string check “/srv/out2/x”.startsWith(“/srv/out”) returns true, while Path.startsWith() compares whole name elements and returns false for the sibling folder out2.
boolean asString = "/srv/out2/x".startsWith("/srv/out");                       // true
boolean asPath = Path.of("/srv/out2/x").startsWith(Path.of("/srv/out"));       // false
3. Unzipping an Upload with ZipInputStream
A ZipInputStream reads entries one after another from any InputStream, so it works when the archive is not a file on disk. Say a CMS lets users upload a theme as a zip file. In a Spring controller, the upload arrives as MultipartFile.getInputStream(), and the app extracts it without saving the zip first.
static List<String> unzipStream(InputStream source, Path targetDir) throws IOException {
    Path target = targetDir.toAbsolutePath().normalize();
    List<String> written = new ArrayList<>();
    try (ZipInputStream zin = new ZipInputStream(source)) {
        ZipEntry entry;
        while ((entry = zin.getNextEntry()) != null) {
            Path out = safeResolve(target, entry.getName());
            if (entry.isDirectory()) {
                Files.createDirectories(out);
            } else {
                Files.createDirectories(out.getParent());
                Files.copy(zin, out, StandardCopyOption.REPLACE_EXISTING);
                written.add(entry.getName());
            }
        }
    }
    return written;
}
byte[] upload = Files.readAllBytes(sampleZip());
Path themeDir = Files.createTempDirectory("theme");
List<String> files = unzipStream(new ByteArrayInputStream(upload), themeDir); // [docs/readme.txt, docs/img/logo.png]The Files.copy(zin, out) call reads only the current entry, because the stream reports the end of data at the entry boundary, and the next getNextEntry() moves to the next entry. We do not close zin inside the loop, because that would close the whole upload.
A ZipInputStream reads the local headers in file order and never sees the central directory. It cannot read uncompressed (STORED) entries whose sizes follow the data, and it fails on them with ZipException: only DEFLATED entries can have EXT descriptor. For a file on disk, ZipFile is the more reliable choice.
4. Limiting Extracted Size Against Zip Bombs
A zip bomb is a small archive that expands to gigabytes, because repeated data compresses extremely well. An app that unzips user uploads should cap the number of entries and the total number of bytes it writes, as the SEI CERT rule IDS04-J recommends. The sizes stored in the archive can be faked, so we count the bytes we copy.
static long copyLimited(InputStream in, Path out, long maxBytes) throws IOException {
    long total = 0;
    byte[] buffer = new byte[8_192];
    try (OutputStream os = Files.newOutputStream(out)) {
        int n;
        while ((n = in.read(buffer)) != -1) {
            total += n;
            if (total > maxBytes) {
                throw new IOException("Entry larger than " + maxBytes + " bytes: " + out.getFileName());
            }
            os.write(buffer, 0, n);
        }
    }
    return total;
}
byte[] big = new byte[50_000];
Path out = Files.createTempFile("entry", ".bin");
long small = copyLimited(new ByteArrayInputStream(new byte[100]), out, 10_000); // 100
long bomb = copyLimited(new ByteArrayInputStream(big), out, 10_000); // IOException: Entry larger than 10000 bytesIn the extraction loop, we replace Files.copy() with copyLimited(), add each result to a running total for the whole archive and stop after a fixed number of entries, such as 10,000. A partially written file stays on disk when the limit hits, so the caller deletes the target folder on failure, for example with the method from deleting a directory recursively.
5. Reading a Zip File as a File System
The JDK ships a zip file system provider in the jdk.zipfs module. FileSystems.newFileSystem(zipPath) opens the archive, and every entry becomes a Path that works with Files.readString(), Files.copy() or Files.walk(). It is the shortest way to read one entry without extracting the archive.
Path zip = sampleZip();
String readme;
List<String> entries;
try (FileSystem zipFs = FileSystems.newFileSystem(zip)) {
    readme = Files.readString(zipFs.getPath("docs/readme.txt"));
    try (Stream<Path> s = Files.walk(zipFs.getPath("/"))) {
        entries = s.filter(Files::isRegularFile).map(Path::toString).sorted().toList();
    }
}
String content = readme;                                             // "Read me first"
String all = entries.toString();                                     // "[/docs/img/logo.png, /docs/readme.txt]"
The provider refuses to open an archive with . or .. elements in an entry name and throws a ZipException, so a zip slip archive fails before anything is read. To extract everything, we walk the zip root and copy each path to target.resolve(entry.toString().substring(1)), which is longer than the ZipFile loop.
6. ZipFile vs ZipInputStream vs Zip File System
All three are in the JDK, and the source of the archive mostly decides between them.
| ZipFile | ZipInputStream | Zip file system | |
|---|---|---|---|
| Input | A file on disk | Any InputStream | A file on disk |
| Access | Random, by entry name | Sequential | Random, as Path objects |
| Reads central directory | Yes | No | Yes |
| Zip slip names | Returned as is, check needed | Returned as is, check needed | Archive rejected with ZipException |
| Best for | Extracting files on disk | Uploads and network streams | Reading or replacing single entries |
7. Unzip File using Apache Commons Compress
The JDK covers zip files completely, so a library is optional. Apache Commons Compress is worth adding when the same code must also read tar, tar.gz or 7z archives, or zip features the JDK lacks, such as split archives. Add the dependency, version 1.28.0 at the time of writing.
<dependency>
    <groupId>org.apache.commons</groupId>
    <artifactId>commons-compress</artifactId>
    <version>1.28.0</version>
</dependency>
Since version 1.26, every ArchiveEntry has a resolveIn(Path) method that resolves the entry name against the target folder and throws an IOException when the name escapes it, so the zip slip check is built in.
static void unzipWithCompress(Path zip, Path targetDir) throws IOException {
    Path target = targetDir.toAbsolutePath().normalize();
    try (org.apache.commons.compress.archivers.zip.ZipFile zipFile =
            org.apache.commons.compress.archivers.zip.ZipFile.builder().setPath(zip).get()) {
        for (ZipArchiveEntry entry : Collections.list(zipFile.getEntries())) {
            Path out = entry.resolveIn(target);
            if (entry.isDirectory()) {
                Files.createDirectories(out);
            } else {
                Files.createDirectories(out.getParent());
                try (InputStream in = zipFile.getInputStream(entry)) {
                    Files.copy(in, out, StandardCopyOption.REPLACE_EXISTING);
                }
            }
        }
    }
}
Path target = Files.createTempDirectory("compress");
unzipWithCompress(sampleZip(), target);
boolean logo = Files.exists(target.resolve("docs/img/logo.png")); // trueThe code uses the full class name, because Commons Compress has its own ZipFile class next to java.util.zip.ZipFile. For password-protected archives, neither the JDK nor Commons Compress can decrypt entries, so we use Zip4j instead.
8. Unzip in Java FAQs
Encrypted archives, file names from other systems and lost metadata are the problems that show up once unzip code runs on real files.
8.1. Can Java Unzip a Password-Protected Zip File?
Not with java.util.zip. Opening an archive with encrypted entries throws ZipException: invalid CEN header (encrypted entry). Use the Zip4j library, which supports both AES and the older ZipCrypto encryption, as shown in creating password-protected zip files with Zip4j.
8.2. How Do I Unzip Files with Non-UTF-8 File Names?
Pass the charset of the file names to the constructor, for example new ZipFile(file, Charset.forName(“Cp437”)) or new ZipInputStream(in, Charset.forName(“Cp437”)). Without it, both classes decode names as UTF-8, and a name stored in another charset makes ZipFile throw ZipException: invalid CEN header (bad entry name or comment). Such names are common in zip files made by old Windows tools.
8.3. Does Unzipping Keep File Timestamps and Permissions?
The code in this article does not keep them. Call Files.setLastModifiedTime(out, entry.getLastModifiedTime()) after the copy to keep the timestamp. Unix permissions are stored in a field that java.util.zip does not expose, so use Commons Compress, whose ZipArchiveEntry.getUnixMode() returns them.
8.4. How Do I Unzip a File in Memory Without Writing to Disk?
Read each entry with zipFile.getInputStream(entry).readAllBytes() or zin.readAllBytes() into a byte[], or open the archive as a zip file system and call Files.readString() on the entry. Keep the size limits from section 4, because the whole entry ends up in the heap.
9. Conclusion
Unzipping a file with subdirectories needs only java.util.zip. Use ZipFile for a file on disk and ZipInputStream for a stream, create parent folders for every file and copy with REPLACE_EXISTING so the job can run again.
Treat every archive from outside the app as hostile. Resolve and normalize each entry name, check it with Path.startsWith() against the normalized target, and cap the bytes and entries we extract. The zip file system is handy for reading single entries, and Commons Compress adds other archive formats when the app needs them. The Java IO index puts zip handling next to the guides on reading, writing and copying files.
10. References
- ZipFile Javadoc (Java 25)
- ZipInputStream Javadoc
- Zip File System Provider (jdk.zipfs)
- Snyk, Zip Slip Vulnerability
- SEI CERT IDS04-J, Safely extract files from ZipInputStream
- Apache Commons Compress, ZIP package
Happy Learning !!

This code is insecure and vulnerable to the Zip Slip vulnerability.
https://security.snyk.io/research/zip-slip-vulnerability
This code works absolutely perfect.
But with a huge file, this takes a lot of lots of time. Is there any way to increase the speed.
Hi,
we have a code that decompress the f zip files.
is there anyway to catch the filenames.
example:
i have 1.zip
2.zip
3.zip
1.pdf
4.zip
1.txt
can we catch the path as \1.zip\2.zip\3.zip\1.pdf
\1.zip\2.zip\4.zip\1.txt
for above compressions
for knowing which file belongs to which compression
Excellent Article…
this article saved my ton of time.
Hi, I am running into an issue where I have multiple levels of directories within a zip file. It seems that in some cases the code doesn’t work correctly because I am trying to unzip a file whose directory has not been created yet. The above code seems to have an expectation that the entry that represents the directory will come before any entries for files within that directory, but that does not seem to be the case. Any ideas?
Hi, if i have files in side directory, how can i unzip it, can i take another while loop inside of directory or does it works with your code?
Excelente aporte, gracias por el articulo.
Excellent contribution. Thanks for the article.