

Java reads and writes UTF-8 files through Files.writeString(path, text) and Files.readString(path), which use UTF-8 by default, and through any reader or writer that takes StandardCharsets.UTF_8. Since Java 18, UTF-8 is also the default charset of the JVM, so FileWriter and FileReader without a charset use it too.
We care about the encoding as soon as text contains more than plain English letters, such as names with accents, prices with the euro sign, translated UI texts or CSV files from another system. If the writer and the reader use different charsets, the text comes back with wrong characters or question marks.
The following example writes a cafe menu with accented letters and euro prices, and reads it back in two ways. The Java source uses \u escapes, so the code is the same in any editor.
Path menu = Files.createTempFile("menu", ".txt");
String text = "caf\u00e9 \u20ac3\ncr\u00e8me br\u00fbl\u00e9e \u20ac5\n";

Files.writeString(menu, text, StandardCharsets.UTF_8);
String back = Files.readString(menu, StandardCharsets.UTF_8);
boolean same = back.equals(text);                       // true

int chars = text.length();                              // 24
long bytes = Files.size(menu);                          // 32

List<String> lines = Files.readAllLines(menu, StandardCharsets.UTF_8);
int lineCount = lines.size();                           // 2
Notice that the file has 32 bytes for 24 characters, because UTF-8 uses two bytes for each accented letter and three for the euro sign. We start with how characters become bytes, write and read with the NIO and java.io classes, look at the Java 18 default, and handle broken input, byte order marks and console output.
1. Characters, Bytes and UTF-8
A file stores bytes, whereas a Java String holds characters. A Charset is the rule that maps between the two, and UTF-8 is the rule most systems use today. Writing encodes characters into bytes, and reading decodes bytes back into characters, so the same charset must be used on both sides.
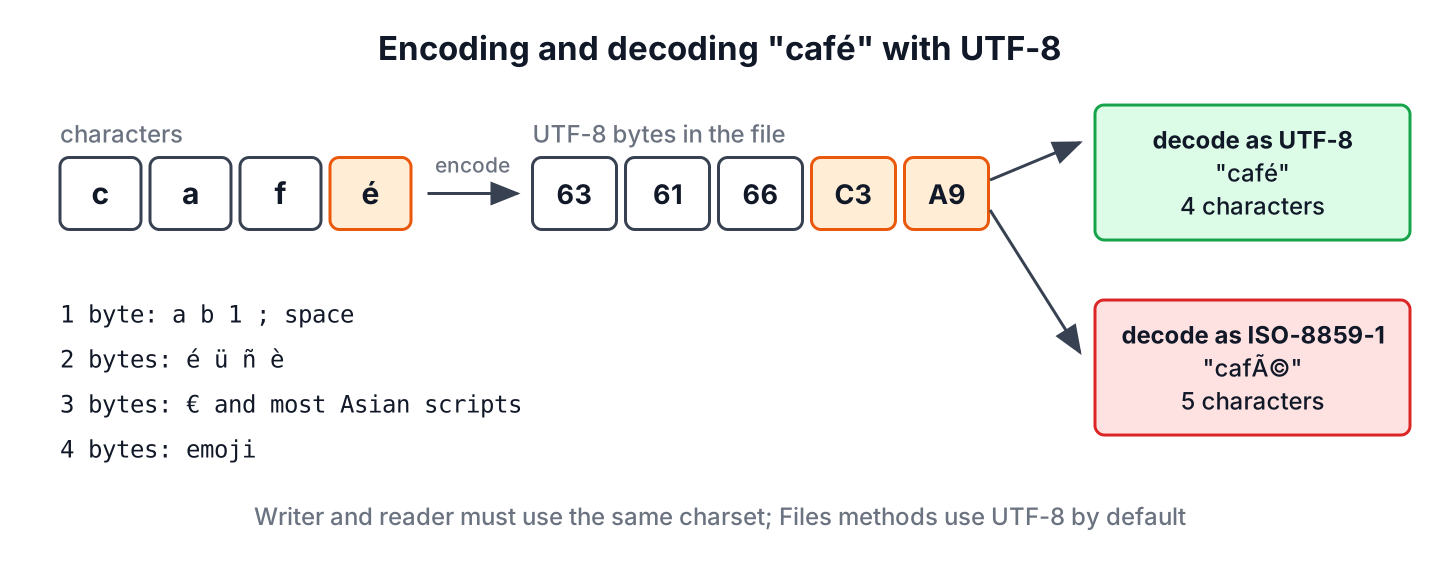
UTF-8 uses a different number of bytes per character. ASCII letters keep their single byte, which is why a plain English file looks the same in UTF-8 and in older charsets.
int ascii = "a".getBytes(StandardCharsets.UTF_8).length;              // 1
int accented = "\u00e9".getBytes(StandardCharsets.UTF_8).length;      // 2
int euro = "\u20ac".getBytes(StandardCharsets.UTF_8).length;          // 3
int emoji = "\uD83D\uDE00".getBytes(StandardCharsets.UTF_8).length;  // 4
int emojiChars = "\uD83D\uDE00".length();                             // 2
The grinning face emoji (U+1F600) takes 4 bytes in the file and 2 char values in the String, because Java stores characters outside the basic range as a pair of char values, so we write it in source as the two escapes \uD83D\uDE00. That is why we never split UTF-8 data at a fixed byte or char position.
2. Writing UTF-8 Data to a File
Every text writer takes a charset, either as a parameter or as a fixed default. The Files methods use UTF-8 when we pass nothing, and we pass StandardCharsets.UTF_8 instead of the string “UTF-8”, because the constant cannot have a typo and the methods that take it do not throw UnsupportedEncodingException.
Path file = Files.createTempFile("menu", ".txt");
String item = "cr\u00e8me br\u00fbl\u00e9e";

Files.writeString(file, item + "\n", StandardCharsets.UTF_8);

Files.write(file, List.of(item, "caf\u00e9"), StandardCharsets.UTF_8);

try (BufferedWriter writer = Files.newBufferedWriter(file, StandardCharsets.UTF_8)) {
    writer.write(item);
    writer.newLine();
}

try (Writer writer = new BufferedWriter(new OutputStreamWriter(new FileOutputStream(file.toFile()), StandardCharsets.UTF_8))) {
    writer.write(item);
}
long size = Files.size(file);   // 15
The last variant is the classic java.io chain, which we still need when an API hands us an OutputStream, such as a servlet response or a ZIP entry. For a File, the constructor FileWriter(File, Charset) (Java 11) is shorter. The guide on writing to a file in Java covers the open options and buffering of these writers.
3. Reading UTF-8 Data From a File
Reading works the same way in reverse. The Files methods decode UTF-8 by default, and the java.io readers take the charset in the constructor.
Path file = Files.createTempFile("menu", ".txt");
Files.writeString(file, "caf\u00e9\ncr\u00e8me br\u00fbl\u00e9e\n");

String all = Files.readString(file);
List<String> lines = Files.readAllLines(file);
int count = lines.size();                                       // 2

try (BufferedReader reader = Files.newBufferedReader(file, StandardCharsets.UTF_8)) {
    String first = reader.readLine();
    boolean match = first.equals("caf\u00e9");                  // true
}

try (BufferedReader reader = new BufferedReader(new InputStreamReader(new FileInputStream(file.toFile()), StandardCharsets.UTF_8))) {
    long items = reader.lines().count();                        // 2
}
The guides on reading a file to a String and reading a file line by line compare these methods for large files.
4. The Default Charset Since Java 18
Many classes have a constructor without a charset, such as FileWriter(File), FileReader(File), Scanner(File) and PrintWriter(File), and String.getBytes() has a variant without one. Up to Java 17, they used the charset of the operating system, which is windows-1252 on many Windows machines and UTF-8 on most Linux and macOS systems. A file written on a Windows laptop could therefore show wrong characters on a Linux server.
Since Java 18, JEP 400 makes UTF-8 the default charset on every platform, and Charset.defaultCharset() returns UTF-8. The Files methods did not change, because they always used UTF-8.
Charset charset = Charset.defaultCharset();                    // UTF-8
String nativeEncoding = System.getProperty("native.encoding");   // the operating system charset, e.g. Cp1252 on Windows
The system property native.encoding (Java 17) keeps the charset of the operating system, for code that must read files written by local tools. Starting the JVM with -Dfile.encoding=COMPAT brings back the pre-18 behavior for an app that depends on it. We still pass StandardCharsets.UTF_8 explicitly in libraries and in code that may run on Java 17 or older, so the result does not depend on the JVM version.
5. When the File Is Not Valid UTF-8
Say an online shop imports a CSV file that an old accounting tool exported in windows-1252. The euro sign and the accented letters are single bytes there, and those bytes are not valid UTF-8 on their own. The Java APIs react to such bytes in two different ways.
Path csv = Files.createTempFile("prices", ".csv");
Files.write(csv, "caf\u00e9;3\n".getBytes(StandardCharsets.ISO_8859_1));

String strict = Files.readString(csv);   // MalformedInputException: Input length = 3

try (BufferedReader reader = new BufferedReader(new InputStreamReader(new FileInputStream(csv.toFile()), StandardCharsets.UTF_8))) {
    String line = reader.readLine();
    boolean replaced = line.contains("\ufffd");                                  // true
}

String decoded = Files.readString(csv, StandardCharsets.ISO_8859_1);
boolean correct = decoded.equals("caf\u00e9;3\n");                              // true
The Files methods throw a MalformedInputException, whereas the InputStreamReader, FileReader and Scanner replace every broken sequence with the character U+FFFD, which editors show as a question mark in a diamond. The strict behavior is safer, because it stops the import instead of saving damaged names to the database. Once we know the real charset, we read the file with it and write it back as UTF-8.
The same split exists for writing. When the target charset cannot represent a character, Files.writeString() throws an UnmappableCharacterException, whereas FileWriter, OutputStreamWriter and getBytes() write a ? instead.
Path file = Files.createTempFile("price", ".txt");

Path strictWrite = Files.writeString(file, "\u20ac5", StandardCharsets.US_ASCII);   // UnmappableCharacterException: Input length = 1

byte[] lossy = "\u20ac5".getBytes(StandardCharsets.US_ASCII);
String stored = new String(lossy, StandardCharsets.US_ASCII);                      // "?5"
6. The UTF-8 Byte Order Mark
Some Windows tools put the three bytes EF BB BF, called a byte order mark (BOM), at the start of a UTF-8 file. Java never writes a BOM, and when it reads one, it does not remove it, so the first line starts with the invisible character \uFEFF. As a result, a header check such as line.startsWith(“id”) fails on the first line of a CSV file.
Path csv = Files.createTempFile("export", ".csv");
Files.write(csv, new byte[] {(byte) 0xEF, (byte) 0xBB, (byte) 0xBF, 'i', 'd', '\n', '1', '\n'});

String header = Files.readAllLines(csv).get(0);
boolean looksRight = header.startsWith("id");                    // false
String cleaned = header.replace("\ufeff", "");
boolean fixed = cleaned.equals("id");                            // true
The other direction matters too. Excel on Windows opens a double-clicked UTF-8 CSV file without a BOM in the local charset, so accented letters look broken. When the file is meant for Excel users, we write \uFEFF as the first character, and Excel detects UTF-8.
Path csv = Files.createTempFile("excel", ".csv");
Files.writeString(csv, "\ufeffitem;price\ncaf\u00e9;3\n", StandardCharsets.UTF_8);
long size = Files.size(csv);   // 22
7. Printing UTF-8 Text to the Console
When the file is correct but the console shows question marks, the problem is the console, not the file. Since Java 19, System.out encodes text with the charset in the system property stdout.encoding, which matches the terminal and is often not UTF-8 on Windows.
On Windows, we switch the terminal to UTF-8 with the command chcp 65001 and start Java with -Dstdout.encoding=UTF-8. In an IDE, the console encoding is a setting of the run configuration. To check the file itself, we compare the decoded String in code, as the examples above do, instead of trusting the console.
8. Reading and Writing UTF-8 Files FAQs
Garbled names after an import and question marks in a log are where most of these questions begin.
8.1. Is the Default Encoding in Java UTF-8?
Yes, since Java 18. Charset.defaultCharset() returns UTF-8 on every platform unless the JVM starts with -Dfile.encoding=COMPAT. Before Java 18, it was the charset of the operating system, and the Files methods used UTF-8 in every version, as described in section 4.
8.2. How Do I Convert a File From ISO-8859-1 to UTF-8?
We read the file with the old charset and write it with UTF-8. For large files, we stream it with a reader and a writer instead of loading it into a String.
Path latin1 = Files.createTempFile("old", ".txt");
Files.write(latin1, "caf\u00e9\n".getBytes(StandardCharsets.ISO_8859_1));
Path utf8 = Files.createTempFile("new", ".txt");

try (BufferedReader in = Files.newBufferedReader(latin1, StandardCharsets.ISO_8859_1);
     BufferedWriter out = Files.newBufferedWriter(utf8, StandardCharsets.UTF_8)) {
    in.transferTo(out);
}
long oldSize = Files.size(latin1);   // 5
long newSize = Files.size(utf8);     // 6
8.3. Why Do I See Question Marks Instead of Special Characters?
A question mark means that one step used a charset that cannot represent the character. Either the writer encoded with a charset such as US-ASCII, which writes a ? into the file, or the console cannot show the character. We check the bytes in the file with Files.readAllBytes(), or compare the decoded string in code, to find out which step it was.
8.4. Can DataOutputStream.writeUTF() Write a UTF-8 Text File?
No. The method writeUTF() writes a 2-byte length followed by a modified form of UTF-8, so the file starts with two extra bytes that a text editor shows as garbage. It is meant for DataInputStream.readUTF() only.
Path file = Files.createTempFile("data", ".bin");
try (DataOutputStream out = new DataOutputStream(Files.newOutputStream(file))) {
    out.writeUTF("caf\u00e9");
}
long size = Files.size(file);   // 7
8.5. How Can I Check Whether a File Is Valid UTF-8?
We read it with Files.readString(path) and catch the MalformedInputException. The method decodes the whole file strictly, so no exception means every byte sequence is valid UTF-8. For large files, a Files.newBufferedReader() loop does the same check line by line without holding the file in memory.
9. Conclusion
Reading and writing UTF-8 files in Java is safe when both sides agree on the charset. The Files methods use UTF-8 by default, and every java.io reader and writer accepts StandardCharsets.UTF_8. Since Java 18, the JVM default is UTF-8 as well, but an explicit charset keeps the code correct on older versions.
When something goes wrong, the Files methods throw, whereas the older readers and writers replace characters without a warning. Files from other tools may use another charset or start with a BOM, and question marks on screen often come from the console rather than the file. The Java IO guide lists the other file tasks.
10. References
- JEP 400: UTF-8 by Default
- Charset Javadoc
- StandardCharsets Javadoc
- Files Javadoc (Java 25)
- DataOutputStream.writeUTF() Javadoc
Happy Learning !!

instead of giving output क्षेत्रफल = लंबाई * चौड़ाई it is giving ????=???? * ???. how to overcome this error?
Follow the instruction giver here.
Hi Lokesh,
My question is somewhat different from this post.
How to escape accented characters(it may include UTF-8, UTF-16…) apart from using apache commans.lang library.
Thanks in advance.
Regards,
Normalizer.normalize(string, Normalizer.Form.NFD);
Read more: https://stackoverflow.com/questions/3322152/is-there-a-way-to-get-rid-of-accents-and-convert-a-whole-string-to-regular-lette