
The Collectors.groupingBy() method groups the elements of a Java Stream into a Map. Each key is a value taken from the element, such as a department, and each map value holds all the elements with that key. The Java stream groupingBy operation does the same job as the GROUP BY clause in SQL.
We use groupingBy() when a list holds many objects and we want them split into buckets, such as employees by department or orders by status. A second collector, called the downstream collector, turns each bucket into a count, a sum, an average or the biggest element.
The following example groups a list of employees by department and shows the three forms we use most often.
Map<String, List<Employee>> byDept = employees.stream().collect(groupingBy(Employee::department));                      // {Finance=[Employee[name=Charles, ...], ...], HR=[...], Admin=[...]}
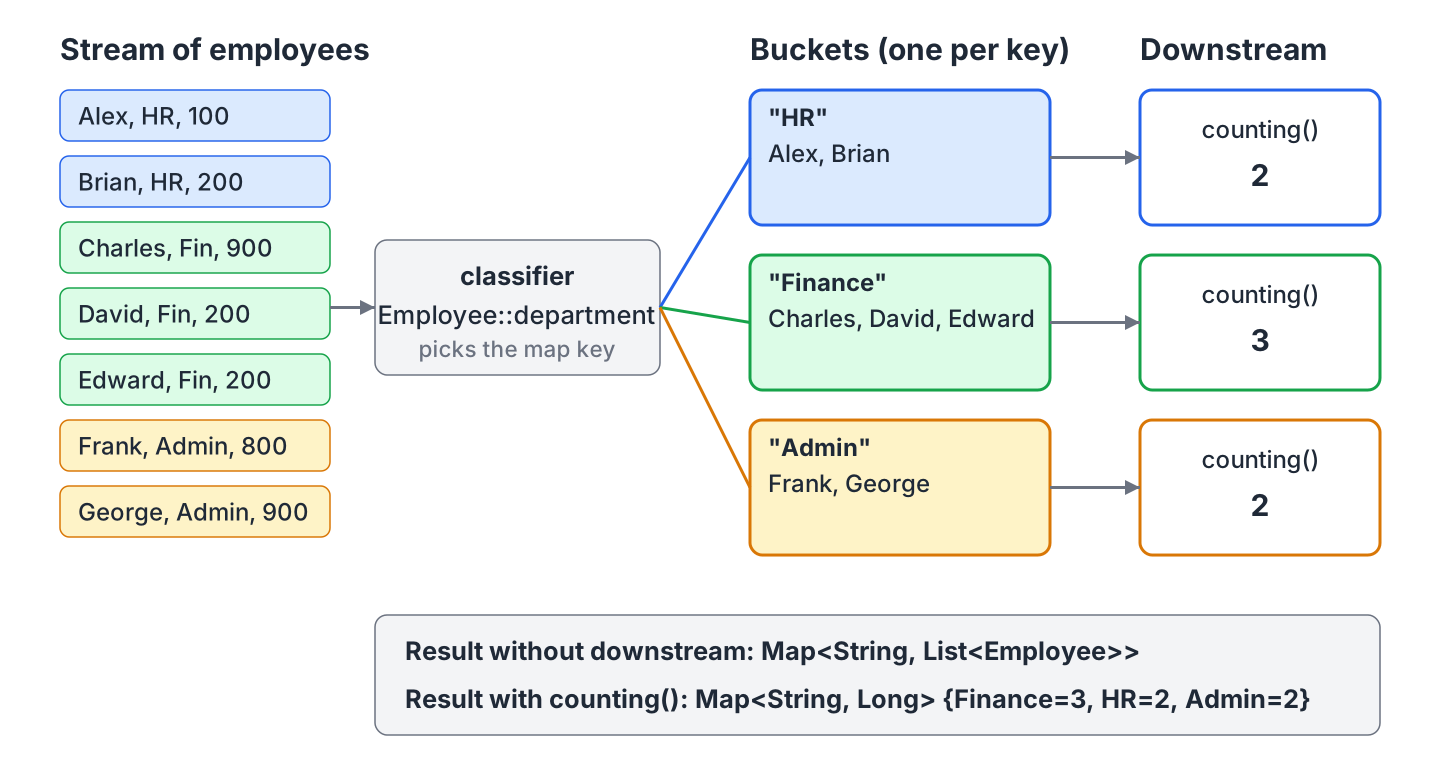
Map<String, Long> countByDept = employees.stream().collect(groupingBy(Employee::department, counting()));                     // {Finance=3, HR=2, Admin=2}
Map<String, Integer> totalByDept = employees.stream().collect(groupingBy(Employee::department, summingInt(Employee::salary))); // {Finance=1300, HR=300, Admin=1700}
Notice that the first argument always picks the map key, and the optional second argument decides what each map value becomes. We go on to aggregate each group, group by two fields, choose the map type, sort the result, compare groupingBy() with partitioningBy() and build a monthly sales report.
1. How groupingBy() Builds the Map
The groupingBy() method returns a Collector, which is an object that Stream.collect() uses to build a result from the stream elements. For every element, the collector calls a function that we pass in, called the classifier, and uses the returned value as the map key. Elements with the same key go into the same bucket.
Each bucket goes to a downstream collector, which turns the bucket into the map value. By default that collector is Collectors.toList(), so the value is a List of the elements. With counting() instead, the value is the number of elements in the bucket.
The groupingBy() method has three overloads. Each one adds one argument to the previous one.
| Overload | Result | Map type |
|---|---|---|
| groupingBy(classifier) | Map<K, List<T>> | HashMap in practice |
| groupingBy(classifier, downstream) | Map<K, D>, where D is the result of the downstream collector | HashMap in practice |
| groupingBy(classifier, mapFactory, downstream) | Map<K, D> | The map that mapFactory creates |
Each argument has one job in the grouping.
- The classifier is a Function that maps an element to its key, for example Employee::department.
- The downstream collector reduces one bucket to the map value. Any collector from the Collectors class works here, including another groupingBy().
- The mapFactory is a Supplier that creates the empty result map, such as TreeMap::new. Without it, the type of the map is not guaranteed, but in practice we get a HashMap.
The result map has no defined iteration order, so two runs can print the groups in a different order. When the order matters, we pass a map factory as shown in section 5.
2. The Example Data
The following example is a list of employees, each with a name, a department, a city and a salary. A record keeps the class short, and its accessor methods such as Employee::department work as classifiers. We keep the list in a constant of the class, so every snippet can use it.
record Employee(String name, String department, String city, int salary) {}

static final List<Employee> employees = List.of(
    new Employee("Alex", "HR", "Delhi", 100),
    new Employee("Brian", "HR", "Pune", 200),
    new Employee("Charles", "Finance", "Delhi", 900),
    new Employee("David", "Finance", "Delhi", 200),
    new Employee("Edward", "Finance", "Pune", 200),
    new Employee("Frank", "Admin", "Pune", 800),
    new Employee("George", "Admin", "Delhi", 900));
The snippets call the collectors without the Collectors. prefix, which needs one static import at the top of the file.
import static java.util.stream.Collectors.*;The examples run on JDK 25. Most collectors exist since Java 8, and filtering() and flatMapping() came in Java 9.
3. Grouping Into Lists
The one-argument call groups the employees by department and keeps whole Employee objects in each list. The lists keep the order in which the elements appeared in the stream.
Map<String, List<Employee>> byDept = employees.stream().collect(groupingBy(Employee::department)); // one list of employees per department{Finance=[Employee[name=Charles, department=Finance, city=Delhi, salary=900], Employee[name=David, ...], Employee[name=Edward, ...]],
HR=[Employee[name=Alex, ...], Employee[name=Brian, ...]],
Admin=[Employee[name=Frank, ...], Employee[name=George, ...]]}Often we need only one field in the list, such as the name. The Collectors.mapping() collector applies a function to each element before the downstream collector stores it, so the map value becomes a List<String>. With toSet() as the last collector we drop duplicates, and with joining() we get one joined string per group.
Map<String, List<String>> namesByDept = employees.stream().collect(groupingBy(Employee::department, mapping(Employee::name, toList())));   // {Finance=[Charles, David, Edward], HR=[Alex, Brian], Admin=[Frank, George]}
Map<String, Set<String>> deptsByCity = employees.stream().collect(groupingBy(Employee::city, mapping(Employee::department, toSet())));        // {Delhi=[Finance, HR, Admin], Pune=[Finance, HR, Admin]}
Map<String, String> joinedByDept = employees.stream().collect(groupingBy(Employee::department, mapping(Employee::name, joining(", "))));     // {Finance=Charles, David, Edward, HR=Alex, Brian, Admin=Frank, George}
4. Aggregating Each Group
In most reports we want one number per group, such as how many employees a department has or what it pays in total. We get that number by replacing toList() with an aggregating downstream collector.
| Collector | Map value type | What it gives per group |
|---|---|---|
| counting() | Long | The number of elements |
| summingInt(f), summingLong(f), summingDouble(f) | Integer, Long, Double | The sum of the mapped values |
| averagingInt(f), averagingDouble(f) | Double | The arithmetic mean, 0.0 for an empty group |
| maxBy(comparator), minBy(comparator) | Optional<T> | The largest or smallest element |
| summarizingInt(f) | IntSummaryStatistics | Count, sum, min, average and max in one pass |
| filtering(predicate, downstream) | Depends on downstream | Drops elements that fail the test but keeps the key |
| reducing(identity, mapper, op) | The type of identity | A custom fold, for example a BigDecimal sum |
4.1. Counting
The counting() collector returns a Long for each key, and the classifier can be any field, so the same call can count employees per city or per salary.
Map<String, Long> countByDept = employees.stream().collect(groupingBy(Employee::department, counting()));   // {Finance=3, HR=2, Admin=2}
Map<String, Long> countByCity = employees.stream().collect(groupingBy(Employee::city, counting()));         // {Delhi=4, Pune=3}
4.2. Sum and Average
The summingInt() collector takes a function that returns an int for each element and adds the values up. The averagingDouble() collector returns a Double even when the field is an int, because the mean is rarely a whole number.
Map<String, Integer> totalByDept = employees.stream().collect(groupingBy(Employee::department, summingInt(Employee::salary)));          // {Finance=1300, HR=300, Admin=1700}
Map<String, Double> averageByDept = employees.stream().collect(groupingBy(Employee::department, averagingDouble(Employee::salary)));   // {Finance=433.3333333333333, HR=150.0, Admin=850.0}
4.3. Maximum With maxBy() and Optional
The maxBy() collector takes a Comparator and returns the largest element of each group. The result is wrapped in an Optional, because a group can be empty when maxBy() is combined with filtering().
Map<String, Optional<Employee>> topByDept = employees.stream().collect(groupingBy(Employee::department, maxBy(Comparator.comparingInt(Employee::salary)))); // {Finance=Optional[Employee[name=Charles, ...]], HR=Optional[Employee[name=Brian, ...]], Admin=Optional[Employee[name=George, ...]]}To remove the Optional in the map value, we wrap maxBy() in collectingAndThen(). The second argument is a function that runs once per group on the finished Optional, so we can unwrap it and pick the field we want.
Map<String, String> topNameByDept = employees.stream()
    .collect(groupingBy(Employee::department,
        collectingAndThen(maxBy(Comparator.comparingInt(Employee::salary)),
            best -> best.map(Employee::name).orElse("none"))));   // {Finance=Charles, HR=Brian, Admin=George}
Two employees of one department can share the top salary. In that case maxBy() keeps the first one it saw in the stream, because it replaces the current maximum only with a strictly larger element.
4.4. Filtering Inside a Group
When we call Stream.filter() before groupingBy(), a department with no matching employee disappears from the map. No element with that key reaches the collector, so the key is never created. The filtering() collector applies the test inside the group instead. Every department stays in the map, and the empty ones get a count of zero.
Map<String, Long> above300Filtered = employees.stream().filter(e -> e.salary() > 300).collect(groupingBy(Employee::department, counting()));   // {Finance=1, Admin=2}
Map<String, Long> above300AllKeys = employees.stream().collect(groupingBy(Employee::department, filtering(e -> e.salary() > 300, counting())));   // {Finance=1, HR=0, Admin=2}
4.5. All Statistics in One Pass
A salary report often needs the count, the total, the lowest, the highest and the average for each department. The summarizingInt() collector computes all five in one pass and stores them in an IntSummaryStatistics object, so we do not stream the list five times.
Map<String, IntSummaryStatistics> statsByDept = employees.stream().collect(groupingBy(Employee::department, summarizingInt(Employee::salary)));
IntSummaryStatistics finance = statsByDept.get("Finance");
long financeCount = finance.getCount();        // 3
int financeMax = finance.getMax();             // 900
double financeAverage = finance.getAverage();  // 433.3333333333333
5. Choosing the Map Type (TreeMap and LinkedHashMap)
The third overload takes a map factory. With TreeMap::new the keys come out sorted. With LinkedHashMap::new the groups keep the order in which their first element appeared in the stream. The downstream collector is required in this overload, so we pass toList() when we want lists.
TreeMap<String, Long> sortedByDept = employees.stream().collect(groupingBy(Employee::department, TreeMap::new, counting()));            // {Admin=2, Finance=3, HR=2}
LinkedHashMap<String, Long> inInputOrder = employees.stream().collect(groupingBy(Employee::department, LinkedHashMap::new, counting()));   // {HR=2, Finance=3, Admin=2}
TreeMap<String, List<String>> namesSorted = employees.stream().collect(groupingBy(Employee::department, TreeMap::new, mapping(Employee::name, toList())));   // {Admin=[Frank, George], Finance=[Charles, David, Edward], HR=[Alex, Brian]}
Notice that the variable types can be TreeMap and LinkedHashMap here, because the compiler infers the map type from the factory. When the keys are enum constants, () -> new EnumMap<>(Status.class) gives an EnumMap, which is compact and keeps the keys in declaration order.
6. Grouping by Multiple Fields
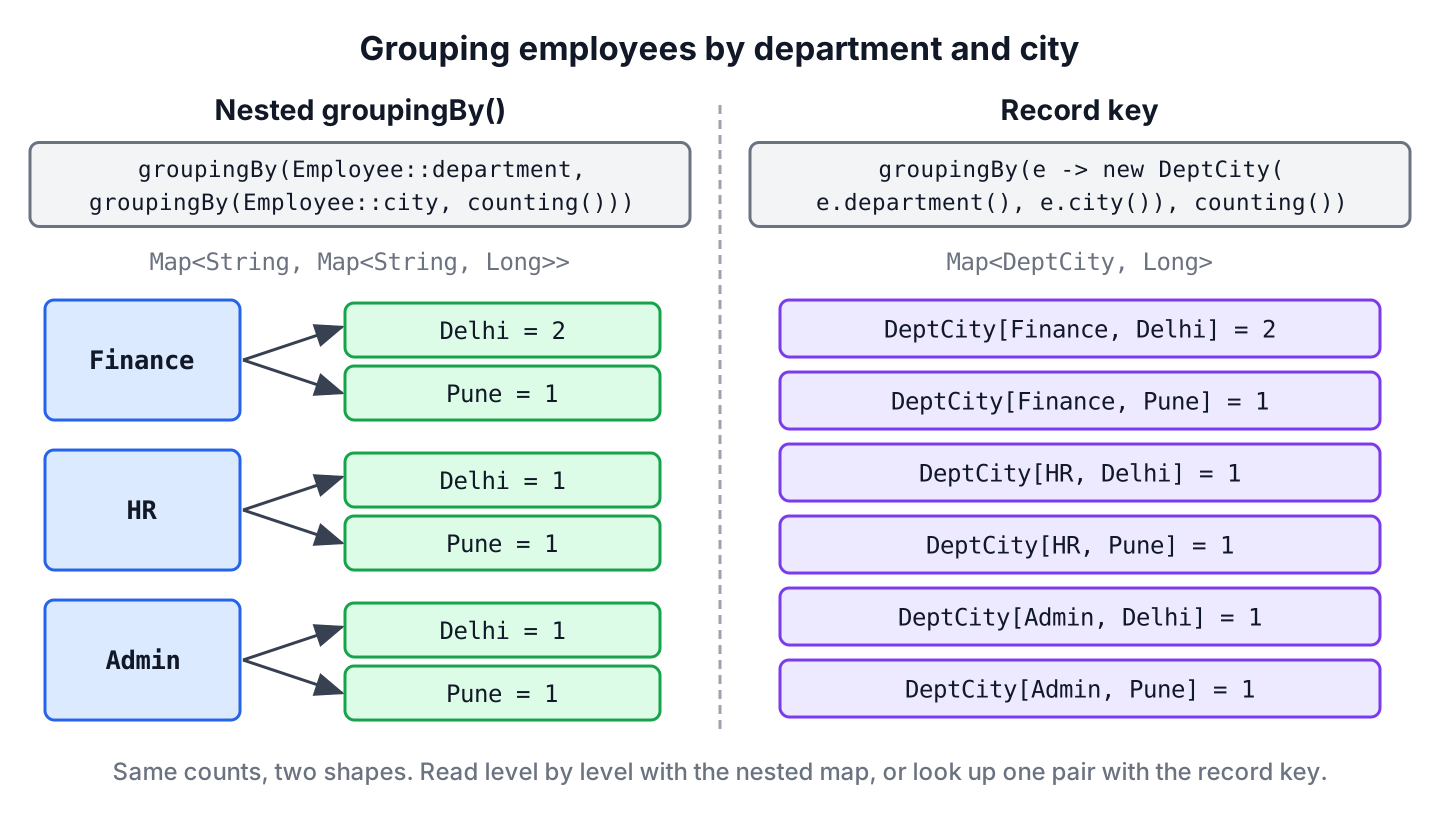
The SQL form GROUP BY department, city has two equivalents in streams. The first nests one groupingBy() inside another, which gives a map of maps. The outer key is the department, the inner key is the city, and the innermost value is whatever the last downstream collector produces.
Map<String, Map<String, List<String>>> byDeptThenCity = employees.stream()
    .collect(groupingBy(Employee::department,
        groupingBy(Employee::city, mapping(Employee::name, toList()))));   // {Finance={Delhi=[Charles, David], Pune=[Edward]}, HR={Delhi=[Alex], Pune=[Brian]}, Admin={Delhi=[George], Pune=[Frank]}}
The second way builds a single key from both fields. A record is the right key type. Records get equals() and hashCode() from their fields, and HashMap needs both to find the bucket. The result is a flat map, which is easier to loop over and to sort.
record DeptCity(String department, String city) {}Map<DeptCity, Long> countByDeptCity = employees.stream().collect(groupingBy(e -> new DeptCity(e.department(), e.city()), counting()));
long financeDelhi = countByDeptCity.get(new DeptCity("Finance", "Delhi")); // 2
int groups = countByDeptCity.size(); // 6We pick the nested form when the code reads the result level by level, such as a report with a heading per department. The record key fits better when we look up one combination at a time, as the financeDelhi line does.
7. Sorting the Grouped Result
A TreeMap sorts by key only. To order the groups by value, for example the highest total salary first, we stream the entries of the finished map and sort them. We collect the sorted entries into a LinkedHashMap, so the order is kept. The last step uses Collectors.toMap() with a map factory.
Map<String, Integer> totalByDept = employees.stream().collect(groupingBy(Employee::department, summingInt(Employee::salary)));
LinkedHashMap<String, Integer> highestTotalFirst = totalByDept.entrySet().stream()
    .sorted(Map.Entry.<String, Integer>comparingByValue().reversed())
    .collect(toMap(Map.Entry::getKey, Map.Entry::getValue, (a, b) -> a, LinkedHashMap::new));   // {Admin=1700, Finance=1300, HR=300}
The third argument of toMap() is a merge function for duplicate keys. It is never called here, but the overload with a map factory requires it. The same entry stream also gives us the SQL HAVING clause, because a filter() on the entries keeps only the groups we want.
Map<String, Long> bigDepartments = employees.stream().collect(groupingBy(Employee::department, counting()))
    .entrySet().stream().filter(entry -> entry.getValue() > 2)
    .collect(toMap(Map.Entry::getKey, Map.Entry::getValue));   // {Finance=3}
8. Comparing groupingBy() and partitioningBy()
The partitioningBy() collector is groupingBy() with a yes/no test (a Predicate) as the classifier, so the map has only two keys, true and false. Unlike groupingBy(), it always creates both keys, even when no element matches one side. The same downstream collectors work with it.
Map<Boolean, List<String>> highEarners = employees.stream().collect(partitioningBy(e -> e.salary() > 500, mapping(Employee::name, toList())));       // {false=[Alex, Brian, David, Edward], true=[Charles, Frank, George]}
Map<Boolean, List<String>> nobodyAbove1000 = employees.stream().collect(partitioningBy(e -> e.salary() > 1000, mapping(Employee::name, toList())));  // {false=[Alex, Brian, Charles, David, Edward, Frank, George], true=[]}
Map<Boolean, List<String>> groupedAbove1000 = employees.stream().collect(groupingBy(e -> e.salary() > 1000, mapping(Employee::name, toList())));     // {false=[Alex, Brian, Charles, David, Edward, Frank, George]}
We can see in the last line that groupingBy() with the same test returns only the false key. So we pick partitioningBy() for a yes/no split that must have both sides, and groupingBy() for every other key.
9. Parallel Streams With groupingByConcurrent()
The groupingByConcurrent() collector has the same three overloads and returns a ConcurrentMap. All threads of a parallel stream insert into that one map at the same time, so it can be faster than groupingBy() on a large parallel stream. The order of the elements inside each group is not guaranteed, so we use it only when that order does not matter.
ConcurrentMap<String, Long> concurrentCount = employees.parallelStream().collect(groupingByConcurrent(Employee::department, counting())); // {Finance=3, HR=2, Admin=2}10. SQL GROUP BY vs Stream groupingBy()
In SQL the aggregate functions are in the SELECT list, whereas in a stream they are the downstream collector. The HAVING clause becomes a filter on the entries of the finished map, as section 7 showed.
| SQL | Stream |
|---|---|
| GROUP BY department | groupingBy(Employee::department) |
| COUNT(*) | counting() |
| SUM(salary) | summingInt(Employee::salary) |
| AVG(salary) | averagingDouble(Employee::salary) |
| MAX(salary) | maxBy(Comparator.comparingInt(Employee::salary)) |
| GROUP BY department, city | groupingBy(Employee::department, groupingBy(Employee::city)) or a record key |
| WHERE salary > 300 | filter(e -> e.salary() > 300) before collect() |
| HAVING COUNT(*) > 2 | filter() on map.entrySet().stream() after collecting |
| ORDER BY department | groupingBy(…, TreeMap::new, …) |
11. Building a Monthly Sales Report With Java Stream groupingBy
An online bakery stores every order with its date and its amount as a BigDecimal. The owner wants a page that lists each month with its revenue and its number of orders, oldest month first. Money must not be summed as double, because binary floating-point values add rounding errors to cents.
record Order(LocalDate date, BigDecimal amount) {}The classifier turns each date into a YearMonth, and TreeMap::new sorts the months. The reducing() collector adds the amounts with BigDecimal::add, starting from BigDecimal.ZERO, so a month with one order still gets a correct total.
List<Order> orders = List.of(
    new Order(LocalDate.of(2026, 9, 3), new BigDecimal("12.50")),
    new Order(LocalDate.of(2026, 9, 21), new BigDecimal("7.25")),
    new Order(LocalDate.of(2026, 10, 2), new BigDecimal("30.00")));
TreeMap<YearMonth, BigDecimal> revenueByMonth = orders.stream()
    .collect(groupingBy(o -> YearMonth.from(o.date()), TreeMap::new, reducing(BigDecimal.ZERO, Order::amount, BigDecimal::add)));   // {2026-09=19.75, 2026-10=30.00}
TreeMap<YearMonth, Long> ordersByMonth = orders.stream().collect(groupingBy(o -> YearMonth.from(o.date()), TreeMap::new, counting()));   // {2026-09=2, 2026-10=1}
The two maps share the same keys in the same order, so the page loops over revenueByMonth and reads the count from ordersByMonth. For a few thousand orders the two passes over the list are cheap. With millions of rows, the grouping belongs in the SQL query instead.
12. Collectors groupingBy FAQs
The same questions about grouping come up in code reviews and in searches, mostly about keys, order and the type of the result.
12.1. Can groupingBy() Handle a null Key?
No. When the classifier returns null, groupingBy() throws a NullPointerException with the message “element cannot be mapped to a null key”. We map a missing value to a real key in the classifier, such as “Unknown”.
Map<String, Long> crash = Stream.of("Delhi", null).collect(groupingBy(city -> city, counting()));                                // NullPointerException: element cannot be mapped to a null key
Map<String, Long> safe = Stream.of("Delhi", null).collect(groupingBy(city -> Objects.requireNonNullElse(city, "Unknown"), counting()));   // {Delhi=1, Unknown=1}
12.2. Does groupingBy() Keep the Order of the Elements?
Yes, inside each group. The list for a key holds the elements in the order the stream produced them. The order of the keys is not defined for the default map, so we pass LinkedHashMap::new for the first-seen order or TreeMap::new for sorted keys.
12.3. What Is the Difference Between groupingBy() and toMap()?
The groupingBy() collector keeps every element for a key, whereas toMap() keeps one value per key and throws IllegalStateException on a duplicate key unless we pass a merge function. When each key appears once, such as an id, toMap() gives the simpler map.
12.4. Is the Map Returned by groupingBy() Modifiable?
In the current JDK, yes, because it is a HashMap with ArrayList values, but the API does not promise that. Code that changes the result passes a map factory and toCollection(ArrayList::new), or wraps the result with collectingAndThen(…, Map::copyOf) when it must stay read-only.
12.5. How Do We Group by a Value That Each Element Has Several Of?
We flatten the values first, so each element appears in the group of every value it has. For example, a developer with two skills belongs to both skill groups. The flatMap() call turns each developer into one entry per skill, and groupingBy() groups the entries by skill.
record Dev(String name, List<String> skills) {}List<Dev> devs = List.of(new Dev("Ann", List.of("java", "sql")), new Dev("Bob", List.of("java")));
Map<String, List<String>> devsBySkill = devs.stream()
.flatMap(d -> d.skills().stream().map(skill -> Map.entry(skill, d.name())))
.collect(groupingBy(Map.Entry::getKey, TreeMap::new, mapping(Map.Entry::getValue, toList()))); // {java=[Ann, Bob], sql=[Ann]}13. Conclusion
The groupingBy() collector turns a stream into a Map in one call. The classifier picks the key, and the downstream collector decides whether each value is a list, a count, a sum, an average, a statistics object or the largest element.
For two levels we nest a groupingBy() or group by a record key, and for a yes/no split we use partitioningBy() so both keys are always present. A map factory such as TreeMap::new sorts the keys, and sorting by value happens on the entries of the finished map.
14. References
- Collectors Javadoc (JDK 25)
- Collector interface Javadoc
- java.util.stream package summary
- IntSummaryStatistics Javadoc
Happy Learning !!

Great help for me
Glad, it helped.
Thanks for helpful post
Please include groupingByConcurrent also.
Its already mentioned. Highlighted a little more in a separate heading.