
To find a file in a directory and its subdirectories in Java, call Files.find() with the start folder, a maximum depth and a condition on the path and its attributes, and collect the matching paths from the returned stream. The method searches the whole tree and returns every file whose name matches, including files with the same name in different subfolders.
We need a recursive file search to locate a config file inside a project, to pick up every invoice.pdf from an extracted archive or to check whether a report already exists before we generate it again.
The following example searches a small project folder for every file named README.md.
Path root = Files.createTempDirectory("project");
Files.createDirectories(root.resolve("docs/old"));
Files.writeString(root.resolve("README.md"), "top");
Files.writeString(root.resolve("docs/old/README.md"), "old");
Files.writeString(root.resolve("docs/guide.pdf"), "pdf");
List<Path> found;
try (Stream<Path> matches = Files.find(root, Integer.MAX_VALUE,
        (path, attrs) -> attrs.isRegularFile() && path.getFileName().toString().equals("README.md"))) {
    found = matches.map(root::relativize).sorted().toList();
}
String result = found.toString();               // "[README.md, docs/old/README.md]"
Notice that we compare getFileName(), not the whole path string, and that the stream is closed by try-with-resources. We cover Files.find() and Files.walk(), stopping at the first match, depth limits, glob patterns, case-insensitive names, folders we cannot read and the classic recursive version with java.io.File.
1. Find a File in a Directory Tree with Files.find()
The Files.find(start, maxDepth, matcher, options) method walks the tree below start and calls the matcher, a BiPredicate<Path, BasicFileAttributes>, for every entry. The attributes are read once during the walk, so checks such as isRegularFile(), size() or lastModifiedTime() cost no extra file system call.
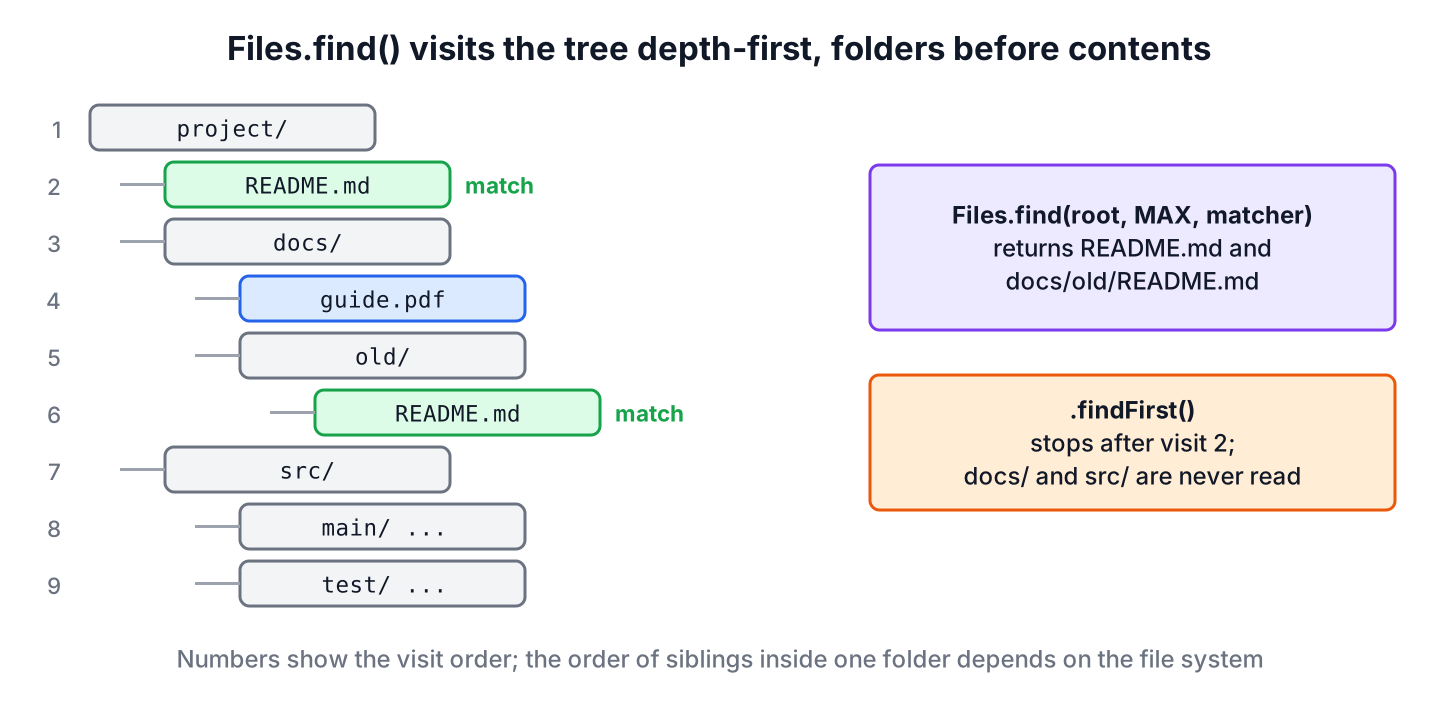
The examples use one sample project tree with two README.md files, Java sources in two folders and a PDF.
static Path projectTree() throws IOException {
    Path root = Files.createTempDirectory("project");
    Files.createDirectories(root.resolve("src/main"));
    Files.createDirectories(root.resolve("src/test"));
    Files.createDirectories(root.resolve("docs/old"));
    Files.writeString(root.resolve("README.md"), "top");
    Files.writeString(root.resolve("src/main/App.java"), "class App {}");
    Files.writeString(root.resolve("src/test/AppTest.java"), "class AppTest {}");
    Files.writeString(root.resolve("docs/guide.pdf"), "a".repeat(3_000));
    Files.writeString(root.resolve("docs/old/README.md"), "old");
    return root;
}
Because the matcher gets the attributes, one call can combine a name rule with a size rule. For example, one call returns the files larger than 1 KB anywhere in the tree.
Path root = projectTree();
List<String> large;
try (Stream<Path> s = Files.find(root, Integer.MAX_VALUE,
        (p, attrs) -> attrs.isRegularFile() && attrs.size() > 1_024)) {
    large = s.map(p -> p.getFileName().toString()).toList();
}
String result = large.toString();                // "[guide.pdf]"
A support tool is a typical case. Say a customer uploads a diagnostics bundle with hundreds of folders, and the tool needs the file thread-dump.txt wherever it ended up. One Files.find() call with a name check returns it, and the attribute check skips folders that have the same name.
2. Find File by Walking the Directories
The Files.walk() method returns a lazy Stream<Path> of every entry in the tree, and we filter it with the usual stream operations. It does the same walk as Files.find(), but the filter has to read attributes again, for example with Files.isRegularFile().
The walk is depth-first in pre-order, so each directory comes before its contents and the start folder is the first element. Files in the deepest folders are not searched first, and the order of siblings inside one folder is not specified.
Path root = projectTree();
List<String> javaFiles;
try (Stream<Path> walk = Files.walk(root)) {
    javaFiles = walk.filter(Files::isRegularFile)
            .map(p -> p.getFileName().toString())
            .filter(name -> name.endsWith(".java"))
            .sorted()
            .toList();
}
String result = javaFiles.toString();            // "[App.java, AppTest.java]"
2.1. Limiting the Search Depth
Both methods take a maxDepth argument. Depth 0 is the start folder itself, depth 1 adds its direct children, and so on, so a depth of 1 searches one folder without going into subfolders.
Path root = projectTree();
BiPredicate<Path, BasicFileAttributes> readme = (p, a) -> p.getFileName().toString().equals("README.md");
long topLevel;
long upToThree;
try (Stream<Path> s = Files.find(root, 1, readme)) {
    topLevel = s.count();
}
try (Stream<Path> s = Files.find(root, 3, readme)) {
    upToThree = s.count();
}
long depthOne = topLevel;                        // 1 (docs/old/README.md is at depth 3)
long depthThree = upToThree;                     // 2
2.2. Stopping after the First Match
When one match is enough, findFirst() returns an Optional and stops the walk, so the rest of the tree is never read. That matters on a network drive or a folder with millions of files.
Path root = projectTree();
Optional<Path> pdf;
try (Stream<Path> s = Files.find(root, Integer.MAX_VALUE,
        (p, a) -> a.isRegularFile() && p.getFileName().toString().endsWith(".pdf"))) {
    pdf = s.findFirst();
}
String name = pdf.map(p -> p.getFileName().toString()).orElse("not found");   // "guide.pdf"
The first match depends on the walk order, which depends on the file system. When several files can match and one of them must win, collect all matches and pick one by a rule, such as the shortest path or the newest file.
3. Matching Names with Glob Patterns
A PathMatcher turns a glob such as *.{java,kt} into a reusable matcher. A pattern without a slash must be matched against getFileName(), while a pattern with ** can match a path relative to the start folder, which lets us search inside a named subfolder.
Path root = projectTree();
PathMatcher sources = FileSystems.getDefault().getPathMatcher("glob:*.{java,kt}");
PathMatcher testsOnly = FileSystems.getDefault().getPathMatcher("glob:src/test/**");
List<String> all;
try (Stream<Path> s = Files.find(root, Integer.MAX_VALUE, (p, a) -> sources.matches(p.getFileName()))) {
    all = s.map(p -> p.getFileName().toString()).sorted().toList();
}
List<String> tests;
try (Stream<Path> s = Files.find(root, Integer.MAX_VALUE,
        (p, a) -> a.isRegularFile() && testsOnly.matches(root.relativize(p)))) {
    tests = s.map(p -> p.getFileName().toString()).toList();
}
String allSources = all.toString();              // "[App.java, AppTest.java]"
String testSources = tests.toString();           // "[AppTest.java]"
For name rules inside a single folder, the FilenameFilter guide shows the same glob syntax with Files.newDirectoryStream().
4. Case-Insensitive File Search
A file named Readme.MD does not equal README.md, and Linux keeps both as different files. When users type the name to search for, compare with equalsIgnoreCase(), or use a PathMatcher with the regex:(?i) prefix for a pattern.
Path root = projectTree();
Files.writeString(root.resolve("docs/Readme.MD"), "mixed");
long ignoringCase;
try (Stream<Path> s = Files.find(root, Integer.MAX_VALUE,
        (p, a) -> a.isRegularFile() && p.getFileName().toString().equalsIgnoreCase("readme.md"))) {
    ignoringCase = s.count();
}
long readmeCount = ignoringCase;                 // 3
5. Handling Folders We Cannot Read
Files.walk() and Files.find() stop at the first folder they cannot open. The stream throws an UncheckedIOException that wraps the AccessDeniedException, so a search from a home folder or a drive root fails on one protected subfolder.
The Files.walkFileTree() method gives us control. A FileVisitor can return CONTINUE from visitFileFailed() to skip the folder it cannot read, and TERMINATE from visitFile() to end the walk once the file is found.
static Optional<Path> findFirstByName(Path start, String fileName) throws IOException {
    Path[] result = new Path[1];
    Files.walkFileTree(start, new SimpleFileVisitor<>() {
        @Override
        public FileVisitResult visitFile(Path file, BasicFileAttributes attrs) {
            if (file.getFileName().toString().equals(fileName)) {
                result[0] = file;
                return FileVisitResult.TERMINATE;
            }
            return FileVisitResult.CONTINUE;
        }

        @Override
        public FileVisitResult visitFileFailed(Path file, IOException e) {
            System.err.println("Skipped " + file + ": " + e);
            return FileVisitResult.CONTINUE;
        }
    });
    return Optional.ofNullable(result[0]);
}
Path root = projectTree();
Optional<Path> test = findFirstByName(root, "AppTest.java");
Optional<Path> missing = findFirstByName(root, "pom.xml");
String found = test.map(p -> root.relativize(p).toString()).orElse("none"); // "src/test/AppTest.java"
boolean absent = missing.isEmpty(); // trueThe same visitor can return SKIP_SUBTREE from preVisitDirectory() to leave out folders such as .git or node_modules, which speeds up searches in source trees.
6. Using Recursion
Before java.nio.file, a recursive file search called File.listFiles() for each folder. The approach still works, but recursion with java.io.File must handle the null that listFiles() returns for a folder it cannot read.
static void findByName(File dir, String fileName, List<File> found) {
    File[] entries = dir.listFiles();
    if (entries == null) {
        return;                        // not a directory, or not readable
    }
    for (File entry : entries) {
        if (entry.isDirectory()) {
            findByName(entry, fileName, found);
        } else if (entry.getName().equalsIgnoreCase(fileName)) {
            found.add(entry);
        }
    }
}
Path root = projectTree();
List<File> readmes = new ArrayList<>();
findByName(root.toFile(), "readme.md", readmes);
int count = readmes.size(); // 2The recursive version follows symbolic links to folders, so a link that points to a parent folder makes it search the same files again and again until the operating system rejects the long path. The NIO methods do not follow links unless we pass FileVisitOption.FOLLOW_LINKS, and with that option they detect cycles and report a FileSystemLoopException.
7. Choosing a Way to Find Files
All four approaches find the same files, and they differ in error handling, early exit and how much code we write.
| Approach | Best for | Stops early | Unreadable folder |
|---|---|---|---|
| Files.find() | Name plus attribute checks, the default choice | With findFirst() | Stream throws UncheckedIOException |
| Files.walk() | Stream pipelines that also need folders | With findFirst() | Stream throws UncheckedIOException |
| Files.walkFileTree() | Skipping folders, ignoring errors | TERMINATE | We decide in visitFileFailed() |
| Recursion with File.listFiles() | Old code based on File | With a flag or exception | listFiles() returns null |
To list every file instead of searching for one, the guide to listing all files in a directory covers Files.list() and hidden files. Reading, writing and watching files are indexed in the Java IO hub.
8. Finding Files in Java FAQs
Search order, symbolic links and exceptions in the middle of a walk account for most questions about recursive file search.
8.1. Is Files.walk() Depth-First or Breadth-First?
Depth-first. The walk returns the start folder first and enters each subfolder completely before it moves on to the next sibling. Within one folder, the order of entries is not specified, so sort the results when the order matters.
8.2. What Is the Difference Between Files.find() and Files.walk()?
The Files.find() method passes the BasicFileAttributes it already read to our condition, whereas a filter on Files.walk() must call Files.isRegularFile() or Files.size() again. Use Files.find() for searches and Files.walk() when every entry goes through the pipeline.
8.3. How Do I Follow Symbolic Links During the Search?
Pass FileVisitOption.FOLLOW_LINKS as the last argument of Files.find(), Files.walk() or the four-argument walkFileTree(). With that option, a link that points back to a parent folder fails with a FileSystemLoopException instead of looping. The guide to symbolic links shows how to create and read them.
8.4. Why Does Files.find() Throw UncheckedIOException?
A Stream cannot throw checked exceptions, so an I/O error during the walk, such as an AccessDeniedException, arrives wrapped in UncheckedIOException. Catch it around the terminal operation and read getCause(), or use walkFileTree() to skip the folder and continue.
9. Conclusion
Files.find() is the shortest way to find a file in a directory and its subdirectories, because its condition gets the path and the file attributes together. Compare getFileName() instead of the full path string, close the stream, limit the depth when the tree is large and use findFirst() when one match is enough.
Switch to walkFileTree() when the search must skip unreadable or unwanted folders, and keep the recursive File.listFiles() version for old code only, with a null check on every call.
10. References
- Files.find Javadoc (Java 25)
- Files.walk Javadoc
- FileVisitResult Javadoc
- FileSystem.getPathMatcher Javadoc
- Oracle Java Tutorials, Finding Files
Happy Learning !!
