
These SQL interview questions cover keys, joins, grouping, indexes and transactions, followed by query exercises. Explain what rows a query returns and how NULLs or duplicates affect it. Examples use several database dialects; identify the target database before treating syntax or behavior as portable.
Concept and query questions
1. What is a Database?
A database is an organized collection of data managed for retrieval and change. A relational database usually represents that data in tables with declared relationships and constraints.
Let’s take some database examples: An online phone book uses a database to store data of people, phone numbers, and other user details. Your internet service provider uses a database to manage billing, client-related issues, handle fault data, and so on.
movies(id, title) -> ratings(movie_id, user_id, score)
users(id, name)  -> ratings(user_id, movie_id, score)
A database can store movies, users and ratings as related tables.
2. What is a DataBase Management System (DBMS)?
In terms of programming, a database management system is a software for creating and managing databases. DBMS allows us to create, protect, read, update and delete data in a database. It works as an interface between databases and us or application programs.
application -> DBMS -> database files
                 |
                 -> transactions, access rules and query execution
A few popular examples are MySQL, PostgreSQL, Microsoft Access, SQL Server, FileMaker, and Oracle.
3. What is Object-Relational Mapping?
Object-relational mapping (ORM) maps program objects to relational rows. A Java ORM library can generate SQL for common reads and writes, but you still need to understand the queries it sends and the transactions around them.
For example, saving an Employee object may produce an INSERT or UPDATE for an employees table. The mapping defines which property supplies each column.
ORMs can provide parameter binding and transaction integration, but they do not automatically prevent SQL injection in manually concatenated queries. Bind values and enforce permissions even when a library generates some SQL for you.
Employee object -> ORM mapping -> employees row
                         -> generated INSERT/UPDATE/SELECT
4. How do SQL and PL/SQL differ?
SQL is the language used to declare data definitions and data operations. PL/SQL is Oracle’s procedural language for writing blocks that can contain SQL statements, variables, control flow and exception handling. Other database products have their own procedural languages.
-- Oracle PL/SQL block
BEGIN
  UPDATE accounts SET active = 1 WHERE id = 7;
END;
The UPDATE is SQL inside the PL/SQL block. Both run in the database environment; the distinction is procedural control around SQL, not one language being on the server and the other outside it.
5. How do relational and non-relational databases differ?
A relational database is organized in tables. Usually, the data within these tables have relationships with one another or dependencies.
Non-relational databases include document, key-value, wide-column and graph stores. They do not all use one document structure. Compare the data model and access requirements instead of assuming “NoSQL” means one particular storage format.
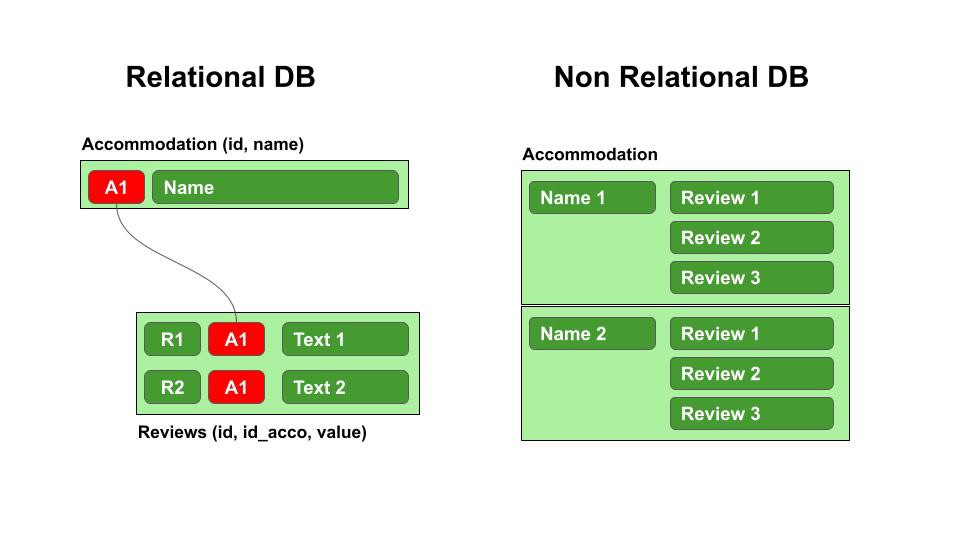
Relational vs non-relational database
6. How do DDL, DML, DCL and transaction statements differ?
These labels group statements by purpose. DDL changes schema, DML reads or changes rows, DCL manages privileges, and transaction statements control a unit of work. Some teaching material calls SELECT a separate DQL category; it is still an SQL query.
CREATE TABLE -> schema definition
SELECT/INSERT/UPDATE/DELETE -> data operations
GRANT/REVOKE -> privileges
COMMIT/ROLLBACK -> transaction control
The exact statements and their transactional behavior vary by database. State the target dialect before giving a rule about rollback or permissions.
7. What is a query?
A query asks the database for a result set. In everyday SQL use, that usually means a SELECT statement. INSERT, UPDATE and DELETE are data-changing statements; some databases can also return rows from them.
SELECT id, name
FROM employees
WHERE year_born < 1990;
This returns the ID and name of each employee whose stored birth year is below 1990. An index may help or may not, depending on data and the database’s plan.
8. What is a primary key?
A primary key identifies each row through one column or a combination of columns. Its values are unique and cannot be NULL. A generated numeric ID is one common choice, not a requirement.
CREATE TABLE employees (
  id INTEGER PRIMARY KEY,
  name VARCHAR(45) NOT NULL
);
Each employee row has one ID. A table can declare one primary key, and that key can contain more than one column.
9. What does a UNIQUE constraint enforce?
A UNIQUE constraint rejects duplicate non-NULL values or value combinations according to the database’s rules. A table can have several such constraints. NULL behavior varies by engine and by constraint definition.
CREATE TABLE employees (
  id INTEGER PRIMARY KEY,
  email VARCHAR(255) UNIQUE
);
Here two employees cannot share the same non-NULL email. If every employee must have an email, add NOT NULL as a separate requirement.
10. How do primary-key and unique constraints differ?
A table has one declared primary key, which identifies its rows and disallows NULL. It can have several UNIQUE constraints on other candidate values. Do not assume either constraint always creates a clustered or non-clustered index; physical index behavior depends on the database.
CREATE TABLE users (
  id INTEGER PRIMARY KEY,
  email VARCHAR(255) UNIQUE
);
The ID is the row identifier. Email has a separate uniqueness rule. The treatment of multiple NULL emails depends on the engine.
11. What does a foreign key protect?
A foreign key requires a non-NULL value to refer to an eligible key in another row or table. It protects the relationship from a dangling reference. NULL and deletion behavior depend on the column and foreign-key declarations.
CREATE TABLE employees (
  id INTEGER PRIMARY KEY,
  manager_id INTEGER,
  FOREIGN KEY (manager_id) REFERENCES employees(id)
);
An employee may have no manager when manager_id is NULL. A non-NULL manager ID must identify an employee row.
12. What do normalization and denormalization change?
Normalization organizes attributes according to their dependencies, reducing update anomalies. Denormalization deliberately stores a repeated or precomputed value for a measured access pattern and adds work to keep copies consistent.
repeated orders(order_id, customer_name, customer_email)
  -> customers(customer_id, name, email)
  -> orders(order_id, customer_id)
If the customer changes email, the normalized design updates one customer row. A denormalized order snapshot may intentionally preserve the old email, but the application must define whether that is history or a copy that should be refreshed. There is no universal rule that one design is always faster.
13. What does a join do?
A join combines rows from two sources according to a condition. An inner join keeps matches; a left join also keeps unmatched rows from its left input, filling right-side columns with NULL. Right and full outer joins, and cross joins, cover other needs where supported.
SELECT c.id, o.id AS order_id
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.id;
A customer with two matching orders appears twice. A customer with no order appears once with a NULL order_id. Join cardinality matters as much as the join name.
14. How does a self-join work?
A self-join references one table more than once, usually with different aliases. It does not require a declared primary-key/foreign-key relationship. The employee-manager case is one common use, while comparing other rows in the same table is another.
For example: Let’s take our Employee table. We have a manager for each employee, but it’s hard to read because we cannot see the manager’s name of an employee directly.
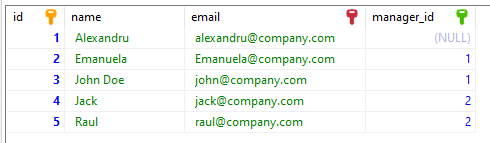
Employee table
We can write a Self-Join to create a view where we have the employee and manager names on the same row.
SELECT employee.id, employee.name, employee.email, employee.manager_id, manager.name AS "Manager name"
FROM Employee employee
LEFT JOIN Employee manager ON employee.manager_id= manager.id
After executing the query, we will obtain the following result:
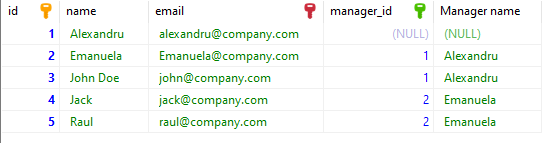
Result SQL
Note that we have used LEFT JOIN because we want to get all the employees even if the manager_id is NULL. If we use a normal join, the first entry from the result will be excluded because the employee Alexandru does not have a manager.
15. How do inner and outer joins differ?
An inner join returns matching row combinations. An outer join also preserves unmatched rows from the designated side or sides, filling missing columns with NULL. Calling these operations intersection and union hides duplicate handling and join cardinality.
SELECT c.id, o.id
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.id;
A left join keeps a customer even when no order matches; the order columns are then NULL.
The ON predicate controls matching. A one-to-many relationship can produce several output rows for one left-side row.
16. How do UNION and UNION ALL differ?
Both combine compatible query results. UNION removes duplicate result rows; UNION ALL preserves them. The column count and compatible types must agree across inputs.
SELECT customer_id FROM online_orders
UNION ALL
SELECT customer_id FROM store_orders;
If customer 7 appears in each input, UNION ALL keeps both rows while UNION returns one. Neither operator guarantees output order without a final ORDER BY.
17. What is an Index?
An index provides an additional access path to data. B-tree indexes are common, but other structures exist, and index pages are not necessarily all in memory. Indexes consume storage and add write-maintenance cost.
Without a useful index, a query may scan a table, though the optimizer can have other access paths. A scan is not automatically bad: it can be efficient for small tables or a query returning much of the data. Inspect the execution plan and actual workload.
The optimizer decides whether an available index is worthwhile. Selectivity, statistics, expressions, ordering and estimated cost affect the choice. Merely creating an index on a WHERE column does not guarantee its use.
We can add an index in the following way:
CREATE INDEX INDEX_EMAIL ON EMPLOYEE (EMAIL);
18. What does a database trigger do?
A trigger runs database-defined logic in response to an event such as an INSERT or UPDATE. Supported events, timing and syntax differ by engine. Use a trigger when the rule must run for every writer, and keep its side effects visible to maintainers.
-- SQLite example
CREATE TRIGGER audit_employee_name
AFTER UPDATE OF name ON employees
BEGIN
  INSERT INTO employee_audit(employee_id, old_name, new_name)
  VALUES (OLD.id, OLD.name, NEW.name);
END;
Updating an employee name adds one audit row. The audit table must exist, and the trigger participates in the surrounding transaction. The example is SQLite syntax; do not paste it unchanged into another database.
19. What is a database cursor?
A cursor lets procedural database code fetch and process a result one row at a time. Cursor declarations, implicit cursors and scroll behavior vary by database language. A set-based SQL statement is usually simpler when it can express the same change.
query result -> cursor -> fetch row -> process -> fetch next row
A cursor can be appropriate when each row needs procedural work that cannot be expressed clearly as one set operation. Check the target database’s cursor lifetime and transaction rules.
20. What is a View in a Database?
An ordinary view stores a query definition rather than a separate copy of its result. A materialized view stores results and has a refresh mechanism. A view name is scoped by the database’s namespace rules, not necessarily unique across every schema.
Views can give callers a stable query interface. They can help limit exposed columns when the database grants access to the view and withholds access to the base table; the view definition alone is not an access-control policy.
This view exposes only three employee columns to callers. Access control still depends on the grants assigned to the view and underlying tables.
CREATE VIEW EMPLOYEE_VIEW AS
SELECT ID, NAME, DOB
FROM  EMPLOYEE;
Distinguish ordinary views from materialized views where the engine supports them. “Dynamic” and “static” are not a universal two-type SQL classification. Changes to base data affect an ordinary view when queried; stored materialized results follow their refresh rules.
21. How does a view differ from a table?
Views and tables may seem pretty similar, but they have some differences. Both of them consist of rows and columns, but they differ in terms of persistence.
table: stored rows and columns
view:  stored query definition -> result evaluated when queried
Some engines also support materialized views, which store a refreshed result; do not assume every view stores rows.
A table stores rows; an ordinary view derives rows from its saved query. The view definition normally persists beyond a session unless explicitly temporary. Do not confuse a stored view with a temporary query result.
22. How do TRUNCATE and DROP differ?
The DROP command removes the entire table, including the definition, indexes, constraints, and triggers for that table.
TRUNCATE TABLE staging_orders;
DROP TABLE staging_orders;
The first removes rows while keeping the table definition; the second removes the table object. Transaction and foreign-key behavior vary by database.
The TRUNCATE command deletes only all the rows from the table. The schema is not affected by this command.
23. How do DELETE and TRUNCATE differ?
DELETE can remove selected rows with a WHERE condition. TRUNCATE removes every row while retaining the table definition. Trigger firing, transaction rollback and foreign-key restrictions vary by engine.
DELETE FROM orders WHERE status = 'cancelled';
TRUNCATE TABLE staging_orders;
The first statement targets canceled orders; the second clears the staging table. Check the target database’s documentation before assuming either operation can be rolled back or fires the same triggers.
24. How do ORDER BY and GROUP BY differ?
Using ORDER BY, we can sort the result set in ascending or descending order.
SELECT customer_id, COUNT(*) AS order_count
FROM orders
GROUP BY customer_id
ORDER BY order_count DESC;
GROUP BY forms one result row per customer; ORDER BY sorts those result rows.
GROUP BY clause is used to group the rows with the same value.
25. How do WHERE and HAVING differ?
WHERE filters input rows before grouping. HAVING filters groups after aggregation. A grouped query can use both clauses for different decisions.
SELECT department_id, COUNT(*) AS employee_count
FROM employees
WHERE active = 1
GROUP BY department_id
HAVING COUNT(*) >= 3;
This counts active employees per department and keeps departments with at least three. The selected non-aggregate columns must follow the target database’s grouping rules.
26. What kinds of constraints can a table declare?
Constraints reject rows that violate declared rules. Common choices are PRIMARY KEY, UNIQUE, NOT NULL, CHECK and FOREIGN KEY.
CREATE TABLE orders (
  id INTEGER PRIMARY KEY,
  customer_id INTEGER NOT NULL,
  amount DECIMAL(10, 2) CHECK (amount >= 0),
  FOREIGN KEY (customer_id) REFERENCES customers(id)
);
The constraints enforce row identity, required values, a numeric condition and a relationship.
The CHECK constraint rejects a negative amount, while the foreign key requires a non-NULL customer ID to reference a customer. Type enforcement and NULL handling vary by engine; test the actual schema.
27. What is a Stored Procedure?
A stored procedure is a named database routine that can run SQL and procedural logic. It differs from a prepared statement, which is a parameterized statement prepared for execution. Procedure syntax and capabilities vary by database.
For example, this SQL Server procedure returns employees and their managers:
CREATE PROCEDURE dbo.ListEmployeesWithManagers
AS
BEGIN
  SELECT e.id, e.name, m.name AS manager_name
  FROM dbo.Employees AS e
  LEFT JOIN dbo.Employees AS m ON m.id = e.manager_id;
END;
And we can execute the procedure as follows:
EXEC dbo.ListEmployeesWithManagers;
28. What is a Schema in SQL?
A database schema describes the structure of database objects such as tables, columns, constraints and views. In some products, schema also means a named namespace that contains objects. These related meanings are useful to distinguish in interviews.
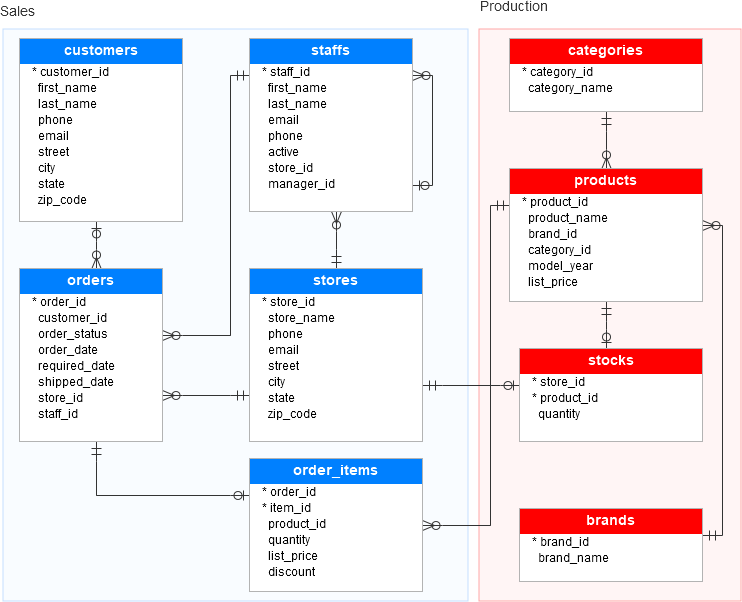
SQL Schema
The diagram shows related sales and product tables. Their columns and relationships are part of the database schema.
29. How do UNION, EXCEPT and INTERSECT combine result sets?
These operators combine complete query results. UNION keeps distinct rows from either result; INTERSECT keeps distinct rows in both; EXCEPT keeps distinct rows from the first result that are absent from the second. Some products use MINUS instead of EXCEPT.
SELECT customer_id FROM online_orders
UNION
SELECT customer_id FROM store_orders;
The example combines customer IDs from two order sources. Replace UNION with UNION ALL to retain duplicates. Use compatible column counts and types, and add a final ORDER BY when order matters.
30. What does the COALESCE function do?
The COALESCE function takes several parameters, evaluates them in sequence, and returns the first non-null argument. For example, given the following query:
SELECT COALESCE(NULL, 'Alexandru', 'Java', NULL) AS result;
The result will be ‘Alexandru’.
31. What is SQL Injection?
SQL injection occurs when untrusted input is concatenated into SQL text and changes the statement’s meaning. Bind user input as a parameter so it remains a value, even if it contains SQL punctuation.
String sql = "SELECT id FROM users WHERE username = ?";
try (PreparedStatement statement = connection.prepareStatement(sql)) {
    statement.setString(1, username);
    try (ResultSet rows = statement.executeQuery()) {
        // Read matching IDs.
    }
}
Parameter binding protects values in this statement. Table or column names cannot usually be bound as values; choose them from an allowlist if the application must vary them. Enforce database privileges as a separate defense.
32. How do you insert several rows?
One INSERT can supply several rows through a comma-separated VALUES list. Specify destination columns so the meaning does not depend on table column order.
INSERT INTO employee (id, NAME, email, manager_id, country)
VALUES
    (6, 'Anna','ana@gmail.com',2,'Romania'),
    (7, 'Maria', 'maria@company.com',1, 'UK'),
    (8, 'Laura', 'laura@as.com',3,'Norway');
33. How do you add a column?
Use ALTER TABLE to add a column. Existing rows receive the database’s default or NULL, subject to the column definition and engine rules.
ALTER TABLE employee ADD COLUMN phone_number VARCHAR(13);
After the execution our table will look like this:
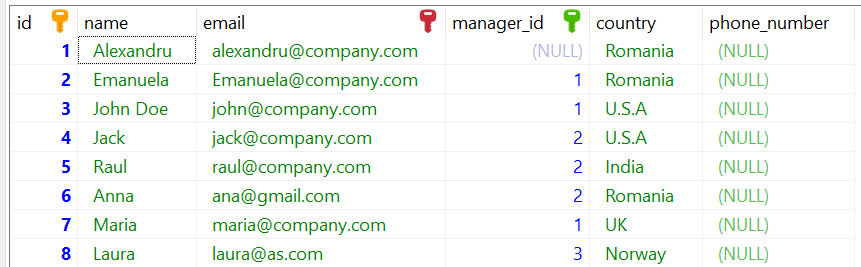
Altering a Table
34. What are the NVL and the NVL2 Functions? How do They Differ?
In Oracle, NVL(value, fallback) returns the fallback when the value is NULL. NVL2(value, when_present, when_null) chooses its second argument when the value is not NULL and its third argument when it is NULL. These are Oracle functions; COALESCE is a common choice for finding the first non-NULL value.
SELECT NVL(NULL, 'fallback') FROM dual;              -- fallback
SELECT NVL2(NULL, 'present', 'missing') FROM dual;   -- missing
SELECT NVL2('x', 'present', 'missing') FROM dual;    -- present
35. How does LIKE match text?
The LIKE operator is used in WHERE clauses to check if a value fits a given string pattern. Here is an example of a LIKE operator:
SELECT id, name FROM employee WHERE name LIKE 'Alex%';
% matches zero or more characters, so this finds names beginning with Alex. Case sensitivity and index use depend on the database and collation.

36. How do you return distinct rows?
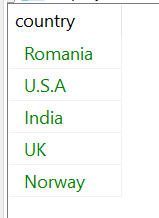
SELECT DISTINCT fetches all the distinct data from a query. For example, let’s say that we want all the distinct countries where our employees are located. For this task, we will use the following SQL query:
SELECT DISTINCT country FROM employee
And the result of the query will be:
37. What is Data Integrity?
Data integrity is referred to the data’s precision and consistency (validity) over its lifecycle. It ensures an organization’s data’s accuracy, completeness, consistency, and validity.
PRIMARY KEY -> row identity
FOREIGN KEY -> relationship to an existing row
CHECK       -> allowed value range
These constraints keep invalid states out of the database, alongside application validation.
Every time data is copied or moved, it should remain unchanged and unaltered between updates. Error checking methods and validation procedures are typically responsible for ensuring the integrity of data transmitted or reproduced without the purpose of alteration.
38. What are ACID Properties?
The ACID properties describe the set of properties of database transactions that guarantee data integrity despite errors, system failures, power failures, or other issues.
transfer: debit account A + credit account B
COMMIT: both changes become durable
ROLLBACK: neither change remains
This illustrates atomicity; consistency, isolation and durability address different transaction guarantees.
- Atomicity: means that the transaction takes place at once or doesn’t happen at all;
- Consistency: means that integrity constraints must be maintained so that the database is consistent before and after the transaction;
- Isolation: ensures that each transaction is independent and occurs without interference;
- Durability: ensures that after a transaction has completed execution, the updates and modifications to the database are stored in and written to disk, and they persist even if a system failure occurs.
39. How do CHAR and VARCHAR2 differ?
In Oracle, CHAR is fixed-length and blank-padded to its declared width. Length semantics can be bytes or characters, so state the declaration and database settings before comparing storage or limits.
-- Oracle dialect
CREATE TABLE codes (fixed_code CHAR(4), label VARCHAR2(40));
CHAR is fixed length and may be padded; VARCHAR2 is variable length in Oracle. Compare trailing-space semantics in the target database.
Oracle VARCHAR2 stores variable-length character data. Its supported limit depends on configuration, including MAX_STRING_SIZE, and may exceed the traditional 4,000-byte SQL limit. Do not apply Oracle’s type name or limits to every SQL engine.
40. What do COMMIT and ROLLBACK do?
COMMIT makes a transaction’s changes permanent; ROLLBACK discards its uncommitted changes. Transaction boundaries depend on explicit statements, autocommit and database behavior. Consecutive SQL statements are not automatically one transaction in every client.
BEGIN;
UPDATE accounts SET balance = balance - 50 WHERE id = 1;
UPDATE accounts SET balance = balance + 50 WHERE id = 2;
COMMIT;
ROLLBACK would abandon the uncommitted updates. Exact transaction syntax varies by database.
- Commit in SQL is used to permanently save the changes done in the transaction in tables/databases. Until we perform COMMIT after making changes to data, data will not be saved unless AUTO COMMIT is ON.
- ROLLBACK in SQL undoes the transactional changes that have not been already saved in the database. The data changes are undone until the last COMMIT command. With the help of ROLLBACK, we can avoid unwanted database changes.
41. Are NULL values Same as Zero or a Blank space?
No. NULL represents missing or unknown information, while zero and a blank string are values. Use IS NULL rather than = NULL. Also note engine-specific behavior, such as Oracle treating an empty character string as NULL.
SELECT id FROM employees WHERE manager_id IS NULL;
Use IS NULL rather than = NULL. NULL denotes an absent or unknown value; it is neither numeric zero nor an empty string in ordinary SQL comparison.
- The NULL represents an unavailable, unassigned, or unknown value,
- The zero is a number value.
- The blank space is a single whitespace character. It is a valid value for CHAR/VARCHAR2 datatypes.
42. What is a user-defined function?
A user-defined function (UDF) is a database routine that returns a value or, in databases that support it, a table. Unlike a stored procedure, a scalar function can be used as an expression in a query. Creation syntax varies by database.
-- SQL Server example
CREATE FUNCTION dbo.GetEmployeeName(@id INT)
RETURNS NVARCHAR(50)
AS
BEGIN
    DECLARE @name NVARCHAR(50);
    SELECT @name = name FROM dbo.Employee WHERE id = @id;
    RETURN @name;
END;
To execute this function use the following command.
SELECT dbo.GetEmployeeName(1) AS employee_name;
43. What do aggregate functions calculate?
Aggregate functions are SQL functions that take several rows, perform a calculation, and then return the result after reducing it according it the used function.
Some examples of aggregate functions will be COUNT (used to get the number of values returned by a SQL statement), MAX/MIN (the largest, respective the smallest value from a SQL result set), etc.
Let us understand with an example. Our table looks like this:
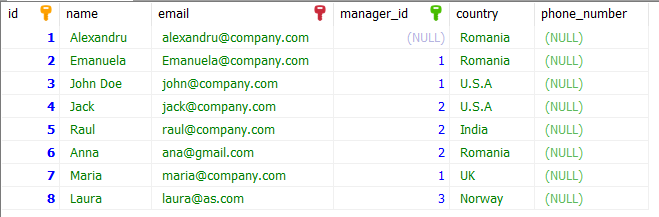
SQL table
Let’s test the COUNT function. We want to write a query to see how many employees have Alexandru as their manager.
SELECT COUNT(*) AS employee_count
FROM employee
WHERE manager_id = 1;
44. What relationship types can tables model?
There are 3 main types of relationships in a database: one-to-one, one-to-many and many-to-many. Let us understand these relationships with following image.
One-to-one:   person 1 --- 1 passport
One-to-many:  customer 1 --- many orders
Many-to-many: authors many --- many books (through author_book)
- One-to-one -> occurs when each row in the user table has only one corresponding row in the password table.
- One-to-many -> one-to-many relationship occurs when one record in the class table is related to one or more records in the student table. However, one record in the student table cannot be related to more than one record in the class table.
- Many-to-many -> multiple records in one table (books table) are related to various records in another table (authors table).
45. What is a Live Lock?
Locks coordinate concurrent database operations. A livelock can occur when transactions repeatedly yield or retry in response to each other, yet neither completes. This differs from a deadlock, in which each waits for a resource held by another.
transaction A backs off -> B backs off -> A retries -> B retries
             both remain active, but neither completes
A livelock involves continued activity without useful progress; a deadlock involves a circular wait with no progress.
In livelock, participants keep responding or retrying but make no useful progress. Indefinitely denying one request while others complete is usually described as starvation. Keep both distinct from deadlock, where participants wait on a dependency cycle.
A retry limit, backoff with jitter and database-specific deadlock handling can help. Diagnose the actual wait and retry pattern before calling it a livelock.
46. How do you find names with a given prefix?
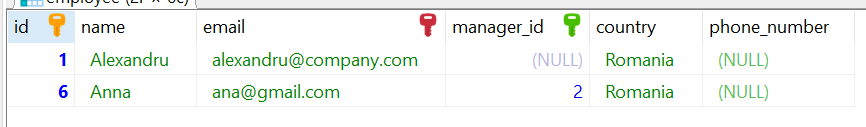
For this query, we can use the LIKE operator for comparing strings and the % symbol which acts as a wildcard to match characters.
Let’s say we want to select all the employees that have a name starting with ‘a”. We will write the following query:
SELECT name FROM employee WHERE name LIKE 'A%';
The result of our query will be:
47. How do you find and remove duplicate records?
First decide which columns define a duplicate and which row to keep. For the example below, duplicate means equal non-NULL email, and the row with the lowest ID is retained. Preview the rows before deleting anything.
Consider these rows in employee_2:
id  email
1   a@example.com
2   a@example.com
3   b@example.com
4   b@example.com
5   NULL
The query uses a correlated EXISTS test. A transaction lets you inspect the affected rows before committing, where your database supports transactional deletes.
Our query will look like this:
SELECT id, email
FROM employee_2 AS e
WHERE email IS NOT NULL
  AND EXISTS (
    SELECT 1 FROM employee_2 AS earlier
    WHERE earlier.email = e.email AND earlier.id < e.id
  );

DELETE FROM employee_2 AS e
WHERE email IS NOT NULL
  AND EXISTS (
    SELECT 1 FROM employee_2 AS earlier
    WHERE earlier.email = e.email AND earlier.id < e.id
  );
This retains IDs 1, 3 and 5. NULL emails are left alone; equality does not match NULL. DELETE alias syntax differs by engine, so adapt the statement to the target database and confirm the preview before executing it.
After deletion: (1, a@example.com), (3, b@example.com), (5, NULL)
Conclusion
Practice predicting result rows before running a query, especially for outer joins, grouping, duplicates and NULLs. For performance and transaction questions, name the database and explain the evidence you would inspect rather than repeat a vendor-specific rule as universal SQL behavior.
You can also go over JDBC performance tips for additional concepts to learn.
Happy Learning !!
