

Fine-tuning adapts a base model by training it on examples of the responses you want. This walkthrough explains the OpenAI workflow: prepare conversations, validate and upload the data, create a job, inspect its status and call the resulting model. The original code and screenshots illustrate an older GPT-3.5 workflow.
Availability matters before you start. OpenAI self-serve fine-tuning is no longer available to new organizations. Eligible existing customers can create jobs only until January 6, 2027, and inference depends on the underlying model lifecycle. Read the current availability notice before using the historical steps below.
- Preparing the training data
- Uploading the training data to OpenAI servers
- Creating a fine-tuned model with the training data
- Interacting with the fine-tuned model using chatGPT Completion API
- Further improving the data quality of the fine-tuned model
The support-answer example demonstrates response behavior, not a live source of support facts. For frequently changing product information, consider RAG and prompt engineering before training. Listing and deletion examples appear in the FAQ.
Prerequisites
For the historical API workflow, the prerequisites below are necessary but may no longer be sufficient: your organization must also be eligible for training and the selected base model must still be supported.
- A Python version supported by the SDK you install; the original environment used an older release
- An OpenAI API key, which can be obtained by signing up for an OpenAI account
- A code editor, such as PyCharm (recommended), to write and run Python code
- Training data in a JSONL file
You can learn to obtain the OpenAI API Key and set up the development workspace in the guide: Getting Started with ChatGPT API and Python.
Step 1: Preparing the Training Data
Start with representative conversations that show the intended behavior. Include ordinary requests, edge cases and examples of appropriate refusals. Keep a separate evaluation set so you can compare the trained model with the base model on examples it did not train on.
The example uses JSONL: one complete conversation object per physical line. Each conversation contains a messages array with the instruction, user request and desired assistant response. Fine-tuning learns from those examples, so consistent answers matter more than merely collecting many records.
Use data you are authorized to process, remove secrets and review personal information before upload. Public availability alone does not establish that material is suitable or licensed for a training dataset.
1.1. Training Data Format
The file input_data.jsonl demonstrates the conversational format used by this older GPT-3.5 example. Each JSONL record is one conversation; individual messages stay inside that record’s messages array. They are not separate JSONL lines.
{"messages": [{"role": "user", "content": "Reset my password for account ID 12345"}, {"role": "assistant", "content": "Your password has been reset. Please check your email for the new login details."}]}
{"messages": [{"role": "user", "content": "How do I update my billing information?"}, {"role": "assistant", "content": "To update your billing information, log in to your account, go to the 'Billing' section, and follow the prompts."}]}
...
To start the fine-tuning a model, we must provide at least 10 examples. For optimal results surpassing base models, we should aim to provide a few hundred or more high-quality examples, preferably vetted by human experts. The right number of examples varies on the exact use case and the level of required accuracy.
1.2. Verifying the Training Data
Validate two things separately: each line must parse as JSON, and each parsed conversation must satisfy the trainer’s message schema. Then review the content for inconsistent labels, poor answers and overlap with evaluation data.
Use the provider’s supported schema for the model and training method you actually select. A successful local validator checks only the rules it implements; it does not guarantee that a training service will accept the file.
import json
from collections import defaultdict

data_path = "input_data.jsonl"

# Load the dataset
with open(data_path, 'r', encoding='utf-8') as f:
  dataset = [json.loads(line) for line in f]

# Initial dataset stats
print("Num examples:", len(dataset))

# Format error checks
format_errors = defaultdict(int)

for ex in dataset:
  if not isinstance(ex, dict):
    format_errors["data_type"] += 1
    continue

  messages = ex.get("messages", None)
  if not messages:
    format_errors["missing_messages_list"] += 1
    continue

  for message in messages:
    if "role" not in message or "content" not in message:
      format_errors["message_missing_key"] += 1

    if any(k not in ("role", "content", "name", "function_call") for k in message):
      format_errors["message_unrecognized_key"] += 1

    if message.get("role", None) not in ("system", "user", "assistant", "function"):
      format_errors["unrecognized_role"] += 1

    content = message.get("content", None)
    function_call = message.get("function_call", None)

    if (not content and not function_call) or not isinstance(content, str):
      format_errors["missing_content"] += 1

  if not any(message.get("role", None) == "assistant" for message in messages):
    format_errors["example_missing_assistant_message"] += 1

if format_errors:
  print("Found errors:")
  for k, v in format_errors.items():
    print(f"{k}: {v}")
else:
  print("No errors found")
Resolve validation errors before upload. The script helps catch missing fields and invalid records early, saving a failed training attempt later.
A clean local validation run produces the following message. It says the implemented checks passed, not that the dataset will improve the model:
Num examples: 15
No errors found
Step 2: Uploading the Training Data to OpenAI Server
For an eligible account, client.files.create() uploads the training file and returns a file resource. The API call below illustrates the upload step in the original workflow.
import os
from openai import OpenAI

input_jsonl_file = 'input_data.jsonl'

client = OpenAI(
  api_key=os.environ.get("OPENAI_API_KEY")
)

file = client.files.create(
  file=open(input_jsonl_file, "rb"),
  purpose="fine-tune"
)

print("File has been uploaded to OpenAI with id ", file.id)
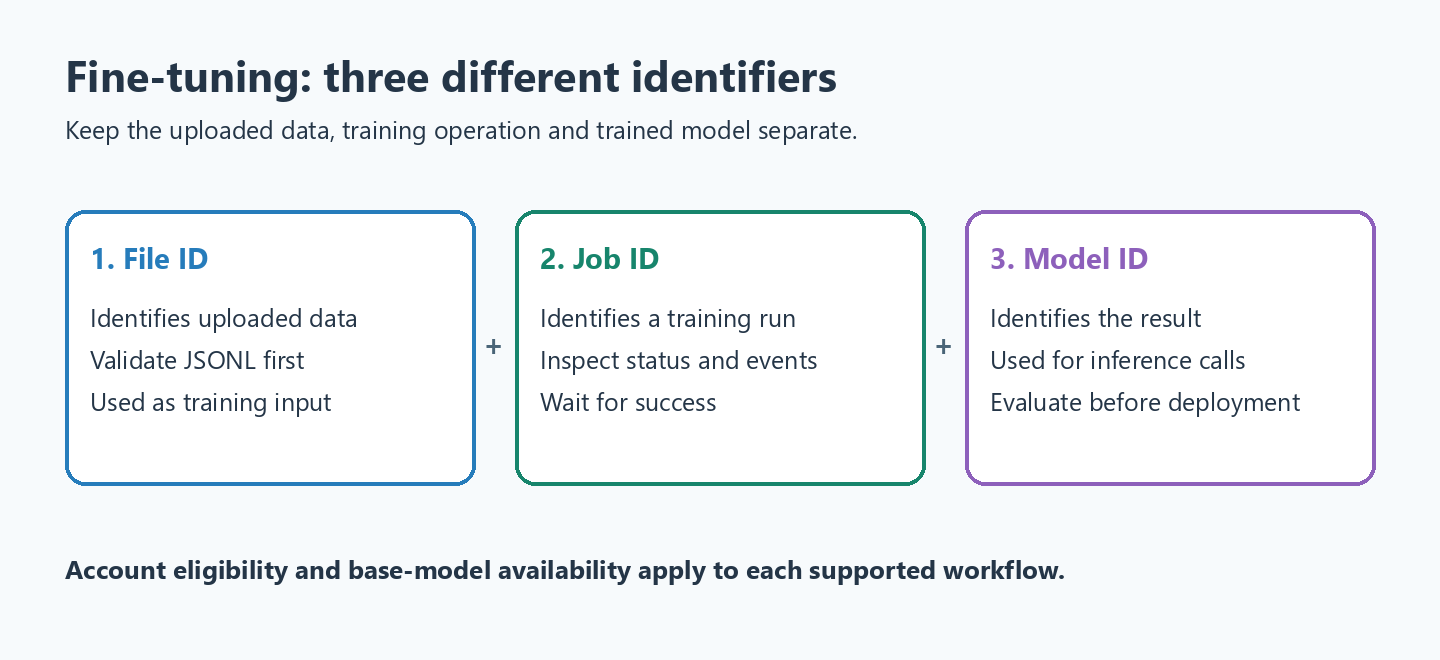
Use the returned file ID when creating the job. It identifies the uploaded file; it is neither a training-job ID nor a model ID.
File has been uploaded to OpenAI with id file-yCIKv0pm8K54FqmBam0w3BG1Step 3: Fine-tuning a Model with the Uploaded Training Data
3.1. Fine Tuning using OpenAI API
The historical client.fine_tuning.jobs.create() call starts an asynchronous job using an uploaded file. Check account eligibility, model support and expected charges before making that request.
import os
from openai import OpenAI

input_jsonl_file = 'input_data.jsonl'

client = OpenAI(
  api_key=os.environ.get("OPENAI_API_KEY")
)

file = client.files.create(
  file=open(input_jsonl_file, "rb"),
  purpose="fine-tune"
)

print("File has been uploaded to OpenAI with id ", file.id)

ft_job = client.fine_tuning.jobs.create(
  training_file=file.id,
  model="gpt-3.5-turbo"
)

print("Fine Tune Job has been created with id ", ft_job.id)
The returned job ID identifies the training operation. Keep it so you can inspect status and events while the job runs.
Fine Tune Job has been created with id ftjob-cEkAzoJeA3fuFQ7ftfHyqv9YTraining duration depends on the data, model and service capacity. Receiving a job ID only means the job was created; wait for a successful completion status before using a resulting model.
Use client.fine_tuning.jobs.list_events() to inspect progress messages and the job resource to check its status. An event log helps explain failures but does not replace the final job state.
events = client.fine_tuning.jobs.list_events(fine_tuning_job_id=ft_job.id, limit=10)

print(events)
The console output:
SyncCursorPage[FineTuningJobEvent](data=[
FineTuningJobEvent(id='ftevent-QL4SIRzfDkCRAwJZ0aaN3cWU', created_at=1702316542, level='info', message='Validating training file: file-yCIKv0pm8K54FqmBam0w3BG1', object='fine_tuning.job.event', data={}, type='message'),
FineTuningJobEvent(id='ftevent-4lpFir27PhOsjZa2N1a0Q6ti', created_at=1702316542, level='info', message='Created fine-tuning job: ftjob-cEkAzoJeA3fuFQ7ftfHyqv9Y', object='fine_tuning.job.event', data={}, type='message')], object='list', has_more=False)....
Poll at a reasonable interval and handle failed or cancelled jobs explicitly. Do not assume every accepted job eventually produces a usable model.
After successful completion, read the resulting fine-tuned model identifier. The recorded event below shows the identifier returned by the original run:
FineTuningJobEvent(id='ftevent-OqhBL7WqEkkYTQqFCjGS1BSu', created_at=1702289919, level='info', message='New fine-tuned model created: ft:gpt-3.5-turbo-0613:personal::8UXexX8R', object='fine_tuning.job.event', data={}, type='message')The recorded identifier begins with ft:gpt-3.5-turbo-0613:personal. It belongs to that historical job and cannot be reused by another account. Use the model ID returned by your own supported job.
3.2. Fine Tuning from UI
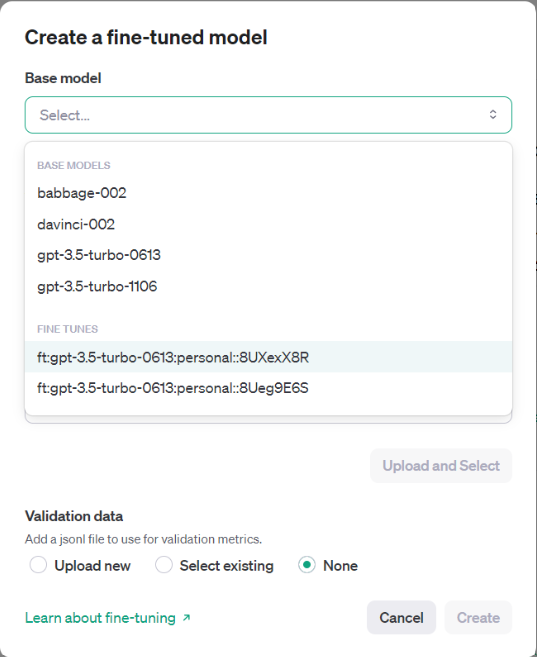
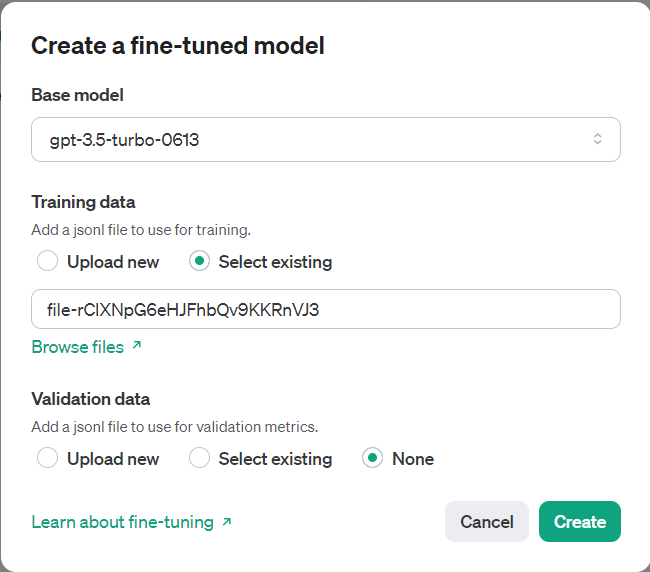
The screenshots below document the earlier dashboard workflow. Dashboard controls and access have changed; the self-serve availability restrictions above apply to UI requests as well as API requests.
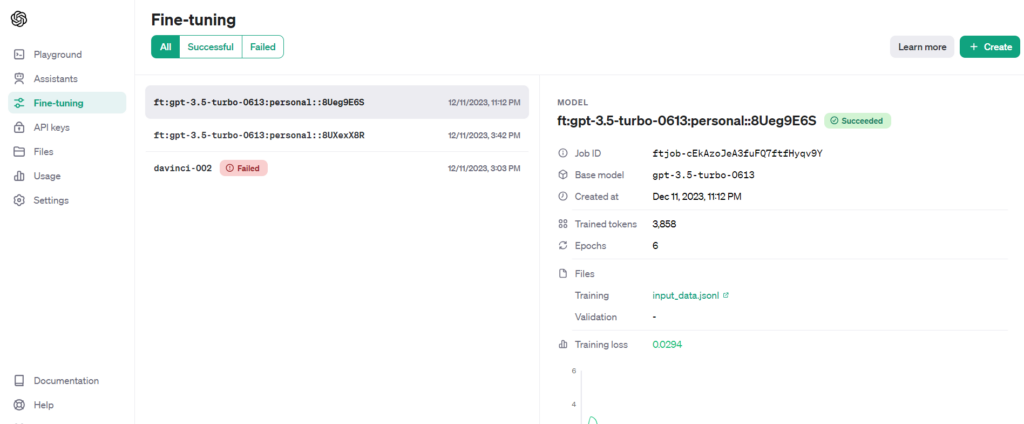
In the captured interface, + Create opened a dialog for selecting the base model and training data. Treat the screenshot as a record of that interface, not a guarantee that the button remains available to your organization.
The captured dialog accepted a training file and submitted a new job. Uploading a file alone did not start training; submitting the job was a separate action.
The dashboard then displayed the asynchronous job and its status. A job must complete successfully before its model is ready for inference.
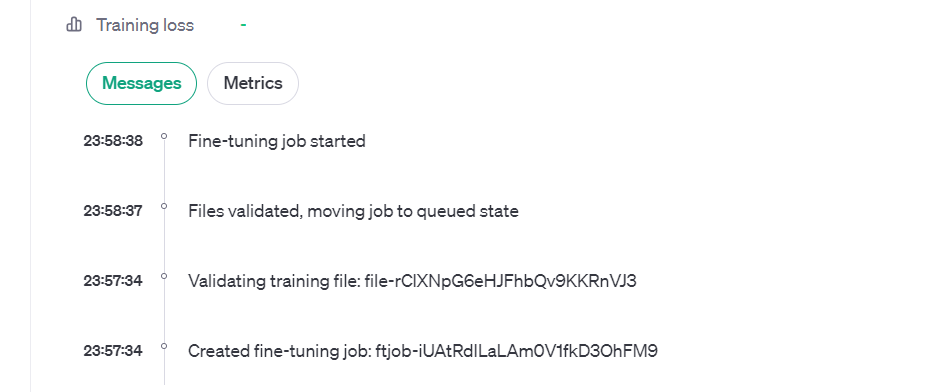
The following screenshot records a successful job from the original example:
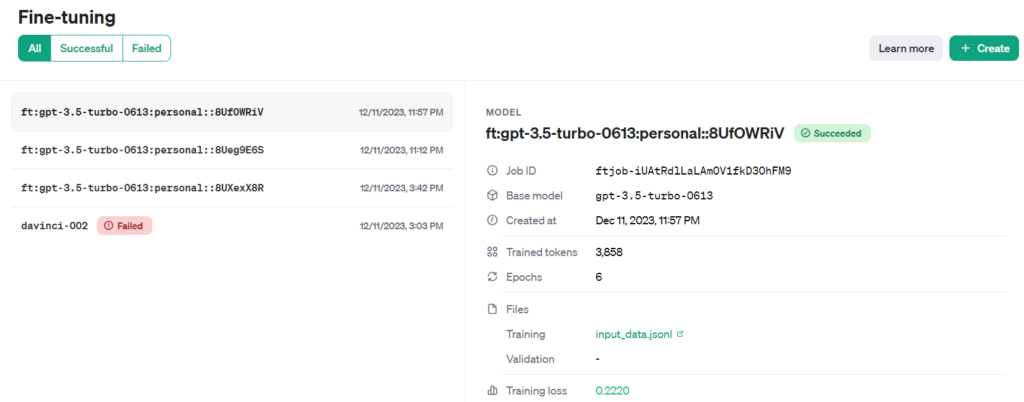
The resulting model ID is the value an inference request uses. Keep it distinct from the file ID and job ID, since each identifies a different resource.
Step 4: Interacting with Fine-tuned Model using Completion API
For a supported fine-tuned chat model, the request uses its model ID in the Chat Completions call. The code below preserves the original API example; model and account availability determine whether that request can still run.
import os
from openai import OpenAI

client = OpenAI(
  api_key=os.environ.get("OPENAI_API_KEY")
)

question = input("Ask me anything: ")

response = client.chat.completions.create(
  messages=[
    {
      "role": "user",
      "content": question
    }
  ],
  model="ft:gpt-3.5-turbo-0613:personal::8UXexX8R",
  temperature=0,
  max_tokens=1024,
  n=1,
  stop=None
)

print(response)
The response below is output from the original demonstration. Compare it with the intended answer and evaluate additional, unseen questions before judging the model’s quality.
Ask me anything: What security measures are in place to protect my account?

ChatCompletion(id='chatcmpl-8Ueks0SWI7pcB096cud09Hha013p5', choices=[Choice(finish_reason='stop', index=0,
message=ChatCompletionMessage(content='We use industry-standard encryption and authentication methods. Additionally, enable two-factor authentication for added security.', role='assistant',
function_call=None, tool_calls=None))], created=1702317194, model='ft:gpt-3.5-turbo-0613:personal::8UXexX8R',
object='chat.completion', system_fingerprint=None,
usage=CompletionUsage(completion_tokens=19, prompt_tokens=18, total_tokens=37))
This recorded response matches a training-style answer. That confirms the demonstrated interaction, but one matching response does not establish improvement or generalization. Compare a held-out set against the base model using explicit acceptance criteria.
Step 5: Further Improving the Data Quality of the Fine-tuned Model
When evaluation finds a recurring error, inspect the training examples that teach that behavior. Improve their coverage and consistency before adding more records. The recommendations below help organize that review:
- Add missing examples that directly show the model how to do the given aspects correctly.
- Update existing examples (with grammar, style, etc) that you expect from the model.
- Check the diversity of examples. The examples should be as close as possible to real conversations.
- Make examples complete enough to teach the intended behavior, while keeping answers as concise as the application requires.
If training remains available for your account, upload the revised dataset and create a supported new experiment. Keep the prior model and evaluation results for comparison. Do not assume every provider supports continuing training from a previously fine-tuned model.
In general, a smaller amount of high-quality data is generally more effective than a larger amount of low-quality data.
FAQs
How to delete a fine-tuned Model?
The API below illustrates deleting a model you own and are authorized to manage. First check that no application still references that identifier.
import os
from openai import OpenAI

client = OpenAI(
  api_key=os.environ.get("OPENAI_API_KEY")
)

client.models.delete('ft:gpt-3.5-turbo-0613:personal::8UXexX8R')
Deleting the model removes its availability for inference. Training files and job records are separate resources; do not assume model deletion removes all associated uploaded data.
How to list all the models?
The models endpoint lists model resources visible to your account. Access and lifecycle determine the result, so your list need not match this historical output.
import os
from openai import OpenAI

client = OpenAI(
  api_key=os.environ.get("OPENAI_API_KEY")
)


models = client.models.list()

print(models)
The program output:
SyncPage[Model](data=[Model(id='text-search-babbage-doc-001', created=1651172509, object='model', owned_by='openai-dev'), Model(id='curie-search-query', created=1651172509, object='model', owned_by='openai-dev'), Model(id='text-davinci-003', created=1669599635, object='model', owned_by='openai-internal'),
...
...
Model(id='gpt-3.5-turbo-0613', created=1686587434, object='model', owned_by='openai'), Model(id='tts-1-1106', created=1699053241, object='model', owned_by='system'), Model(id='tts-1-hd-1106', created=1699053533, object='model', owned_by='system'), Model(id='dall-e-3', created=1698785189, object='model', owned_by='system')], object='list')
Conclusion
The workflow has three distinct identifiers: the uploaded file, the training job and the resulting model. Preparing good conversations and checking a held-out evaluation set matter as much as submitting the job.
The original GPT-3.5 code and dashboard captures remain useful for understanding that lifecycle. Before planning new work, check present training eligibility and model retirement dates. Use retrieval for changing facts and evaluate training for a measurable behavior change.
Happy Learning !!
