
JMH (Java Microbenchmark Harness) is the OpenJDK tool for measuring how long a small piece of Java code takes, such as one method, while it controls JIT warmup, separate JVM forks and the compiler optimizations that make hand-written timing loops wrong. The OpenJDK developers use JMH to benchmark the JDK itself.
We use JMH to compare two implementations of the same task, such as StringBuilder against + in a loop, to check that a change in a hot method did not make it slower, and to answer “which one is faster” questions with numbers instead of guesses.
The following example is a complete JMH benchmark that measures String.join() for an array of 1,000 words.
@State(Scope.Thread)
@BenchmarkMode(Mode.AverageTime)
@OutputTimeUnit(TimeUnit.MICROSECONDS)
public class JoinBenchmark {

    String[] words = new String[1000];

    @Setup
    public void fill() {
        Arrays.setAll(words, i -> "word" + i);
    }

    @Benchmark
    public String join() {
        return String.join("", words);     // returned, so the JIT cannot remove it
    }
}
mvn clean verify
java -jar target/benchmarks.jar JoinBenchmarkNotice that the method returns its result, and that the input array lives in a state object filled by @Setup. JMH generates the timing loop around join(), so we never write System.nanoTime() ourselves. We set up a project with the Maven archetype, fix the annotation processing step that Java 23 and later need, read a real result table, and go through modes, forks, state scopes and the pitfalls that make benchmarks lie.
1. Why a Timing Loop with System.nanoTime() Gives Wrong Numbers
A naive benchmark calls a method a million times between two System.nanoTime() calls and divides the time. The number it prints is rarely the time the method takes in production, because the JVM keeps changing the code while the loop runs.
- The first calls run in the bytecode interpreter, and the JIT compilers (C1 first, C2 later) compile the method only after it becomes hot, so early calls are far slower than later ones.
- The JIT removes code whose result is never used, which is called dead code elimination, so a loop that ignores the result can measure nothing at all.
- The JIT computes expressions on constants at compile time, which is called constant folding, so Math.log(42) may become a fixed number.
- Garbage collection, CPU frequency changes and other processes add noise, and one run on one JVM shows only one sample of that noise.
JMH handles these problems for us. It runs warmup iterations before measuring, starts fresh JVM forks so that one run’s JIT decisions do not leak into the next, consumes results so the JIT cannot drop them, and reports an error margin for every score.
2. Creating a JMH Project with the Maven Archetype
The JMH project recommends a separate Maven project for benchmarks, generated from its archetype. The project builds one executable benchmarks.jar that contains the benchmarks and the generated measurement code. The current version of jmh-core and jmh-generator-annprocess is 1.37.
mvn archetype:generate \
  -DinteractiveMode=false \
  -DarchetypeGroupId=org.openjdk.jmh \
  -DarchetypeArtifactId=jmh-java-benchmark-archetype \
  -DarchetypeVersion=1.37 \
  -DgroupId=com.howtodoinjava \
  -DartifactId=jmh-demo \
  -Dversion=1.0
2.1. Enabling the Annotation Processor on Java 23 and Later
JMH generates the measurement code from the @Benchmark annotations with an annotation processor. Since JDK 23, javac no longer runs annotation processors that it finds on the classpath unless the build asks for them, and the archetype’s pom.xml (which also targets Java 8) does not ask. The build succeeds, but running the jar fails.
$ java -jar target/benchmarks.jar -l
Exception in thread "main" java.lang.RuntimeException: ERROR: Unable to find the resource: /META-INF/BenchmarkList
	at org.openjdk.jmh.runner.AbstractResourceReader.getReaders(AbstractResourceReader.java:98)
	at org.openjdk.jmh.runner.BenchmarkList.find(BenchmarkList.java:124)
We fix it in the maven-compiler-plugin section of the generated pom.xml. The annotationProcessorPaths element names the JMH processor explicitly, and release sets the Java version. The same error and other causes are covered in Unable to find the resource /META-INF/BenchmarkList.
<plugin>
    <groupId>org.apache.maven.plugins</groupId>
    <artifactId>maven-compiler-plugin</artifactId>
    <version>3.16.0</version>
    <configuration>
        <release>25</release>
        <annotationProcessorPaths>
            <path>
                <groupId>org.openjdk.jmh</groupId>
                <artifactId>jmh-generator-annprocess</artifactId>
                <version>1.37</version>
            </path>
        </annotationProcessorPaths>
    </configuration>
</plugin>
After mvn clean verify, the command java -jar target/benchmarks.jar -l lists every benchmark it found. Gradle users get the same setup from the community jmh-gradle-plugin, which adds a src/jmh/java source set and a jmh task.
3. Writing a Benchmark with @State, @Param and @Setup
Say a reporting service builds a CSV line from hundreds of values, and a code review asks whether the += loop in that code is a real problem or a style comment. A benchmark answers it for the sizes the service sees. The following class compares three ways to join an array of words, for 10 and for 1,000 words.
@BenchmarkMode(Mode.AverageTime)
@OutputTimeUnit(TimeUnit.MICROSECONDS)
@Warmup(iterations = 3, time = 1)
@Measurement(iterations = 5, time = 1)
@Fork(2)
@State(Scope.Thread)
public class ConcatBenchmark {

    @Param({"10", "1000"})
    int size;

    String[] words;

    @Setup
    public void setUp() {
        words = new String[size];
        for (int i = 0; i < size; i++) {
            words[i] = "word" + i;
        }
    }

    @Benchmark
    public String plusInLoop() {
        String result = "";
        for (String word : words) {
            result += word;
        }
        return result;
    }

    @Benchmark
    public String stringBuilder() {
        StringBuilder sb = new StringBuilder();
        for (String word : words) {
            sb.append(word);
        }
        return sb.toString();
    }

    @Benchmark
    public String stringJoin() {
        return String.join("", words);
    }
}
Each annotation has one job.
- The @Benchmark annotation marks a public method that JMH measures.
- The @State(Scope.Thread) annotation makes the class a state object, so JMH creates one instance per benchmark thread and keeps its fields out of the measured code.
- The @Param annotation runs every benchmark once per listed value, and JMH converts the strings to the field type.
- The @Setup method runs before the measurement (once per trial by default), so building the input array is not part of the score.
- The @Warmup, @Measurement and @Fork annotations shorten the run for this article; the defaults are covered in section 5.
4. Reading the Result Table
JMH prints the progress of every iteration and ends with a summary table. The following output comes from a real run of ConcatBenchmark on JDK 25.0.4.1 with JMH 1.37, on a shared cloud VM with 2 virtual CPUs, so other processes added noise.
Benchmark                      (size)  Mode  Cnt    Score    Error  Units
ConcatBenchmark.plusInLoop         10  avgt   10    0.170 +-  0.014  us/op
ConcatBenchmark.plusInLoop       1000  avgt   10  530.689 +- 53.728  us/op
ConcatBenchmark.stringBuilder      10  avgt   10    0.535 +-  1.896  us/op
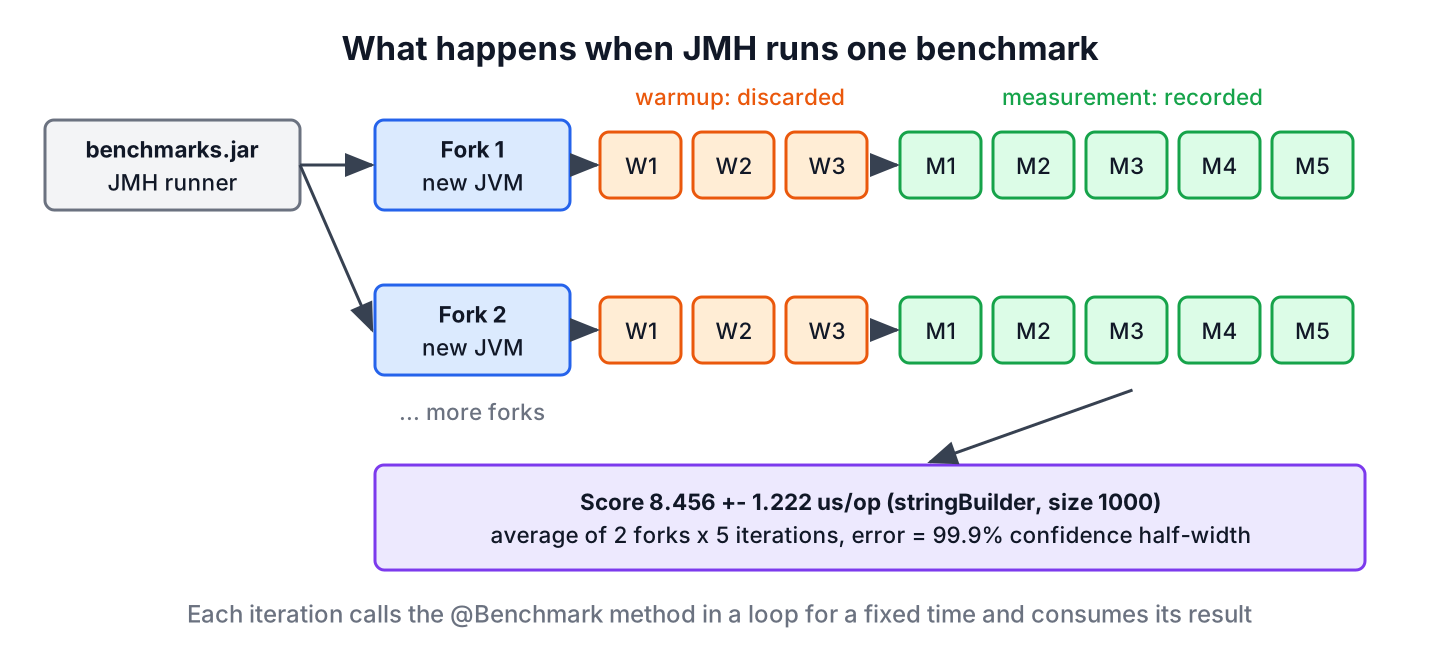
ConcatBenchmark.stringBuilder    1000  avgt   10    8.456 +-  1.222  us/op
ConcatBenchmark.stringJoin         10  avgt   10    0.110 +-  0.051  us/op
ConcatBenchmark.stringJoin       1000  avgt   10    9.141 +-  1.553  us/op
The columns tell us how to read each row.
| Column | Meaning |
|---|---|
| (size) | The @Param value of this row |
| Mode | avgt is average time per operation, thrpt is operations per time unit |
| Cnt | Number of measurement iterations in all forks, here 2 forks times 5 iterations |
| Score | The average result, here microseconds per call |
| Error | Half-width of the 99.9% confidence interval around the score |
| Units | The unit set by @OutputTimeUnit and the mode |
For 1,000 words, the += loop took about 530 microseconds per call against about 8 to 9 microseconds for StringBuilder and String.join(), because every += copies the whole string built so far. For 10 words, all three finish in well under a microsecond, so the review comment matters only for long inputs.
We compare scores only when their error ranges do not overlap. The stringBuilder row for 10 words has an error of 1.896 against a score of 0.535, which means the iterations varied wildly, most likely because of the shared VM. Such a row needs a rerun on a quiet machine, more iterations or more forks before anyone quotes it.
5. Warmup, Measurement and Forks
A JMH run of one benchmark is a trial. JMH starts a new JVM for each fork, runs the warmup iterations whose results it throws away, and runs the measurement iterations that make up the score. Each iteration calls the benchmark method in a loop for a fixed time.
| Annotation | What it sets | Default in JMH 1.37 | Command-line option |
|---|---|---|---|
| @Fork(value, warmups, jvmArgs) | Number of separate JVM processes | 5 forks | -f 5 |
| @Warmup(iterations, time, timeUnit) | Warmup iterations and their length | 5 iterations of 10 s | -wi 5 -w 10s |
| @Measurement(iterations, time, timeUnit) | Measured iterations and their length | 5 iterations of 10 s | -i 5 -r 10s |
| @Threads | Threads calling the benchmark at the same time | 1 | -t 4 |
With the defaults, one benchmark runs for about 8 minutes and 20 seconds (5 forks times 100 seconds), so a class with six parameter combinations takes close to an hour. Short settings such as those in section 3 are fine while writing a benchmark, and the published numbers come from a longer run. Command-line options override the annotations, as in java -jar target/benchmarks.jar ConcatBenchmark -f 3 -wi 5 -i 10.
Forks are separate processes, not threads. Each fork starts with a cold JIT and a new heap, so the result does not depend on what an earlier benchmark compiled. The jvmArgs element passes options such as -Xmx2g to the forked JVMs, and @Fork(0) runs inside the current JVM, which is useful for debugging and wrong for measuring.
6. Benchmark Modes and Time Units
The mode decides what JMH reports. We set it with @BenchmarkMode on the class or the method, and the unit with @OutputTimeUnit.
| Mode | Reports | Use it for |
|---|---|---|
| Mode.Throughput (default) | Operations per time unit, higher is better | Methods called very often, such as a parser |
| Mode.AverageTime | Average time per operation, lower is better | Comparing implementations |
| Mode.SampleTime | Time of sampled calls with percentiles such as p99 | Spotting slow outliers |
| Mode.SingleShotTime | Time of one call without a measurement loop | Cold start cost, such as the first call after startup |
| Mode.All | All of the above | Exploring a new benchmark |
The default unit for throughput is operations per second. For average and sample time, we pick a unit that keeps the numbers readable, such as NANOSECONDS for a getter and MILLISECONDS for parsing a large file.
7. State Scopes and Setup Levels
State objects hold the input data and any objects the benchmark needs. The scope decides how many instances JMH creates when a benchmark runs with several threads.
| Scope | Instances | Typical use |
|---|---|---|
| Scope.Thread | One per benchmark thread | Unshared inputs, the safe default |
| Scope.Benchmark | One shared by all threads | Measuring contention on a shared object, such as a ConcurrentHashMap |
| Scope.Group | One per thread group | Producer and consumer benchmarks with @Group |
Methods annotated with @Setup and @TearDown take a Level that says when they run. Level.Trial (the default) runs before and after each run of the benchmark in a fork, Level.Iteration runs before or after every iteration, and Level.Invocation runs around every single call. With Level.Invocation, JMH has to timestamp each call to subtract the setup time, which distorts the result of a small method, so we keep Level.Invocation for benchmark methods that take milliseconds, not nanoseconds.
8. Pitfalls That Make a Benchmark Lie
JMH removes the measurement problems, but the code inside a benchmark method can still let the JIT optimize away the work we want to measure. The JMH samples show each of the following pitfalls with code.
8.1. Dead Code Elimination
If the result of a computation is never used, the JIT may remove the computation. The first method in the following benchmark may measure an empty method, while the other two keep the work alive, either by returning the value, which JMH consumes for us, or by passing it to a Blackhole.
@State(Scope.Thread)
public class LogBenchmark {

    double x = Math.PI;

    @Benchmark
    public void wrong() {
        Math.log(x);                       // result unused, may be removed
    }

    @Benchmark
    public double returned() {
        return Math.log(x);
    }

    @Benchmark
    public void consumed(Blackhole bh) {
        bh.consume(Math.log(x));
        bh.consume(Math.log(x + 1));       // several results need a Blackhole
    }
}
Whether the JIT removes a particular call depends on the JDK version and the CPU, so we never rely on it either way. A score close to an empty @Benchmark method (well under a nanosecond) is the usual sign that the work was removed.
8.2. Constant Folding
If the inputs are constants, the JIT can compute the result once at compile time. A literal such as Math.log(42) or a final field initialized with a constant gives the JIT that chance, so we read inputs from non-final fields of a state object, as x is read in LogBenchmark.
8.3. Loops Inside the Benchmark Method
A loop such as for (int i = 0; i < 1000; i++) sum += i * factor; inside a benchmark lets the JIT unroll or vectorize it, so the time per element shrinks in ways that never happen with real data. We let JMH call the method repeatedly, and when a loop over input data is part of the task, as in ConcatBenchmark, we vary the input size with @Param instead of dividing by the loop count.
8.4. A Noisy Machine
Browsers, IDE indexing, other builds and laptop power saving all change the results. We run benchmarks on a quiet machine with the power profile set to performance, compare only results from the same machine, and watch the error column, as section 4 showed with the shared VM.
9. Running from Code, Profilers and Result Files
The jar is the recommended way to run benchmarks, and the command-line options cover most needs. For IDE runs, the Runner API starts the same runner from a main() method.
public class BenchmarkMain {

    public static void main(String[] args) throws RunnerException {
        Options options = new OptionsBuilder()
                .include(ConcatBenchmark.class.getSimpleName())
                .forks(1)
                .resultFormat(ResultFormatType.JSON)
                .result("concat.json")
                .build();
        new Runner(options).run();
    }
}
Profilers explain why one version is faster. The option -prof gc adds allocation rates and garbage collection counts to the table, which shows the extra garbage of the += loop, and java -jar target/benchmarks.jar -lprof lists all available profilers. The -rf json option writes a result file that tools such as JMH Visualizer can chart.
10. Java Microbenchmark Harness FAQs
Setup errors and odd numbers cause most JMH questions, from the missing BenchmarkList to scores below one nanosecond.
10.1. What is the difference between JMH and System.nanoTime()?
System.nanoTime() only reads a clock. JMH uses the clock too, but it adds warmup, forks, result consumption, statistics and an error margin, which a hand-written loop does not have, as section 1 explained.
10.2. Why does JMH report Unable to find the resource /META-INF/BenchmarkList?
The annotation processor did not run, so the generated benchmark list is missing from the jar. On JDK 23 and later, add jmh-generator-annprocess to annotationProcessorPaths, as shown in section 2.1, and rebuild.
10.3. Can I run JMH benchmarks in JUnit tests?
We can call the Runner API from a test, but the OpenJDK team recommends a separate benchmark project. Unit test runs are short, share the JVM with other tests and often run on busy CI agents, so their numbers are not reliable enough to fail a build on.
10.4. Why is my benchmark faster than 1 nanosecond?
The JIT most likely removed the work through dead code elimination or constant folding. Return the result or pass it to a Blackhole, and read inputs from a @State field.
10.5. How many forks and iterations should a benchmark use?
The defaults of 5 forks with 5 warmup and 5 measurement iterations of 10 seconds are a good start for published numbers. If the error stays large, add forks before adding iterations, because the variation between JVM runs is often bigger than the variation inside one run.
11. Conclusion
JMH measures small pieces of Java code with warmup iterations, separate forks and an error margin, which a System.nanoTime() loop cannot do. A project from the 1.37 archetype needs one change on Java 23 and later, namely the annotation processor in annotationProcessorPaths.
A good benchmark keeps inputs in @State objects, varies sizes with @Param, returns or consumes every result, and avoids its own loops. The result table is only as good as the machine it ran on, so we trust scores whose error ranges do not overlap and rerun the rest.
12. References
Happy Learning !!
