

Flogger is Google’s fluent logging API for Java, in which every log statement is a chain of method calls such as logger.atInfo().every(100).log(“Processed %d rows”, count). Flogger is only the API, so the messages go to a backend such as java.util.logging (the default), Log4j2 or SLF4J, which decides the format and the destination.
We use Flogger in services that log a lot and need features beyond plain levels, for example rate limiting a message that would otherwise appear thousands of times per minute, attaching a stack trace on demand, or skipping an expensive argument when the level is disabled. Google uses it as its recommended Java logging API.
The following example creates a FluentLogger in an import job and logs a message with two arguments.
public class ImportJob {
    private static final FluentLogger logger = FluentLogger.forEnclosingClass();

    void importFile(String file, int orders) {
        logger.atInfo().log("Imported %d orders from %s", orders, file);
    }
}
Oct 10, 2026 2:32:49 PM ImportJob importFile
INFO: Imported 120 orders from orders.csvNotice that the placeholders are printf style (%d, %s) and not the {} placeholders of SLF4J, and that the default backend prints in the java.util.logging format. We go through the dependencies, levels, exceptions, rate limiting and lazy arguments, explain why disabled statements cost almost nothing, and compare Flogger with the fluent API that SLF4J 2 added.
1. Flogger Dependencies
Flogger, similar to SLF4J, is an abstraction over a logging framework. Code depends on the flogger artifact, and the application adds one backend at runtime. The current version on Maven Central is 0.9, released in May 2025.
1.1. Flogger Core and the Default Backend
The flogger artifact contains FluentLogger and the API, and flogger-system-backend sends the messages to java.util.logging (JUL). Without any backend, FluentLogger.forEnclosingClass() throws an ExceptionInInitializerError caused by IllegalStateException: No logging platforms found, so the system backend is the safe default for small apps and tests.
<dependency>
    <groupId>com.google.flogger</groupId>
    <artifactId>flogger</artifactId>
    <version>0.9</version>
</dependency>

<!-- The java.util.logging backend -->
<dependency>
    <groupId>com.google.flogger</groupId>
    <artifactId>flogger-system-backend</artifactId>
    <version>0.9</version>
    <scope>runtime</scope>
</dependency>
1.2. Using Log4j2 or SLF4J as the Backend
Most applications already have a logging setup, such as log4j2.xml or a Logback file behind SLF4J. In that case we add the matching Flogger backend instead of the system backend, and the existing configuration controls levels, appenders and layouts.
<!-- Log4j2 backend -->
<dependency>
    <groupId>com.google.flogger</groupId>
    <artifactId>flogger-log4j2-backend</artifactId>
    <version>0.9</version>
    <scope>runtime</scope>
</dependency>

<!-- or the SLF4J backend -->
<dependency>
    <groupId>com.google.flogger</groupId>
    <artifactId>flogger-slf4j-backend</artifactId>
    <version>0.9</version>
    <scope>runtime</scope>
</dependency>
Flogger finds the backend with Java’s ServiceLoader, so the dependency alone is enough. If several backends are on the classpath, the system property flogger.backend_factory selects one, for example -Dflogger.backend_factory=com.google.common.flogger.backend.log4j2.Log4j2BackendFactory. The old flogger-log4j-backend targets Log4j 1.x, which reached end of life in 2015, so new projects skip it.
2. The FluentLogger API
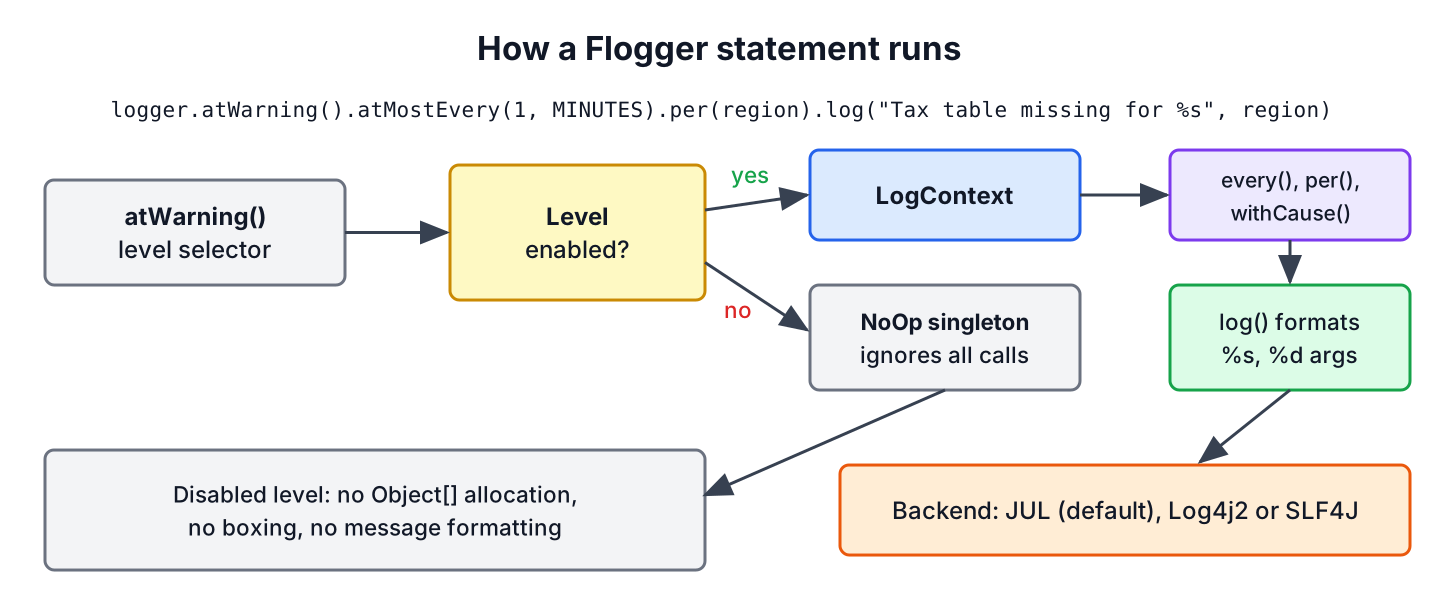
Every log statement follows the same shape. A level method such as atInfo() starts the chain, optional methods such as withCause() or every() add behavior, and log() ends it and writes the message.
2.1. Creating the Logger
We declare one logger per class as a private static final field and create it with FluentLogger.forEnclosingClass(), which is the recommended way to get a Flogger logger. The method finds the class name for us, so a copied logger line never logs under the wrong class name, which is a common mistake with getLogger(SomeOtherClass.class).
The message uses Java format specifiers such as %s, %d and %.2f. Flogger formats the message only when the statement is enabled, so we pass arguments instead of concatenating strings.
2.2. Log Levels
Flogger uses the levels of java.util.logging.Level, from SEVERE down to FINEST. Each common level has its own method, and at(Level) covers the case where the level is chosen at runtime.
| Method | JUL level | Typical use |
|---|---|---|
| atSevere() | SEVERE | A failure that needs attention, such as a stopped import |
| atWarning() | WARNING | A problem the code recovered from, such as a rejected row |
| atInfo() | INFO | Normal milestones, such as a finished import |
| atConfig() | CONFIG | Configuration values read at startup |
| atFine(), atFiner(), atFinest() | FINE to FINEST | Debug and trace details |
| at(Level.WARNING) | Any | Level decided at runtime |
The backend decides which levels are enabled. With the system backend, JUL prints INFO and above by default, so atFine() statements stay silent until we lower the level in logging.properties or in code. With Log4j2 or SLF4J, the level comes from their configuration files. The Log4j2 backend maps CONFIG and FINE to DEBUG, and FINER and FINEST to TRACE.
java.util.logging.Logger jul = java.util.logging.Logger.getLogger("ImportJob");
jul.setLevel(java.util.logging.Level.FINE);        // enables atFine() for this class
2.3. Logging Exceptions and Stack Traces
The withCause() method attaches an exception, and the backend prints its stack trace after the message. The withStackTrace() method adds the stack of the current log call even when there is no exception, which helps when we need to know which code path reached a statement.
public class RowValidator {
    private static final FluentLogger logger = FluentLogger.forEnclosingClass();

    void reject(int row, Exception cause) {
        logger.atWarning().withCause(cause).log("Rejected row %d", row);
    }

    void trace() {
        logger.atInfo().withStackTrace(StackSize.SMALL).log("Who called the validator?");
    }
}
Oct 10, 2026 2:32:49 PM RowValidator reject
WARNING: Rejected row 7
java.lang.IllegalStateException: price missing
at ImportApp.main(ImportApp.java:25)
Oct 10, 2026 2:32:49 PM RowValidator trace
INFO: Who called the validator?
com.google.common.flogger.LogSiteStackTrace: SMALL
at RowValidator.trace(ImportApp.java:11)
at ImportApp.main(ImportApp.java:26)The StackSize enum has five constants. SMALL, MEDIUM and LARGE capture an increasing number of frames, FULL captures the whole stack, and NONE captures nothing, which lets us switch the stack trace on and off with one variable such as withStackTrace(debug ? StackSize.MEDIUM : StackSize.NONE).
2.4. Rate Limiting with every(), atMostEvery() and per()
Rate limiting is the main reason teams pick Flogger. Say an import of 2 million rows logs a warning for every row without a tax rate. The log file grows by gigabytes, and the one useful line is lost. Flogger can log such a statement only every N calls or at most once per time period.
public class TaxLookup {
    enum Region { US, IN }

    private static final FluentLogger logger = FluentLogger.forEnclosingClass();

    void progress(int row) {
        logger.atInfo().every(10).log("Processed row %d", row);
    }

    void missingRate(Region region) {
        logger.atWarning()
                .atMostEvery(1, TimeUnit.MINUTES)
                .per(region)
                .log("Tax table missing for %s", region);
    }
}
TaxLookup lookup = new TaxLookup();
for (int row = 0; row < 25; row++) {
lookup.progress(row); // logs rows 0, 10 and 20
}
for (TaxLookup.Region region : List.of(TaxLookup.Region.US, TaxLookup.Region.US, TaxLookup.Region.IN)) {
lookup.missingRate(region); // logs US once and IN once
}INFO: Processed row 0 [CONTEXT ratelimit_count=10 ]
INFO: Processed row 10 [CONTEXT ratelimit_count=10 skipped=9 ]
INFO: Processed row 20 [CONTEXT ratelimit_count=10 skipped=9 ]
WARNING: Tax table missing for US [CONTEXT ratelimit_period="1 MINUTES" group_by="US" ]
WARNING: Tax table missing for IN [CONTEXT ratelimit_period="1 MINUTES" group_by="IN" ]We can see that the backend adds a [CONTEXT …] suffix with the limit and the number of skipped calls, so the reader knows that lines are missing. The per(region) call keeps a separate limit for each enum value, so a frequent US warning does not hide the first IN warning. For non-enum keys, the overload per(key, LogPerBucketingStrategy) takes a strategy that limits the number of buckets.
2.5. Lazy Arguments
Arguments are evaluated before log() runs, even when the level is disabled. For a cheap value that does not matter, but a call such as buildSummary() that walks a large collection wastes CPU on every disabled DEBUG statement. The static method LazyArgs.lazy() wraps the argument in a lambda that Flogger calls only when the message is logged.
public class ReportBuilder {
    private static final FluentLogger logger = FluentLogger.forEnclosingClass();
    static int summaryCalls = 0;

    static String buildSummary() {
        summaryCalls++;
        return "120 ok, 3 rejected";
    }

    void finish() {
        logger.atFine().log("Summary %s", LazyArgs.lazy(() -> buildSummary()));
    }
}
new ReportBuilder().finish();
int calls = ReportBuilder.summaryCalls; // 0, FINE is disabled
boolean fine = FluentLogger.forEnclosingClass().atFine().isEnabled(); // falseThe isEnabled() method answers the same question for a whole block of code, but lazy() keeps the log statement on one line, so we prefer it for single arguments.
3. Why Disabled Flogger Statements Cost Almost Nothing
Classic logging APIs have methods such as info(String, Object…). Every call allocates an Object[] for the varargs and boxes primitive arguments such as int, and this work happens before the method can check the level, so a disabled statement still allocates memory.
Flogger checks the level first. When atFine() finds the level disabled, it returns a shared no-op object whose methods ignore all arguments. The no-op object is immutable and thread-safe, so the same instance is reused, and log() has overloads for up to ten arguments, including variants with int, long and boolean parameters, so the common cases avoid varargs and boxing.
The saving matters in hot loops with many disabled DEBUG statements, and it does not matter for a few INFO lines per request. SLF4J’s {} placeholders already avoid string building for disabled levels, so for most applications the difference between the APIs is the feature set, not the speed.
4. Flogger vs the SLF4J 2 Fluent API
SLF4J 2.0 added a fluent logging API with methods such as atInfo(), addArgument(), addKeyValue() and setCause(). Teams that already use SLF4J get fluent statements without a new dependency, so the decision is whether Flogger adds anything beyond that.
public class SlfImportJob {
    private static final org.slf4j.Logger log = org.slf4j.LoggerFactory.getLogger(SlfImportJob.class);

    void finish(String file, int orders, Exception problem) {
        log.atInfo().setMessage("Imported {} orders from {}").addArgument(orders).addArgument(file).log();
        log.atInfo().addKeyValue("file", file).addKeyValue("orders", orders).log("Import finished");
        log.atWarn().setCause(problem).log("Rejected row {}", 7);
    }
}
[main] INFO SlfImportJob - Imported 120 orders from orders.csv
[main] INFO SlfImportJob - file=orders.csv orders=120 Import finished
[main] WARN SlfImportJob - Rejected row 7
java.lang.IllegalStateException: price missingThe output comes from slf4j-simple 2.0.20, which prints key-value pairs before the message. Logback and Log4j2 can write them as separate JSON fields instead, which helps log search tools.
| Feature | Flogger 0.9 | SLF4J 2.0 fluent API |
|---|---|---|
| Placeholders | printf style, %s and %d | {} |
| Rate limiting | every(), atMostEvery(), per() | No |
| Lazy arguments | LazyArgs.lazy() | addArgument(Supplier) |
| Key-value pairs | Metadata API, less common | addKeyValue() |
| Stack trace without exception | withStackTrace() | No |
| Exception | withCause() | setCause() |
| Backends | JUL, Log4j2, SLF4J | Logback, Log4j2, JUL, simple and more |
| Typical user | Google projects, libraries that log heavily | Most Spring Boot and Jakarta EE apps |
We pick Flogger when rate limiting or call-site stack traces solve a real problem, such as a noisy batch job. For a Spring Boot application, which logs through SLF4J and Logback already, the SLF4J 2 fluent API covers fluent statements and structured key-value logging without another library, as described in SLF4J vs Log4j.
5. Status and Compatibility
Flogger is open source under the Apache 2.0 license and lives in the google/flogger repository. Release 0.9 came out in May 2025, about a year and a half after 0.8, so releases are infrequent, and the version number has not reached 1.0. The examples in this article run on Java 25 with Flogger 0.9 and the system backend, and version 0.9 depends on the small org.jspecify:jspecify annotations library, which Maven adds for us.
The slow release pace is a reason to keep Flogger calls behind the logger field of each class and not to spread backend-specific code. Switching from Flogger to SLF4J later means rewriting the log statements, because the placeholder syntax differs.
6. Flogger FAQs
Rate limiting and the choice between Flogger and SLF4J lead the questions about Flogger, followed by backend setup.
6.1. Is Flogger better than SLF4J?
Not in general, because it depends on the features we need. Flogger has built-in rate limiting and call-site stack traces, and SLF4J has wider framework support and {} placeholders that every Java developer knows. For a typical Spring Boot app, SLF4J 2 is enough, and for a batch job that floods its logs, Flogger’s atMostEvery() helps.
6.2. How do I change the log level when using Flogger?
We change it in the backend. With the system backend, we set the level in logging.properties or call java.util.logging.Logger.getLogger(name).setLevel(), and with Log4j2 or SLF4J we use log4j2.xml or logback.xml. Flogger has no level setting of its own.
6.3. Why does Flogger throw No logging platforms found?
The flogger artifact contains only the API, so the first logger creation fails with IllegalStateException when no backend is present. Add flogger-system-backend or another backend to the runtime classpath, as shown in section 1.
6.4. Can Flogger log only once every few seconds?
Yes. The call atMostEvery(5, TimeUnit.SECONDS) logs the statement at most once per 5 seconds, and combining it with per(key) keeps a separate limit for each key, such as each region or customer type.
6.5. Does Flogger work with Spring Boot?
Yes. Add flogger-slf4j-backend, and the messages go through SLF4J to Logback, so the Spring Boot logging properties apply. The placeholders inside the code stay in printf style.
7. Conclusion
Flogger writes each log statement as a chain that starts with a level method and ends with log(). Disabled statements return a shared no-op object, and the API adds rate limiting, lazy arguments and call-site stack traces that classic logging APIs do not have.
Version 0.9 runs on Java 25 with JUL, Log4j2 or SLF4J as the backend. When an application already uses SLF4J and does not need rate limiting, the SLF4J 2 fluent API gives a similar style without another dependency.
8. References
- Flogger documentation
- Flogger best practices
- Anatomy of a logging API (Flogger)
- Flogger on GitHub
- SLF4J manual, fluent logging API
Happy Learning !!

LoggerConfig not exist in version 0.7.4
Thanks for sharing. I have updated the article.