

The Java DOM parser reads the whole XML file into memory as a tree of objects. The tree is called the Document, and we can read any element, text or attribute from it in any order. The parser comes with the JDK in the java.xml module, so we need no Maven dependency.
We use the DOM parser for XML files that fit in memory and that we read as a whole, such as a config file or an XML response from a partner API.
The following example reads a recipes.xml file. We create a DocumentBuilder from a DocumentBuilderFactory, call parse() to get the Document, and find elements by name with getElementsByTagName().
DocumentBuilderFactory factory = DocumentBuilderFactory.newInstance();
factory.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);  // blocks XXE
DocumentBuilder builder = factory.newDocumentBuilder();

Document doc = builder.parse(new File("recipes.xml"));
doc.getDocumentElement().normalize();

String root = doc.getDocumentElement().getNodeName();    // recipes
NodeList recipes = doc.getElementsByTagName("recipe");   // 2 elements

for (int i = 0; i < recipes.getLength(); i++) {
  Element recipe = (Element) recipes.item(i);
  String id = recipe.getAttribute("id");                                        // "1"
  String name = recipe.getElementsByTagName("name").item(0).getTextContent();   // "Pasta"
  String minutes = recipe.getElementsByTagName("minutes").item(0).getTextContent();
  System.out.println(id + " " + name + " " + minutes);
}
1 Pasta 20
2 Dal 35Notice that the setFeature() line blocks XXE attacks, so we keep it in every factory that reads XML from outside.
We first look at the DOM tree itself, including the whitespace text nodes that getChildNodes() returns, what normalize() does, and how getTextContent() differs from getNodeValue(). After that, we read attributes and nested elements into Java records, parse XML from a String or an InputStream, pick values with XPath, block XXE attacks, and compare DOM with SAX and StAX.
1. What Is the DOM Parser in Java?
DOM (Document Object Model) is a W3C standard that describes an XML document as a tree of nodes, where a node is any part of the document. An element is a node, and so are the text inside an element, an attribute and a comment. The JDK implements the standard in the org.w3c.dom package, and the parser that builds the tree is in javax.xml.parsers.
Four node types cover almost everything we read from a normal XML file.
| Node type | Example in recipes.xml | Read it with |
|---|---|---|
| Document | the whole file | builder.parse(file) |
| Element | recipe, name, ingredient | getElementsByTagName(“name”), getTagName() |
| Text | Pasta, and the line breaks between tags | getTextContent(), getNodeValue() |
| Attr | id=”1″, cuisine=”italian” | getAttribute(“id”) |
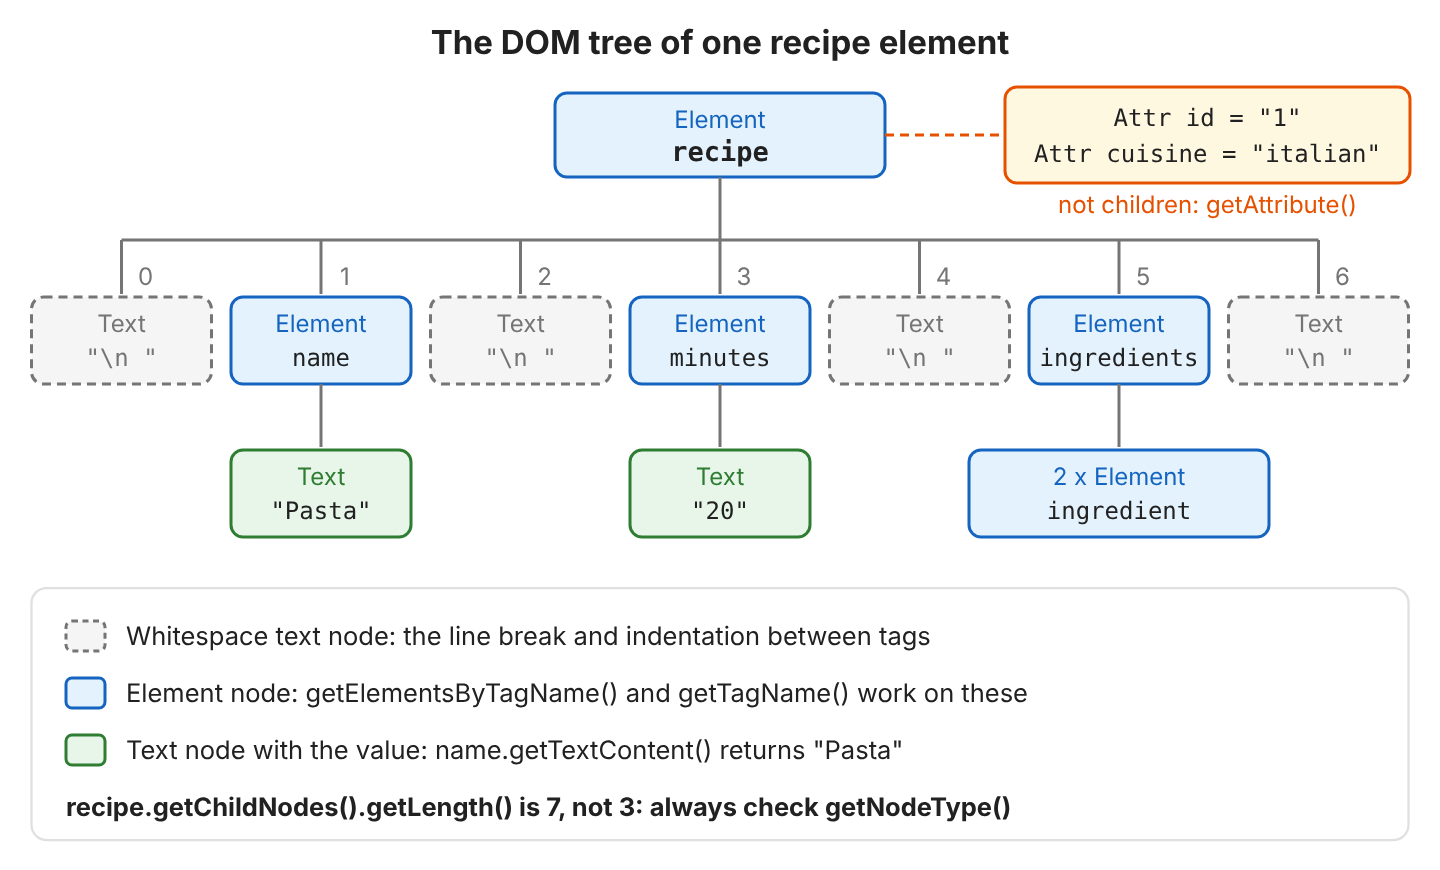
The tree for one recipe element shows a detail that surprises most developers, because the line breaks and spaces between tags become text nodes too.
1.1. The recipes.xml File and a Builder Method
Our recipes.xml belongs to a small cooking app and has two recipes. Each recipe has two attributes, id and cuisine, two simple child elements, name and minutes, and a nested list of ingredients, where each ingredient has a qty attribute for the quantity.
<?xml version="1.0" encoding="UTF-8"?>
<recipes>
  <recipe id="1" cuisine="italian">
    <name>Pasta</name>
    <minutes>20</minutes>
    <ingredients>
      <ingredient qty="200g">spaghetti</ingredient>
      <ingredient qty="2">tomato</ingredient>
    </ingredients>
  </recipe>
  <recipe id="2" cuisine="indian">
    <name>Dal</name>
    <minutes>35</minutes>
    <ingredients>
      <ingredient qty="1 cup">lentils</ingredient>
      <ingredient qty="1 tsp">turmeric</ingredient>
    </ingredients>
  </recipe>
</recipes>
Every snippet in this article needs a parser with the same security setting, so we put the factory setup in one method. The method returns a new DocumentBuilder on each call, so two threads never share a builder.
static DocumentBuilder newBuilder() throws ParserConfigurationException {
  DocumentBuilderFactory factory = DocumentBuilderFactory.newInstance();
  factory.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);
  return factory.newDocumentBuilder();
}
1.2. Whitespace Text Nodes in getChildNodes()
The method getChildNodes() returns every child node, not only the elements. In our file, each child tag starts on a new, indented line, and the line break and spaces are text too. So the indentation before name, minutes, ingredients and the closing tag becomes four extra text nodes.
Document doc = newBuilder().parse(new File("recipes.xml"));
Element pasta = (Element) doc.getElementsByTagName("recipe").item(0);
NodeList children = pasta.getChildNodes();
int count = children.getLength();    // 7
Printing the type and the content of each child shows the text nodes between the elements.
0 TEXT [\n    ]
1 ELEMENT [name]
2 TEXT [\n    ]
3 ELEMENT [minutes]
4 TEXT [\n    ]
5 ELEMENT [ingredients]
6 TEXT [\n  ]
A loop over getChildNodes() must check getNodeType() before it casts a node to Element. Without the check, the cast throws a ClassCastException on the first text node, so we use a small helper method that keeps only the child elements.
static List<Element> childElements(Element parent) {
  List<Element> result = new ArrayList<>();
  for (Node n = parent.getFirstChild(); n != null; n = n.getNextSibling()) {
    if (n.getNodeType() == Node.ELEMENT_NODE) {
      result.add((Element) n);
    }
  }
  return result;
}
The helper returns the three elements and skips the four text nodes.
Document doc = newBuilder().parse(new File("recipes.xml"));
Element pasta = (Element) doc.getElementsByTagName("recipe").item(0);
int elementCount = childElements(pasta).size();   // 3
The class DocumentBuilderFactory also has a method called setIgnoringElementContentWhitespace(true), but the setting works only with a validating parser (a parser that checks the XML against a set of rules) and a DTD (Document Type Definition). The DTD must declare which elements contain only other elements. Without a DTD, the setting has no effect, and the recipe still has 7 child nodes.
1.3. What Does normalize() Do?
Many examples call doc.getDocumentElement().normalize() right after parse(). The method merges adjacent text nodes into one text node and removes empty text nodes. The method normalize() does not remove the whitespace text nodes, so the recipe still has 7 child nodes afterwards.
Adjacent text nodes appear when our code changes the tree. In the following snippet, appendChild() adds a second text node to name, and normalize() joins the two.
Document doc = newBuilder().parse(new InputSource(new StringReader("<name>Pasta</name>")));
Element name = doc.getDocumentElement();
int before = name.getChildNodes().getLength();          // 1

name.appendChild(doc.createTextNode(" Bake"));
int afterAppend = name.getChildNodes().getLength();     // 2
String first = name.getFirstChild().getNodeValue();     // Pasta

doc.normalize();
int afterNormalize = name.getChildNodes().getLength();  // 1
String merged = name.getFirstChild().getNodeValue();    // Pasta Bake
On JDK 25, the parser already returns one text node for each piece of text, so normalize() after parse() changes nothing. Keeping the call does no harm because it is cheap, and it protects code that reads getFirstChild().getNodeValue() in case another parser splits the text into several nodes.
1.4. getTextContent() vs getNodeValue()
The Node interface has two methods that sound alike, but for an element they return different things.
| Call | Result | Why |
|---|---|---|
| name.getTextContent() | Pasta | text of the element and of everything inside it |
| name.getNodeValue() | null | an element has no value of its own |
| name.getFirstChild().getNodeValue() | Pasta | the value of the Text child node |
| ingredients.getTextContent() | “\n spaghetti\n tomato\n “ | all text inside, whitespace included |
| emptyName.getTextContent() for <name/> | “” (empty string) | no text child |
| emptyName.getFirstChild() for <name/> | null | no child node at all |
We use getTextContent() for elements and call strip() on the result. When the XML has line breaks inside the tag, such as <name>\n Pasta\n</name>, getTextContent() returns the line breaks too, and strip() removes them and leaves Pasta. The method getNodeValue() is useful only on Text and Attr nodes.
Document doc = newBuilder().parse(new File("recipes.xml"));
Element name = (Element) doc.getElementsByTagName("name").item(0);
String content = name.getTextContent();                  // Pasta
String elementValue = name.getNodeValue();               // null
String textValue = name.getFirstChild().getNodeValue();  // Pasta
2. Reading an XML File with the DOM Parser
The following example reads the recipes of the cooking app from section 1.1. The example uses Java 25 and only JDK classes, and the complete code is in the Core-Java repository on GitHub. Every snippet starts from the Document that newBuilder().parse() returns.
2.1. Reading Attributes
The method getAttribute() returns the attribute value as a String. For a missing attribute, it returns an empty string, not null, so when we must tell a missing attribute from an empty one, we call hasAttribute().
Document doc = newBuilder().parse(new File("recipes.xml"));
Element pasta = (Element) doc.getElementsByTagName("recipe").item(0);

String idText = pasta.getAttribute("id");             // "1"
String spicy = pasta.getAttribute("spicy");           // "" (missing attribute)
boolean hasSpicy = pasta.hasAttribute("spicy");       // false
Attr spicyNode = pasta.getAttributeNode("spicy");     // null
int id = Integer.parseInt(pasta.getAttribute("id"));  // 1
When we do not know the attribute names in advance, getAttributes() gives us all of them. It returns a NamedNodeMap, a collection that holds one Attr node per attribute and that we can read by index or by name.
Document doc = newBuilder().parse(new File("recipes.xml"));
Element pasta = (Element) doc.getElementsByTagName("recipe").item(0);
NamedNodeMap attrs = pasta.getAttributes();
for (int i = 0; i < attrs.getLength(); i++) {
  Node attr = attrs.item(i);
  System.out.println(attr.getNodeName() + " = " + attr.getNodeValue());
}
cuisine = italian
id = 1The JDK returns the attributes in alphabetical order, not in the order of the file. The DOM standard does not define any order, so our code must not depend on the position of an attribute. When we need one attribute of a matching element, XPath can get an attribute value in one expression.
2.2. Reading Nested Elements
The method getElementsByTagName() searches at any depth, not only in the direct children, starting from the object we call it on. When we call it on the document, it finds the tags in the whole file. When we call it on one element, it finds only the tags inside that element.
Document doc = newBuilder().parse(new File("recipes.xml"));
int all = doc.getElementsByTagName("ingredient").getLength();   // 4 (both recipes)

Element dal = (Element) doc.getElementsByTagName("recipe").item(1);
NodeList ingredients = dal.getElementsByTagName("ingredient");
int dalCount = ingredients.getLength();                         // 2 (only Dal)

for (int i = 0; i < ingredients.getLength(); i++) {
  Element ing = (Element) ingredients.item(i);
  System.out.println(ing.getAttribute("qty") + " " + ing.getTextContent());
}
1 cup lentils
1 tsp turmericWhen a tag is missing, item(0) returns null, so the chained getTextContent() call throws a NullPointerException. The JDK includes a helpful message that names the failing call.
NullPointerException: Cannot invoke "org.w3c.dom.Node.getTextContent()" because the return value of "org.w3c.dom.NodeList.item(int)" is nullA helper method handles both problems in one place, because it returns null for a missing tag and strips the text. For example, older recipe files have no rating element, and the helper returns null for them instead of throwing.
static String text(Element parent, String tag) {
  Node node = parent.getElementsByTagName(tag).item(0);
  return node == null ? null : node.getTextContent().strip();
}
We call the helper with the tag name, the same way for present and missing tags.
Document doc = newBuilder().parse(new File("recipes.xml"));
Element dal = (Element) doc.getElementsByTagName("recipe").item(1);
String dalName = text(dal, "name");     // "Dal"
String rating = text(dal, "rating");    // null
2.3. Walking the Whole Tree
When we do not know the structure of the XML in advance, a recursive method can visit every element by calling itself once for each child element. It prints the attributes of each element and, for leaf elements (elements with no child elements), the text as well. The childElements() helper from section 1.2 skips the whitespace nodes.
static void printElement(Element element, int depth) {
  StringBuilder line = new StringBuilder("  ".repeat(depth)).append(element.getTagName());
  NamedNodeMap attrs = element.getAttributes();
  for (int i = 0; i < attrs.getLength(); i++) {
    line.append(" @").append(attrs.item(i).getNodeName())
        .append('=').append(attrs.item(i).getNodeValue());
  }
  List<Element> children = childElements(element);
  if (children.isEmpty()) {
    line.append(" = ").append(element.getTextContent().strip());
  }
  System.out.println(line);
  for (Element child : children) {
    printElement(child, depth + 1);
  }
}
We start the walk at the root element with depth 0.
Document doc = newBuilder().parse(new File("recipes.xml"));
printElement(doc.getDocumentElement(), 0);
recipes
recipe @cuisine=italian @id=1
name = Pasta
minutes = 20
ingredients
ingredient @qty=200g = spaghetti
ingredient @qty=2 = tomato
recipe @cuisine=indian @id=2
name = Dal
minutes = 35
ingredients
ingredient @qty=1 cup = lentils
ingredient @qty=1 tsp = turmeric2.4. Reading XML into a List of Records
In real code, we rarely print the XML, and we turn it into Java objects instead. Java records fit this job well, because a record is a compact data class whose fields cannot change.
record Ingredient(String name, String qty) {}

record Recipe(int id, String cuisine, String name, int minutes, List<Ingredient> ingredients) {}
An outer loop reads the recipes, and an inner loop reads the ingredients of each recipe. The inner loop calls getElementsByTagName() on the recipe element, not on the document, so each recipe gets only its own ingredients.
Document doc = newBuilder().parse(new File("recipes.xml"));
List<Recipe> result = new ArrayList<>();
NodeList nodes = doc.getElementsByTagName("recipe");

for (int i = 0; i < nodes.getLength(); i++) {
  Element r = (Element) nodes.item(i);

  List<Ingredient> ingredients = new ArrayList<>();
  NodeList ingNodes = r.getElementsByTagName("ingredient");
  for (int j = 0; j < ingNodes.getLength(); j++) {
    Element ing = (Element) ingNodes.item(j);
    ingredients.add(new Ingredient(ing.getTextContent().strip(), ing.getAttribute("qty")));
  }

  result.add(new Recipe(
      Integer.parseInt(r.getAttribute("id")),
      r.getAttribute("cuisine"),
      text(r, "name"),
      Integer.parseInt(text(r, "minutes")),
      List.copyOf(ingredients)));
}

List<String> quick = result.stream().filter(r -> r.minutes() < 30).map(Recipe::name).toList();   // [Pasta]
Printing the list shows both records with their ingredients.
Recipe[id=1, cuisine=italian, name=Pasta, minutes=20, ingredients=[Ingredient[name=spaghetti, qty=200g], Ingredient[name=tomato, qty=2]]]
Recipe[id=2, cuisine=indian, name=Dal, minutes=35, ingredients=[Ingredient[name=lentils, qty=1 cup], Ingredient[name=turmeric, qty=1 tsp]]]
Once the data is in records, the usual Java tools work on it, as the stream in the last line shows. For larger documents with a fixed structure, a JAXB Unmarshaller creates the objects from annotations on our classes, so we write no loops.
2.5. Parsing XML From a String or an InputStream
The method DocumentBuilder.parse() has overloads (versions of the method with different parameter types) that take a File, an InputStream, a URI String or an InputSource. When the XML is already in a String, such as an HTTP response body, we wrap the string in a StringReader and the reader in an InputSource. A text block keeps the XML readable.
String xml = """
    <recipe id="3" cuisine="mexican">
      <name>Tacos</name>
      <minutes>15</minutes>
    </recipe>""";

Document doc = newBuilder().parse(new InputSource(new StringReader(xml)));
String cuisine = doc.getDocumentElement().getAttribute("cuisine");   // "mexican"
A common mistake is to pass the XML string straight to parse(String). This overload expects a URI (the address of a file or a web page), so the parser tries to open the XML text as a URL and fails.
String xml = "<recipe id=\"3\"><name>Tacos</name></recipe>";
Document wrong = newBuilder().parse(xml);   // MalformedURLException: no protocol: <recipe id="3"><name>Tacos</name></recipe>
For bytes from a file, a socket or the classpath, an InputStream is the better choice, because the parser reads the encoding from the XML declaration on the first line of the file. The next snippet opens the file with Files.newInputStream() and closes the stream in a try-with-resources block. For a file inside the JAR, we read it from the resources folder with getResourceAsStream() in the same way.
try (InputStream in = Files.newInputStream(Path.of("recipes.xml"))) {
  Document doc = newBuilder().parse(in);
  int count = doc.getElementsByTagName("recipe").getLength();   // 2
}
We can also convert a String to XML and back, and save a changed Document by writing XML to a file.
3. XPath, the Shorter Alternative
XPath is a query language for XML, where an expression describes the path to the nodes we want, much like a file path. The JDK includes an XPath engine in javax.xml.xpath that works on the same Document the DOM parser built, so one XPath expression often replaces a loop with several getElementsByTagName() calls and if checks.
Document doc = newBuilder().parse(new File("recipes.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();

String dalName = xpath.evaluate("/recipes/recipe[@id='2']/name", doc);    // "Dal"
String quick = xpath.evaluate("//recipe[minutes < 30]/name", doc);        // "Pasta"
String qty = xpath.evaluate("//ingredient[.='lentils']/@qty", doc);       // "1 cup"
String countText = xpath.evaluate("count(//ingredient)", doc);            // "4"
Double count = xpath.evaluateExpression("count(//ingredient)", doc, Double.class);   // 4.0

NodeList names = (NodeList) xpath.evaluate("//recipe/name", doc, XPathConstants.NODESET);
int nameCount = names.getLength();                                        // 2
The method evaluate() returns the text of the first match as a String, whereas evaluateExpression(), added in Java 9, returns a result of the type we ask for, such as Double. One of the result types, XPathNodes, works in a for-each loop. We use DOM methods when we walk through the tree or change it, and XPath when we pick a few values by a condition. The Java XPath syntax also has functions such as contains() and starts-with() for text conditions.
4. Securing the DOM Parser Against XXE
An XXE (XML External Entity) attack uses an XML feature called entities (named pieces of content declared in a DOCTYPE at the top of the file). An external entity points to a local file or a URL. When the attacker sends XML with an external entity, a default DocumentBuilderFactory reads the file behind the entity and copies its content into the document.
Say a recipe-sharing site accepts recipe uploads as XML. An attacker uploads a recipe whose name is an entity that points to a file with a database password. On JDK 25 with default settings, the parse succeeds, and the name element holds the content of that file, whereas the factory with the disallow-doctype-decl feature rejects the upload.
String xml = """
    <!DOCTYPE recipe [
      <!ENTITY secret SYSTEM "file:///etc/recipes/secret.txt">
    ]>
    <recipe><name>&secret;</name></recipe>""";

Document unsafe = DocumentBuilderFactory.newInstance().newDocumentBuilder()
    .parse(new InputSource(new StringReader(xml)));
String leaked = unsafe.getDocumentElement().getTextContent();   // "db.password=tiger"

Document safe = newBuilder().parse(new InputSource(new StringReader(xml)));   // SAXParseException: DOCTYPE is disallowed
For XML from any untrusted source, we disallow DOCTYPE declarations completely. Normal data XML, such as API payloads, uploads and config files, has no DOCTYPE, so turning on this feature costs nothing there. With the feature on, the parser rejects the document before reading any entity.
org.xml.sax.SAXParseException: DOCTYPE is disallowed when the feature "http://apache.org/xml/features/disallow-doctype-decl" set to true.The default error handler also prints [Fatal Error] :1:10: with the same message to System.err, and we can replace it by calling builder.setErrorHandler(). Some applications must accept a DOCTYPE, so the table compares the other settings against the same attack on JDK 25.
| Setting | Result |
|---|---|
| none (default factory) | parsed, text = db.password=tiger |
| setFeature(“…/disallow-doctype-decl”, true) | SAXParseException: DOCTYPE is disallowed … |
| setFeature(XMLConstants.FEATURE_SECURE_PROCESSING, true) | SAXParseException: External Entity: Failed to read external document ‘secret.txt’, because ‘file’ access is not allowed due to restriction set by the accessExternalDTD property. |
| setAttribute(XMLConstants.ACCESS_EXTERNAL_DTD, “”) plus ACCESS_EXTERNAL_SCHEMA | same message as FEATURE_SECURE_PROCESSING |
| external-general-entities and external-parameter-entities set to false | parsed, entity ignored, text = “” |
Another attack is the entity expansion bomb, also called “billion laughs”, where entities refer to other entities many levels deep until the text grows to gigabytes. The JDK limits this attack even with the default factory. Since JDK 24, the limit is 2,500 expansions, and the parse fails with JAXP00010001: The parser has encountered more than “2500” entity expansions in this document; this is the limit imposed by “jdk.xml.entityExpansionLimit”. Other Java parsers, such as SAXParserFactory and XMLInputFactory, need the same XXE prevention settings.
5. DOM vs SAX vs StAX
The JDK has three ways to read XML. DOM builds the whole tree in memory, whereas SAX (Simple API for XML) reads the file from top to bottom and calls a method in our handler class at each event, such as “element started”, so the parser pushes events to our code. StAX (Streaming API for XML) works the other way, because our own loop pulls the next event from the parser.
Neither streaming parser holds the whole document in memory, which matters for large files. The chart shows the heap (the memory for Java objects) used to read a generated 46 MB file with 200,000 recipes.
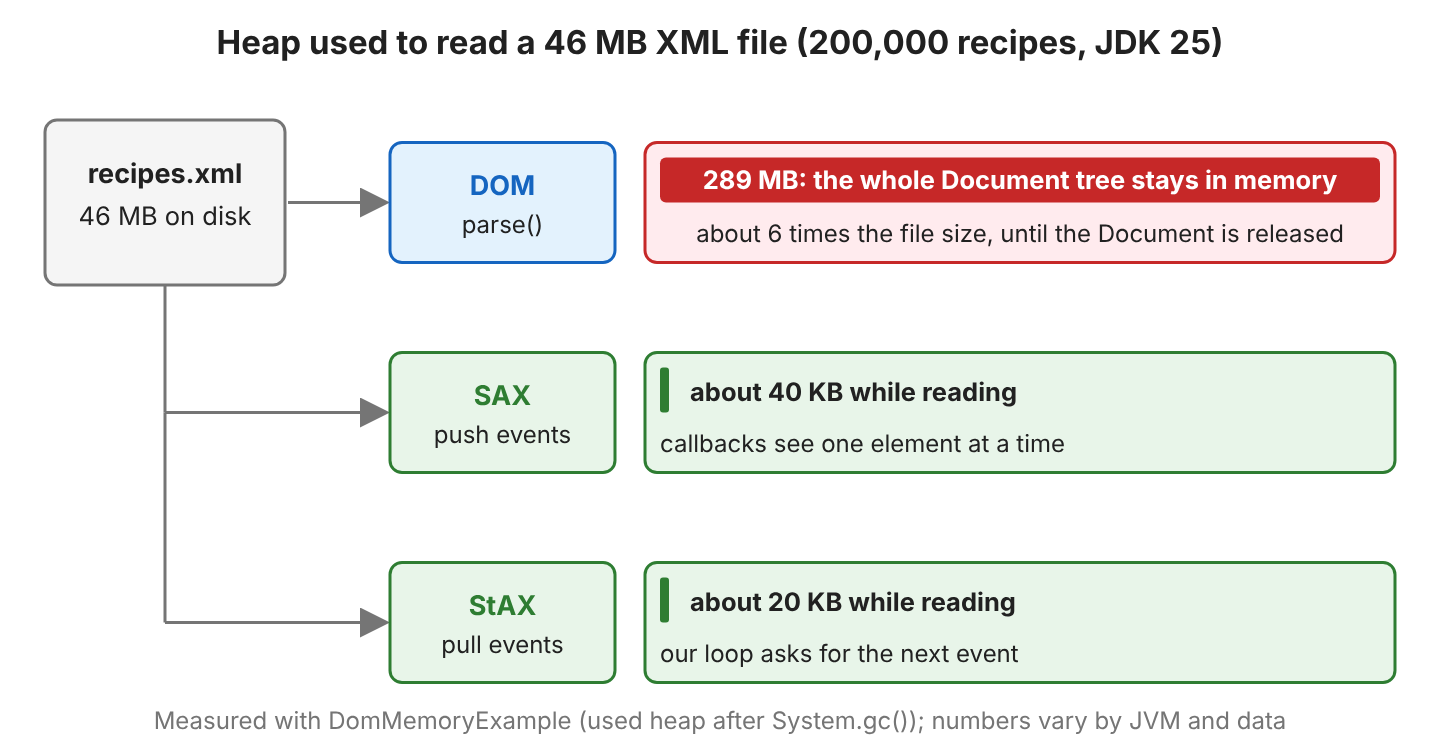
The numbers come from the used heap after System.gc() on JDK 25, so they are rough, but the ratio is typical. A DOM tree needs several times the file size in heap. The right choice depends on the file size and on what the code does with the data.
| DOM | SAX | StAX | |
|---|---|---|---|
| How it reads | whole tree in memory | parser calls our handler (push) | our loop asks for the next event (pull) |
| Heap for the 46 MB file | 289 MB | about 40 KB | about 20 KB |
| Go back or jump to any node | yes | no | no |
| XPath queries | yes | no | no |
| Change and write the XML | yes | no | writing through XMLStreamWriter |
| JDK entry point | DocumentBuilder | SAXParser | XMLStreamReader |
| Good for | config files and API responses up to a few MB | huge files read once | huge files when we want control of the loop |
For a nightly export of all recipes, we read the data with a SAX parser or a StAX parser instead, and the trade-offs of DOM vs SAX parser decide which one fits.
6. DOM Parser FAQs
Most problems with the DOM parser show up as an empty result, a threading bug or a schema question.
6.1. Why Does getElementsByTagName() Return 0 Elements?
The cause is either the letter case or a namespace. XML names are case-sensitive, so getElementsByTagName(“Recipe”) returns 0 for <recipe>. A namespace is a URI that groups element names, and the file refers to it with a short prefix, as in <r:recipe xmlns:r=”https://example.com/recipes”>. A default factory matches only the full name with the prefix.
String xml = """
    <r:recipe xmlns:r="https://example.com/recipes" id="1"/>""";
Document doc = newBuilder().parse(new InputSource(new StringReader(xml)));

int plain = doc.getElementsByTagName("recipe").getLength();       // 0
int prefixed = doc.getElementsByTagName("r:recipe").getLength();  // 1
A namespace-aware factory matches by namespace URI and local name (the name without the prefix), so the prefix in the file no longer matters.
String xml = """
    <r:recipe xmlns:r="https://example.com/recipes" id="1"/>""";
DocumentBuilderFactory factory = DocumentBuilderFactory.newInstance();
factory.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);
factory.setNamespaceAware(true);
Document doc = factory.newDocumentBuilder().parse(new InputSource(new StringReader(xml)));

NodeList recipes = doc.getElementsByTagNameNS("https://example.com/recipes", "recipe");
int nsCount = recipes.getLength();                           // 1
String local = ((Element) recipes.item(0)).getLocalName();   // recipe
String tag = ((Element) recipes.item(0)).getTagName();       // r:recipe
The wildcard “*” as the namespace argument matches an element name in any namespace.
6.2. Is DocumentBuilder Thread-Safe?
No, not by contract. The JavaDoc of DocumentBuilder and DocumentBuilderFactory makes no thread-safety promise, so we treat both classes as unsafe for use by several threads at the same time. We configure the factory with the security features and create one DocumentBuilder per thread or per request, as newBuilder() in section 1.1 does. One builder may parse many documents one after another in the same thread, and reset() returns it to the state it had when the factory created it. A parsed Document is not thread-safe either when one thread changes the tree.
6.3. How Do We Validate XML Against an XSD Before Reading It?
We set the schema on the factory. An XSD (XML Schema Definition) file describes which elements and attributes the XML may contain, and factory.setSchema(schema) makes the DOM parser check the XML against the XSD while parsing. A javax.xml.validation.Validator checks a document that is already parsed. Both ways, with their error messages, are part of XSD schema validation in Java.
6.4. Do We Need a Library Such as Xerces or JDOM?
No. The JDK contains its own copy of Xerces in the java.xml module, and every class in this post comes from the JDK. Libraries such as JDOM2 offer an API that feels more like normal Java, with lists instead of NodeList and no casts, but they add an extra dependency.
7. Conclusion
Reading XML with the Java DOM parser takes three steps. We create a DocumentBuilder from a DocumentBuilderFactory, call parse() on a File, an InputStream or an InputSource, and read the tree with getElementsByTagName(), getAttribute() and getTextContent(). In loops over getChildNodes(), we check getNodeType() before casting and strip text values.
For untrusted input, we disallow DOCTYPE declarations. When we only need a few values, XPath is shorter, and for files larger than a few megabytes, SAX or StAX reads the data in a tiny part of the memory.
8. References
- DocumentBuilderFactory JavaDoc (Java 25)
- DocumentBuilder JavaDoc (Java 25)
- Node JavaDoc (Java 25)
- java.xml module and JAXP limits (Java 25)
- JAXP Security Guide (Java 25)
- W3C DOM Level 3 Core
Happy Learning !!

I have a task to transform xml and xsl file to html. The problem is, the xml and xsl files are uploaded through file upload so i dont have the file object. I have xml and xsl code file contents.
Please help me as to how to transform the contents only.
it will read white spaces also
Hi
I tried to run your code,
while executing and examining node.hasChildNode() always return true and getChildNode().getLength() always return integer values even if there are no child node present.
for ex . Node Lastname in your xml doesnt contain any child node but hasChildNode returns true for the same, it should return false in order for me to do some coding for my project need.
im using the sample xml used here.
Thanks,
Rohini Rangaswany
My requirement is the Write a new corn job to export all users in an XML format. Use the
DOM java class to export to xml. This job should run at 5 pm IST in Hybris
I want to parse html file.
Tried by
but getting error.
It needs xml file only.
How I can parse html file?
hi,
i dont know how i get data if the XML is little more complex and every employee look like that:
David
Feezor
USA
NY
NY
how can i get to the data in city ?
thanks!
I have a XML file. I want to get a XML from the same XML as a subset. How to do it in java please give an code example.
Its urgent please provide your input.
Lots of thanks.
Unmarshal the XML into java objects, and then marshal desired java object into XML.
Hi Lokesh,
I need to transform XHTML span tags with certain style to another (similar) XML structure.
For example, this element should be converted:
This simple example, I could implement by renaming nodes and attributes.
But there are style attributes that I can’t match. In this case I need to ignore/remove the element node but keep its content:
Eg. I can’t map span element when their style attribute is “text-decoration: underline;” :
The element “span style=”text-decoration: underline” should be ignored/removed but the content (child nodes) should remain (text and span elements that can be mapped).
Do you know how this could be implemented? I appreciate any help.
So the expected result should be:
Thanks Benjamin!
I am stuck up with this!!! I want to fetch the value of ns1:uri based on the choices for SMS, MMS…
true
tel:+46123456758
E164
mmsChannel
MMS
00
true
tel:+46123456758
E164
SMS Dummy
SMS
00
true
tel:+464611223344
E164
faxChannel
FAX
true
tel:+46123456758
E164
CCS MWI
MWI
Could you please help me with some sort of hint to read this value. TIA
Please wrap the XML inside [xml] … [/xml].
Hi Lokesh,
If there is one more tag named department inside , then how can we do it in unknown xml structure. to get bith employee as well as department details
what if the nodes have furthur node like
<launch>
        <announced>23 march 2011</announced>
        <status>available</status>
</launch>
now when i give launch in getElementByTagName then it prints the data as 23 march 2011available without any space among them … how to put the space between these node’s contents…
Following is the code used and below element contents are changed which is not desired by replacing the escape character,
Below is the code used,
Document xmlDocument = DocumentBuilderFactory.newInstance()
.newDocumentBuilder().parse(SourceXMLFile);
XPath xPath = XPathFactory.newInstance().newXPath();
XPathExpression exprPre = xPath
.compile(“/SPIRITConfiguration/@Version”);
NodeList list = (NodeList) exprPre.evaluate(xmlDocument,
XPathConstants.NODESET);
for (int i = 0; i < list.getLength(); i++) {
list.item(i).setTextContent(ModelVersion.getValue());
}
// write the content back into new renamed xml file
TransformerFactory transformerFactory = TransformerFactory
.newInstance();
Transformer transformer = transformerFactory.newTransformer();
DOMSource source = new DOMSource(xmlDocument);
StreamResult result = new StreamResult(new File(DestxmlFile));
transformer.transform(source, result);
Kindly help me on this. Thank you in advance.
Hello Sir,
I got a requirement that I have to map my xml to java object without parsing it, but the problem is like that in xml tag names would be same, for example,
Sharique
24
India</name
and class would be like this
public class Employee{
private String empName;
private int age;
private String country;
//getters and setters
}
Please help
You forgot to put your code in [xml] … [/xml] tags.
I don’t know why xml tags are not appearing though I’m providind it in comments
You are not using [xml] your XML here [/xml] tags. Anyway, send me your problem in howtodoinjava@gmail.com. I will reply later in evening.
Hi Lokesh,
I’m struggling with a problem like I have xml which have repeated child node with same name so when I’m trying to fetch all child node values DOM parser returns only first child value.My xml looks like …
Lokesh
Gupta
India
A
B
C
P
K
S
How can I parse it using dom parser to get all repeated values?Please respond.
Please XML java java sourcecodes inside [java] … [/java] OR [xml] … [/xml] tags.
Thanks for the tutorial, it really helped me, but i was wondering…Is there a way to “format” the output?
I mean, you get the info like this :
Node Name = employee; Value =
Lokesh
Gupta
India
Attr name : id; Value = 111
Node Name = firstName; Value = Lokesh
Node Name = lastName; Value = Gupta
Node Name = location; Value = India
But is there a way to just print :
Name : Lokesh
Last Name : Gupta
Location : India
###########
// And so on for every other Employee
Thank you!
I seriously doubt that there is any API support. Reason is simple that you are expected to store the values in some java objects and not directly print them anywhere.
Here after populating the java objects, you can override toString() method to print the content the way you like.
thnx sir
Thanks Lokesh. It cleared my doubt.
what is difference between xml parsing and JAXB. I think both serve the same purpose.
In broader sense, yes, they are somehow same. But if you look closely, they are different things. Parsers are used to generate/populate java objects or simply analyzing the XML data. Java POJOs object’s are optional here.
In JAXB, java POJOs are mandatory. JAXB acts as a bridge between XML and java POJOs. What’s parsers do is just a small portion of JAXB. JAXB is much more than that.