
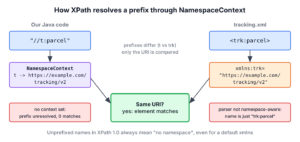
A NamespaceContext tells the Java XPath API which namespace URI each prefix in an expression stands for, so an expression such as //trk:parcel can match elements that the XML document puts in a namespace. We set it with XPath.setNamespaceContext(), and the document must be parsed with namespace awareness turned on.
We need namespace resolution for almost every XML format that comes from another system, such as SOAP responses, Atom and RSS feeds, sitemaps, Maven POM files and Office documents. Without it, XPath expressions that look correct return nothing.
The following example reads parcel statuses from a SOAP tracking response, tracking.xml.
<?xml version="1.0" encoding="UTF-8"?>
<soap:Envelope xmlns:soap="http://schemas.xmlsoap.org/soap/envelope/">
  <soap:Body>
    <trk:TrackResponse xmlns:trk="https://example.com/tracking/v2">
      <trk:parcel id="1" trk:carrier="DHL">
        <trk:status>IN_TRANSIT</trk:status>
      </trk:parcel>
      <trk:parcel id="2" trk:carrier="UPS">
        <trk:status>DELIVERED</trk:status>
      </trk:parcel>
    </trk:TrackResponse>
  </soap:Body>
</soap:Envelope>
DocumentBuilderFactory factory = DocumentBuilderFactory.newInstance();
factory.setNamespaceAware(true);
factory.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);
Document doc = factory.newDocumentBuilder().parse(new File("tracking.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();
xpath.setNamespaceContext(new MapNamespaceContext(Map.of("t", "https://example.com/tracking/v2")));
String status = xpath.evaluate("//t:parcel[@id='2']/t:status", doc); // "DELIVERED"The expression uses the prefix t, whereas the document uses trk. Only the URI has to match. The class MapNamespaceContext is our own ten-line implementation from section 2, because the JDK ships no public one. After that, we handle a default namespace, namespaced attributes, prefixes read from the document and the local-name() shortcut.
1. Why XPath Finds Nothing in Namespaced XML
An element name in XML with namespaces has two parts, the namespace URI and the local name. The prefix is only a short alias for the URI inside one document. XPath works the same way, so //parcel without a prefix means “a parcel element in no namespace”, as the XPath 1.0 node test rules define, and it never matches trk:parcel.
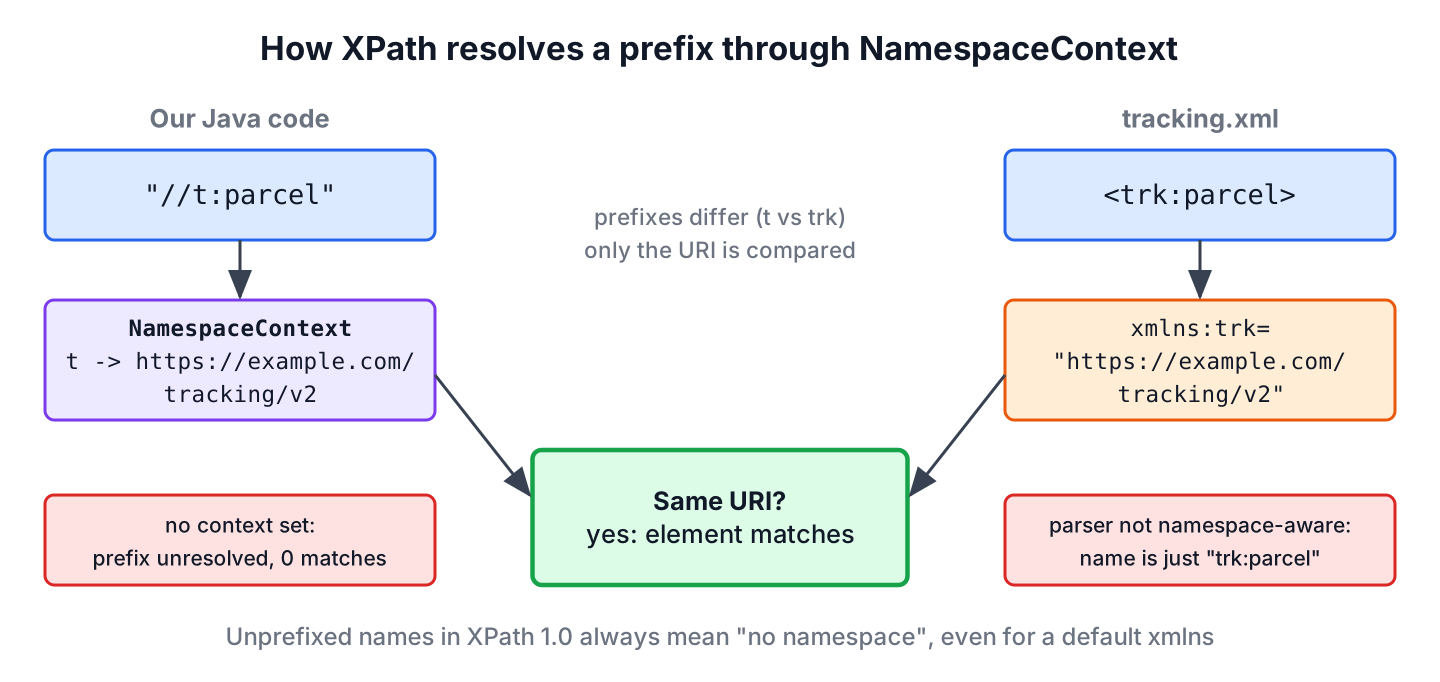
Two settings have to be right before a namespaced query works. The DocumentBuilderFactory is not namespace-aware by default, and the XPath object needs a context for every prefix in the expression. The helper parseNamespaceAware() fixes the first part, and it also turns off DOCTYPE declarations so that the parser never loads external entities.
static Document parseNamespaceAware(Path file) throws Exception {
    DocumentBuilderFactory factory = DocumentBuilderFactory.newInstance();
    factory.setNamespaceAware(true);
    factory.setFeature("http://apache.org/xml/features/disallow-doctype-decl", true);
    return factory.newDocumentBuilder().parse(file.toFile());
}
Document doc = parseNamespaceAware(Path.of("tracking.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();
Double noPrefix = xpath.evaluateExpression("count(//parcel)", doc, Double.class); // 0.0
Double unbound = xpath.evaluateExpression("count(//trk:parcel)", doc, Double.class); // 0.0Both expressions count zero parcels, and neither throws an exception. The first one looks for parcel in no namespace. In the second one, the XPath object has no context at all, so the JDK cannot resolve trk and matches nothing. The prefixes declared in the document do not count, since the API never looks into the document to resolve them.
We always parse namespaced XML with setNamespaceAware(true) and give the XPath object a NamespaceContext for every prefix we use. Without namespace awareness, the DOM stores trk:parcel as a plain name with a colon, and even a correct context matches nothing.
2. Implementing an XPath NamespaceContext With a Map
The NamespaceContext interface has three methods. XPath calls getNamespaceURI() for each prefix, and the other two do the reverse lookup. A record that wraps a Map covers all three and follows the interface contract, which asks for an IllegalArgumentException on a null argument and an empty string for an unbound prefix.
record MapNamespaceContext(Map<String, String> uris) implements NamespaceContext {

    MapNamespaceContext {
        uris = Map.copyOf(uris);
    }

    @Override
    public String getNamespaceURI(String prefix) {
        if (prefix == null) {
            throw new IllegalArgumentException("prefix is null");
        }
        return switch (prefix) {
            case XMLConstants.XML_NS_PREFIX -> XMLConstants.XML_NS_URI;
            case XMLConstants.XMLNS_ATTRIBUTE -> XMLConstants.XMLNS_ATTRIBUTE_NS_URI;
            default -> uris.getOrDefault(prefix, XMLConstants.NULL_NS_URI);
        };
    }

    @Override
    public String getPrefix(String namespaceURI) {
        Iterator<String> prefixes = getPrefixes(namespaceURI);
        return prefixes.hasNext() ? prefixes.next() : null;
    }

    @Override
    public Iterator<String> getPrefixes(String namespaceURI) {
        if (namespaceURI == null) {
            throw new IllegalArgumentException("namespaceURI is null");
        }
        return uris.entrySet().stream()
                .filter(entry -> entry.getValue().equals(namespaceURI))
                .map(Map.Entry::getKey)
                .iterator();
    }
}
The reserved prefixes xml and xmlns always map to their fixed URIs, as the interface requires. The method getPrefixes() returns an empty iterator for an unknown URI rather than null, which some older examples return and which breaks any caller that loops over the result.
Document doc = parseNamespaceAware(Path.of("tracking.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();
xpath.setNamespaceContext(new MapNamespaceContext(Map.of(
        "s", "http://schemas.xmlsoap.org/soap/envelope/",
        "t", "https://example.com/tracking/v2")));

Double parcels = xpath.evaluateExpression("count(/s:Envelope/s:Body/t:TrackResponse/t:parcel)", doc, Double.class);   // 2.0
String first = xpath.evaluate("//t:parcel[1]/t:status", doc);       // "IN_TRANSIT"
String unknown = xpath.getNamespaceContext().getNamespaceURI("x");  // ""
Double typo = xpath.evaluateExpression("count(//tr:parcel)", doc, Double.class);   // XPathExpressionException
Once a context is set, a prefix it does not know, such as the typo tr, makes the evaluation throw an XPathExpressionException with the message Prefix must resolve to a namespace. That error is useful, because it turns a silent empty result into a visible bug.
Spring applications already have SimpleNamespaceContext in spring-core, with bindNamespaceUri(prefix, uri) and setBindings(map). Outside Spring, the MapNamespaceContext record is all we need, and it adds no dependency.
3. Querying a Default Namespace
A default namespace, declared with xmlns=”…” and no prefix, puts every unprefixed element in that namespace. XPath 1.0 has no notion of a default namespace for element names, so we still bind the URI to a prefix of our choice and use it in the expression. A sitemap is a typical case.
Say an SEO tool checks a website’s sitemap.xml and lists every URL with its priority. The file declares the sitemap namespace as the default namespace, so //url/loc finds nothing.
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url><loc>https://example.com/</loc><priority>1.0</priority></url>
  <url><loc>https://example.com/blog</loc><priority>0.8</priority></url>
</urlset>
Document doc = parseNamespaceAware(Path.of("sitemap.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();
xpath.setNamespaceContext(new MapNamespaceContext(Map.of("sm", "http://www.sitemaps.org/schemas/sitemap/0.9")));
Double withoutPrefix = xpath.evaluateExpression("count(//url/loc)", doc, Double.class); // 0.0
List<String> urls = new ArrayList<>();
for (Node loc : xpath.evaluateExpression("//sm:url/sm:loc", doc, XPathNodes.class)) {
urls.add(loc.getTextContent());
}
List<String> found = urls; // [https://example.com/, https://example.com/blog]Binding the empty prefix in the context does not help. An unprefixed name in an XPath 1.0 expression always means no namespace, whatever getNamespaceURI(“”) returns, so the made-up prefix is the only way.
4. Namespaced and Plain Attributes
Attributes follow a rule that surprises many developers. An attribute without a prefix is in no namespace, even when its element is in a namespace. Only a prefixed attribute, such as trk:carrier, belongs to the namespace of its prefix.
Document doc = parseNamespaceAware(Path.of("tracking.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();
xpath.setNamespaceContext(new MapNamespaceContext(Map.of("t", "https://example.com/tracking/v2")));

String carrier = xpath.evaluate("//t:parcel[@id='1']/@t:carrier", doc);    // "DHL"
String noNs = xpath.evaluate("//t:parcel[@id='1']/@carrier", doc);         // ""
String wrongId = xpath.evaluate("//t:parcel/@t:id", doc);                  // ""
So we write @id without a prefix and @t:carrier with one, the same way the document does, only with our own prefix. The DOM methods follow the same rule, so getAttribute(“id”) works and the namespaced attribute needs getAttributeNS(uri, “carrier”).
5. Resolving Prefixes From the Document
Instead of a fixed map, a context can ask the document with Node.lookupNamespaceURI(). The appeal is that we never repeat URIs in Java code. The catch is the scope of the lookup, because Document.lookupNamespaceURI() searches only from the root element, and a prefix declared deeper in the tree is invisible there.
Document doc = parseNamespaceAware(Path.of("tracking.xml"));
Element response = (Element) doc.getElementsByTagNameNS("https://example.com/tracking/v2", "TrackResponse").item(0);

String soapFromRoot = doc.lookupNamespaceURI("soap");          // "http://schemas.xmlsoap.org/soap/envelope/"
String trkFromRoot = doc.lookupNamespaceURI("trk");            // null
String trkFromResponse = response.lookupNamespaceURI("trk");   // "https://example.com/tracking/v2"
SOAP responses declare the service namespace on the body element, as our file does, so a context built on the document resolves soap but not trk. Documents from the same service can also switch prefixes between releases, such as ns2 today and ns3 tomorrow, and expressions tied to document prefixes break. The URI is the stable part of the contract, so the map-based context is the safer default.
6. Matching by local-name() Without a Context
XPath can also ignore namespaces altogether with the functions local-name() and namespace-uri(). The expression //*[local-name()=’parcel’] matches every element named parcel in any namespace, and no NamespaceContext is needed.
Document doc = parseNamespaceAware(Path.of("tracking.xml"));
XPath xpath = XPathFactory.newInstance().newXPath();

Double anyNs = xpath.evaluateExpression("count(//*[local-name()='parcel'])", doc, Double.class);   // 2.0
String status = xpath.evaluate("//*[local-name()='parcel'][@id='2']/*[local-name()='status']", doc);   // "DELIVERED"
The shortcut is fine for a quick script, but it has two costs. The expressions get long and hard to read, and they also match elements from a different vocabulary that use the same local name, such as a status element that another service adds to the same response in its own namespace.
| Approach | Needs a context | Survives prefix changes | Handles nested declarations | Best for |
|---|---|---|---|---|
| Map-based NamespaceContext | Yes | Yes | Yes | Production code |
| Document-based context | Yes | No | No, root only | Simple files with all declarations on the root |
| local-name() | No | Yes | Yes | Quick scripts and debugging |
| Parsing without namespace awareness | No | No | No | Never, prefixes become part of the names |
7. XPath Namespace FAQs
Namespace bugs rarely raise an error. They return an empty result, so each answer starts from that symptom.
7.1. Do the Prefixes in My XPath Have to Match the XML File?
No. XPath matches namespace URIs, so t:parcel matches trk:parcel when both prefixes resolve to the same URI. Picking our own short prefixes keeps expressions stable when the producer changes its prefixes.
7.2. Does the JDK Include a NamespaceContext Implementation?
No public one. The JDK uses internal classes for its own parsers, but the javax.xml.namespace package only defines the interface. We write a small class such as the record in section 2, or use SimpleNamespaceContext from Spring.
7.3. Can I Change the NamespaceContext After Compiling an Expression?
We can, but the change has no effect on expressions that are already compiled, because compile() resolves the prefixes at that moment. We set the context first and compile afterwards, which is the same rule the XPath variable resolver follows.
7.4. How Do Namespaces Work in JDOM2 XPath?
JDOM2 takes Namespace objects instead of a context, passed to XPathFactory.compile(), for example Namespace.getNamespace(“t”, uri). The article on reading XML with JDOM2 shows it with a namespaced file.
8. Conclusion
XPath namespace resolution in Java needs two things, a namespace-aware parser and a NamespaceContext that maps the prefixes of our expressions to namespace URIs. The prefixes are our choice, the URIs must match the document, and a default namespace still needs a prefix in the expression.
A map-based context is short to write, follows the interface contract and keeps working when the producer moves a declaration or renames a prefix. Unprefixed attributes stay outside every namespace, and local-name() remains a debugging shortcut rather than a production pattern. For the rest of the XPath syntax, see the Java XPath tutorial, and for parsing basics the DOM parser guide.
9. References
- NamespaceContext Javadoc (Java 25)
- XPath Javadoc (Java 25)
- XML Path Language (XPath) 1.0
- Namespaces in XML 1.0
- Sitemaps XML format
Happy Learning !!

One weakness with your approach comes from the assumption that the prefix has any real meaning. In fact, the namespace prefix is arbitrary. A document could be written with the prefix ns3 instead of ns2, which would still be valid according to a schema, but your code would fail because you’ve hard-coded the prefix. Is there really a way to get around the fact that you have to know the URI portion of the namespace to reliably parse these documents?
Hi, in my case my api returns the response where name spaces are dynamic i.e the number of name spaces present in the xml is not fixed. In that case what should be the xpath expression?
Is there any way to ignore the name space in while providing it in the xpath
Thank you for the solution, worked like a charm.
Btw is there a way i can ignore the namespace while providing the xpath?
I don’t understand what part of the flow you use the namspece.
Thank You so much – Great example, neat and crisp, works like a charm
Good example, excellent explained! This example helped me a lot! Thanks!