
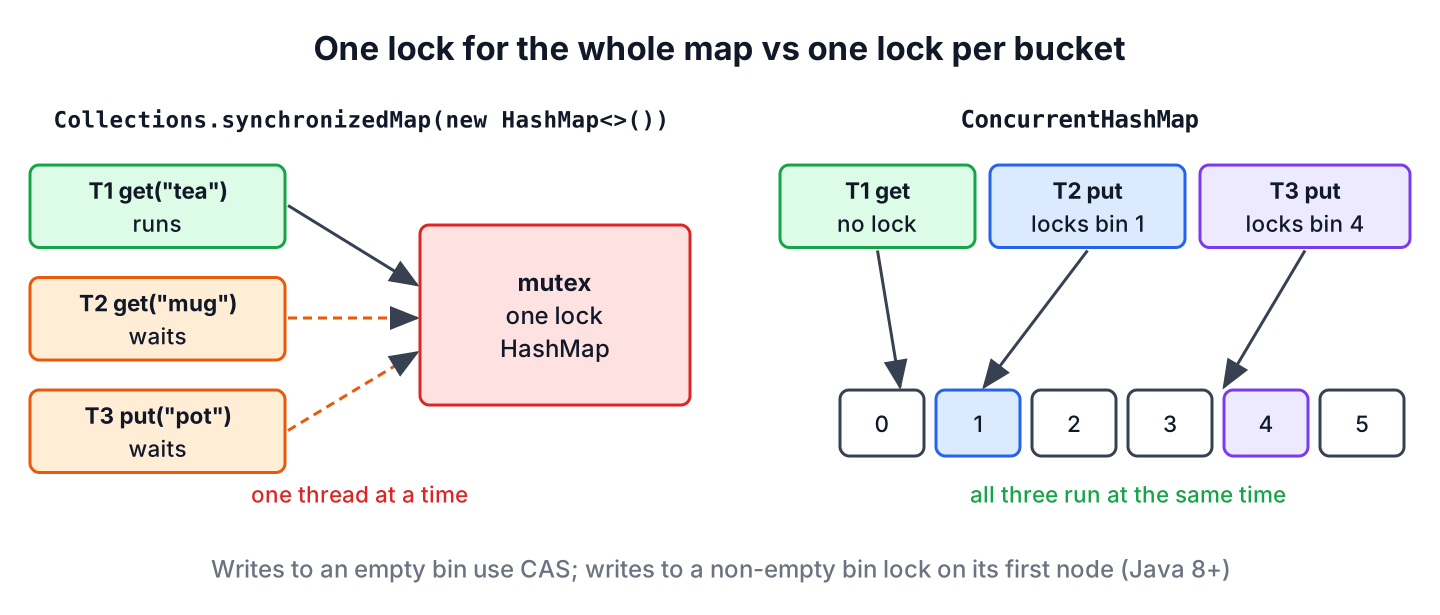
Collections.synchronizedMap() makes a HashMap thread-safe by wrapping it so that every method call takes one lock on the whole map, whereas ConcurrentHashMap lets reads run without a lock and locks only one bucket for each write. Both give correct results for single calls such as put() and get(), but ConcurrentHashMap lets many threads work on the map at the same time. The choice of ConcurrentHashMap vs synchronizedMap therefore depends on how many threads use the map and what else we need from it.
We need one of them whenever several threads share a map, such as a cache in a web app or counters updated by request threads. A plain HashMap is not synchronized, so concurrent writes can lose updates or corrupt its internal state. The following example creates both maps and updates a counter in each one.
Map<String, Integer> wrapped = Collections.synchronizedMap(new HashMap<>());
ConcurrentHashMap<String, Integer> concurrent = new ConcurrentHashMap<>();
Integer w1 = wrapped.merge("tea", 1, Integer::sum);          // 1, one lock for the whole map
Integer c1 = concurrent.merge("tea", 1, Integer::sum);       // 1, locks only the bucket of "tea"
Integer w2 = wrapped.put("note", null);                      // null, HashMap accepts null values
Integer c2 = concurrent.put("note", null);                   // NullPointerException
Notice the last line, because ConcurrentHashMap rejects null keys and values while the wrapper accepts whatever its backing map accepts. We look at how each map locks, why compound actions need special methods on both, how to iterate each one safely, and when the wrapper is still the right choice.
1. Why a HashMap Needs Protection Between Threads
A HashMap read-modify-write such as merge() reads the old value, computes the new one and writes it back. When two threads do that on the same key at the same time, both read the same old value and one increment is lost. A resize running in one thread while another thread writes can also lose whole entries.
Map<String, Integer> unsafe = new HashMap<>();
try (ExecutorService pool = Executors.newVirtualThreadPerTaskExecutor()) {
    for (int i = 0; i < 1_000; i++) {
        pool.submit(() -> unsafe.merge("views", 1, Integer::sum));
    }
}
Integer views = unsafe.get("views");                         // often below 1000, varies per run
The result changes from run to run, and that makes the bug hard to find in tests. The fix is to give the threads a map that controls access for them, and Java offers two of them in the JDK.
- The wrapper from Collections.synchronizedMap(), which works with any Map implementation.
- The class ConcurrentHashMap from java.util.concurrent, which is a separate hash table built for concurrent access.
2. How Collections.synchronizedMap() Locks the Map
The method Collections.synchronizedMap(map) returns a wrapper object of the private class Collections.SynchronizedMap. Every method of the wrapper runs inside a synchronized block on one lock object, which is the wrapper itself, and delegates the call to the backing map.
// does not compile: excerpt from java.util.Collections.SynchronizedMap in JDK 25
public V get(Object key) {
    synchronized (mutex) {return m.get(key);}
}
public V merge(K key, V value, BiFunction<? super V, ? super V, ? extends V> remappingFunction) {
    synchronized (mutex) {return m.merge(key, value, remappingFunction);}
}
Because merge(), compute(), putIfAbsent() and forEach() are also wrapped, each single call is atomic. The price is that only one thread can use the map at any moment, even when two threads only read different keys.
We must send every access through the wrapper. A thread that keeps a reference to the backing HashMap and writes to it bypasses the lock, so we create the backing map inside the call and never store it.
Map<String, Integer> stock = Collections.synchronizedMap(new HashMap<>());
Integer before = stock.put("tea", 5);                        // null
Integer units = stock.get("tea");                            // 5
Integer missing = stock.getOrDefault("mug", 0);              // 0
3. How ConcurrentHashMap Locks Since Java 8
Since Java 8, ConcurrentHashMap has no segments and no map-wide lock. Java 7 split the map into 16 segments with one lock each, and many articles still describe that design. The current class locks per bucket, and readers do not lock at all.
- A read such as get() never locks. It reads the bucket through volatile memory access, so it sees the latest completed write.
- A write to an empty bucket inserts the first node with a single compare-and-swap (CAS) instruction, which also needs no lock.
- A write to a non-empty bucket synchronizes on the first node of that bucket only, so writes to other buckets go on in parallel.
- When the table resizes, several writer threads help move the buckets, while readers keep reading the old or the new table.
The atomic methods compute(), computeIfAbsent() and merge() run their function while holding the bucket lock, so the function must be short and must not change other keys of the same map. The ConcurrentMap guide covers these methods and the bulk operations in detail.
ConcurrentHashMap<String, Integer> stock = new ConcurrentHashMap<>();
Integer added = stock.putIfAbsent("tea", 5);                 // null
Integer kept = stock.putIfAbsent("tea", 9);                  // 5, the existing value stays
Integer reserved = stock.compute("tea", (sku, n) -> n - 1);  // 4
long count = stock.mappingCount();                           // 1
4. ConcurrentHashMap vs synchronizedMap Side by Side
The two maps give the same answer for single calls, so the differences show up in throughput, iteration and null handling.
| Feature | Collections.synchronizedMap(new HashMap<>()) | ConcurrentHashMap |
|---|---|---|
| Locking | One lock for every call, reads included | Lock-free reads, one bucket lock per write |
| Concurrent readers | One at a time | Any number in parallel |
| Single calls (put, merge, compute) | Atomic | Atomic |
| Iteration | Must be inside synchronized (map); fail-fast, can throw ConcurrentModificationException | No lock needed; weakly consistent, never throws ConcurrentModificationException |
| null keys and values | As the backing map (HashMap allows them) | Rejected with NullPointerException |
| Backing map type | Any Map, e.g. LinkedHashMap or TreeMap | Its own hash table only |
| size() during writes | Exact at the moment of the call | An estimate while other threads write |
| Locking a block of several calls | Possible with synchronized (map) | Not possible; the map does not use its own monitor |
The last row matters when we need several calls to run as one unit, such as moving stock from one key to another. With the wrapper, we hold the map’s lock across the calls. With ConcurrentHashMap, a synchronized (map) block does not stop other threads, because the map never uses that lock, so we redesign the update as one atomic call or use a separate lock.
5. Check-and-Put Races in Both Maps
A synchronized or concurrent map makes each call atomic, not a sequence of calls. The pattern “if the key is missing, put it” uses two calls, and another thread can insert the key between them.
Map<String, Integer> stock = Collections.synchronizedMap(new HashMap<>());
if (!stock.containsKey("tea")) {     // thread A checks
    stock.put("tea", 5);             // thread B may have put "tea" in between
}
The fix is the same for both maps. We replace the two calls with one atomic method, so the check and the write happen under the same lock.
Map<String, Integer> wrapped = Collections.synchronizedMap(new HashMap<>());
ConcurrentHashMap<String, Integer> concurrent = new ConcurrentHashMap<>();
Integer w = wrapped.putIfAbsent("tea", 5);                   // null, atomic on the wrapper too
Integer c = concurrent.putIfAbsent("tea", 5);                // null
Integer sold = concurrent.merge("tea", -1, Integer::sum);    // 4
When an update spans several keys, the wrapper lets us hold its lock for the whole block. ConcurrentHashMap has no such option, so we keep related values in one entry, for example a record as the value, and update that entry with compute().
Map<String, Integer> shelf = Collections.synchronizedMap(new HashMap<>(Map.of("tea", 5, "teaGift", 0)));
synchronized (shelf) {
    shelf.merge("tea", -1, Integer::sum);
    shelf.merge("teaGift", 1, Integer::sum);
}
Integer tea = shelf.get("tea");                              // 4
Integer gifts = shelf.get("teaGift");                        // 1
6. Iterating Each Map Safely
The two maps follow opposite rules for iteration. For the wrapper, we must hold its lock while we walk any of its views with an Iterator, a for-each loop or a stream. Without the lock, another thread can change the map mid-loop, and the fail-fast HashMap iterator throws ConcurrentModificationException or returns inconsistent data.
Map<String, Integer> stock = Collections.synchronizedMap(new HashMap<>(Map.of("tea", 5, "mug", 2)));
int total = 0;
synchronized (stock) {               // lock the wrapper, not the keySet() or values() view
    for (int units : stock.values()) {
        total += units;
    }
}
int sum = total;                                             // 7
Single-call methods on the views, such as forEach() and removeIf(), take the lock themselves, so they need no extra block.
Map<String, Integer> stock = Collections.synchronizedMap(new HashMap<>(Map.of("tea", 5, "mug", 0)));
boolean removed = stock.values().removeIf(units -> units == 0);   // true
int left = stock.size();                                          // 1
Iterators of a ConcurrentHashMap are weakly consistent. It never throws ConcurrentModificationException, it shows each entry at most once, and it may or may not show changes made after the iterator was created. We iterate without a lock and can remove entries in the loop. The two-argument remove(key, value) removes the entry only while it still holds that value, so a concurrent restock is never lost.
ConcurrentHashMap<String, Integer> stock = new ConcurrentHashMap<>(Map.of("tea", 5, "mug", 0, "pot", 0));
for (String sku : stock.keySet()) {
    stock.remove(sku, 0);            // removes only if the value is still 0
}
int left = stock.size();                                     // 1
Wrapping a ConcurrentHashMap loop in synchronized (map), as some older tutorials show, adds nothing, because writers never take that lock.
7. Reserving Stock in an Online Shop
An online shop keeps the available units of each product in memory, and hundreds of checkout threads reserve units at the same time. Most requests read stock levels for product pages, and only a few write. With the wrapper, every page view waits for the same lock as the checkouts, so the lock becomes the bottleneck under load.
A ConcurrentHashMap lets the page views read without locking, and each reservation locks only the bucket of one product. The reservation is a single compute() call, so two buyers can never take the last unit together.
static boolean reserve(ConcurrentHashMap<String, Integer> stock, String sku) {
    boolean[] ok = {false};
    stock.computeIfPresent(sku, (key, units) -> {
        if (units == 0) {
            return 0;
        }
        ok[0] = true;
        return units - 1;
    });
    return ok[0];
}
ConcurrentHashMap<String, Integer> stock = new ConcurrentHashMap<>(Map.of("lamp", 1));
boolean first = reserve(stock, "lamp"); // true
boolean second = reserve(stock, "lamp"); // false, sold out
boolean unknown = reserve(stock, "desk"); // false, no such product
Integer lamps = stock.get("lamp"); // 08. Choosing Between the Two
For a new shared map, we use ConcurrentHashMap, because it scales with the number of threads and its iteration needs no lock. The wrapper still has a place in a few cases.
- We need null keys or values, which ConcurrentHashMap rejects.
- We need the order of a LinkedHashMap, for example an access-ordered LRU cache, which has no concurrent version in the JDK.
- We need to lock several calls as one unit and the map is small, so the single lock costs little.
- We have an existing map object that other code already holds, and we want thread-safe access without copying it.
For sorted keys, ConcurrentSkipListMap is the concurrent counterpart of TreeMap, and Collections.synchronizedSortedMap() or synchronizedNavigableMap() wrap a TreeMap with one lock. The legacy Hashtable locks every method like the wrapper and rejects null like ConcurrentHashMap, so it has no advantage over either map in new code.
9. Synchronized HashMap FAQs
The two maps are most often confused over speed, null handling and locking during iteration.
9.1. Which is faster, ConcurrentHashMap or Collections.synchronizedMap()?
ConcurrentHashMap is faster as soon as several threads use the map, especially for reads, because readers never wait for a lock and writers lock only one bucket. With a single thread, both maps cost about the same, so the difference depends on contention. We measure our own workload with JMH before quoting numbers.
9.2. Why does ConcurrentHashMap not allow null keys or values?
Because get() returning null must mean “no mapping”. In a concurrent map, another thread can change the map between get() and containsKey(), so we could not tell a missing key from a null value. Rejecting null removes that ambiguity, so we store a marker value such as Optional.empty() instead.
9.3. Do we need to synchronize when iterating a synchronizedMap?
Yes. We put the whole loop in synchronized (map) on the wrapper object, not on the view returned by keySet(), values() or entrySet(). Single calls such as forEach() and removeIf() lock by themselves.
9.4. Is ConcurrentHashMap still divided into segments?
No. Segments were the Java 7 design. Since Java 8, the map uses CAS for empty buckets and synchronizes on the first node of a bucket for other writes. The concurrencyLevel constructor argument is still accepted, but it only serves as a size hint.
9.5. How do we make an existing HashMap thread-safe?
We either wrap it or copy it. The wrapper Collections.synchronizedMap(existing) keeps the same entries, but every other reference to existing must stop writing to it. The copy constructor gives an independent concurrent map.
Map<String, Integer> existing = new HashMap<>(Map.of("tea", 5));
Map<String, Integer> wrapped = Collections.synchronizedMap(existing);   // same entries, one lock
ConcurrentHashMap<String, Integer> copy = new ConcurrentHashMap<>(existing);
Integer tea = copy.get("tea");                                          // 5
10. Conclusion
Both thread-safe maps make single calls atomic. Collections.synchronizedMap() does it with one lock for the whole map, so it works with any backing map, allows null if the backing map does, and lets us lock a group of calls, but all threads wait in line and iteration needs a manual synchronized block.
ConcurrentHashMap reads without locks and locks one bucket per write, and its weakly consistent iterators need no lock at all. It is the default choice for shared maps in new code, as long as we replace check-and-put code with putIfAbsent(), compute() or merge() and keep null out of it.
11. References
- ConcurrentHashMap Javadoc (Java 25)
- Collections.synchronizedMap() Javadoc (Java 25)
- Weakly consistent iterators (java.util.concurrent package summary)
Happy Learning !!

Does the concurrentHashMap , end with different end state , if multiple threads try to put values in it while iterating ?
In such a case, its behavior is not predictable.
Oh okay thanks, so just to summarize :
1) using the synchronized block on iterator and synchronizedMap
a) multiple threads cannot access the code.
b) single thread attempts to add values to the map while iterating will result in CocurrentModificationException error.
2) without synchronized block and synchronizedMap
a) multiple threads can access the code (as iterator doesn’t follow sychronisedMap rules and need explicit synchronized block) and won’t be able to modify the state, as synchronisedMap locks the object.
b) single thread attempts to add values to map while iterating will result in CocurrentModificationException error.
3) with synchronized block on iterator and ConcurrentHashMap
a) multiple threads cannot access the code.
b) single thread attempts to add values to map while iterating will *not* result in CocurrentModificationException error.
4) without synchronized block on iterator and ConcurrentHashMap
a) multiple threads can access the code and the state cannot be predicted.
b) single thread attempts to add values to map while iterating will *not* result in CocurrentModificationException error.
Correct me if there are any changes in the above 8 use cases.