
An IdentityHashMap compares its keys with == instead of equals(), so two keys are the same only when they are the same object in memory. It also uses System.identityHashCode() instead of the key’s own hashCode().
We use an IdentityHashMap when we track objects themselves rather than their values, for example to mark visited nodes while copying an object graph, or to attach data to objects whose equals() we cannot trust.
The following example puts two equal but separate String objects into an IdentityHashMap and copies the result into a HashMap.
String first = new String("lokesh");
String second = new String("lokesh");

Map<String, Integer> byIdentity = new IdentityHashMap<>();
byIdentity.put(first, 1);
byIdentity.put(second, 2);

int size = byIdentity.size();                     // 2, two different objects
Integer one = byIdentity.get(first);              // 1
Integer literal = byIdentity.get("lokesh");       // null, the literal is a third object
int merged = new HashMap<>(byIdentity).size();    // 1, equals() sees one key
Notice that get(“lokesh”) returns null although the map holds two keys with that text. We cover how the class compares keys, how to create and use it, how it differs from HashMap with mutable keys, the traps with literals and boxed numbers, and the cases where it is the right tool.
1. How IdentityHashMap Compares Keys
A HashMap finds a key in two steps. It picks a bucket from key.hashCode(), and in that bucket it looks for a key where key.equals(other) returns true. An IdentityHashMap replaces both steps. It picks a slot from System.identityHashCode(key) and compares keys with key == other.
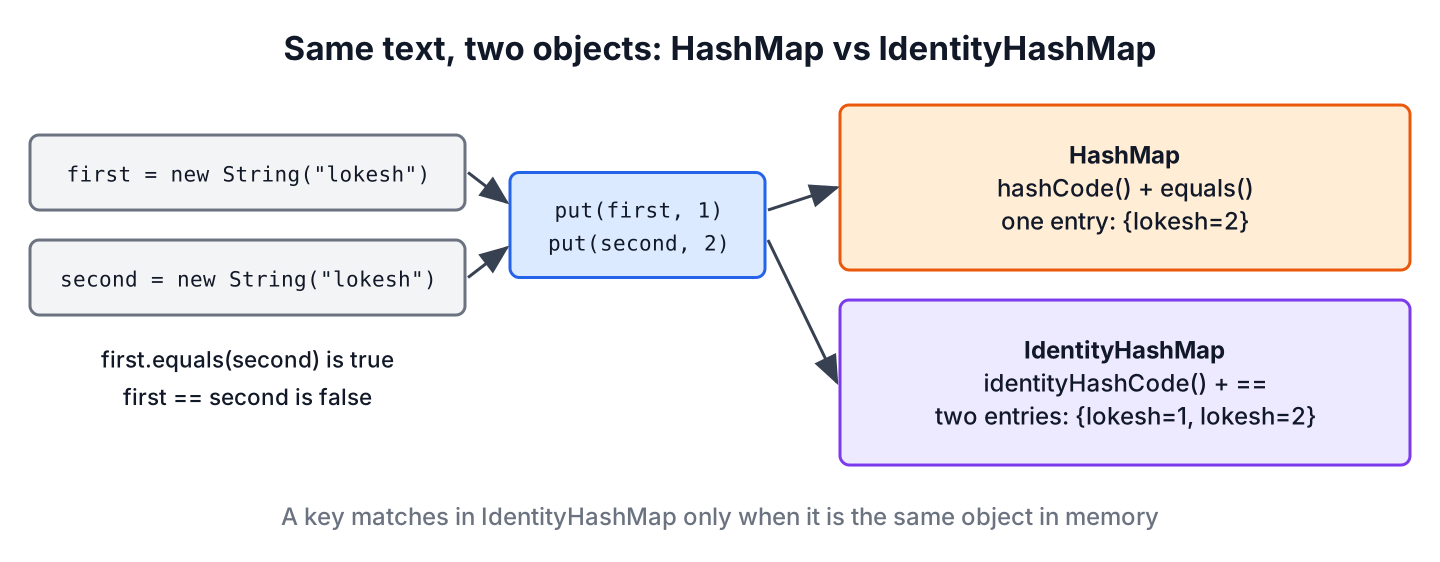
Because of this, the class breaks the general contract of the Map interface, which says that keys are compared with equals(). For that reason, IdentityHashMap is not a general-purpose Map implementation. Values are compared by identity too, so containsValue() uses ==.
The class has been in the JDK since Java 1.4. Some other facts are useful before we use it.
- It stores keys and values in one array and resolves collisions with linear probing, which means it tries the next free slot, instead of the linked buckets of HashMap.
- It allows a null key and null values.
- It has no defined iteration order, and its iterators are fail-fast.
- It is not synchronized, so shared use needs Collections.synchronizedMap() or external locking.
2. Working with IdentityHashMap
The class implements the full Map interface, so code that already uses put(), get() and merge() works without changes. Only the meaning of “same key” is different.
2.1. Creating an IdentityHashMap
The constructors take an expected maximum size instead of a capacity and a load factor. The default expected size is 21, and the map holds at least that many entries before it grows its table.
Map<String, Integer> empty = new IdentityHashMap<>();                    // expected maximum size 21
Map<String, Integer> sized = new IdentityHashMap<>(100);                 // expected maximum size 100
Map<String, Integer> copy = new IdentityHashMap<>(Map.of("apple", 5));   // copies the entries
2.2. IdentityHashMap Methods
The keys in the next snippet are String literals. The JVM keeps one object per literal in its string pool, so the same literal in two places is the same object, and the lookups succeed.
Map<String, Integer> stock = new IdentityHashMap<>();
stock.put("apple", 5);
stock.put("banana", 3);
stock.merge("apple", 2, Integer::sum);
stock.put(null, 0);                                      // null key is allowed

Integer apples = stock.get("apple");                     // 7
boolean hasBanana = stock.containsKey("banana");         // true
boolean hasSeven = stock.containsValue(7);               // true, 7 is a cached Integer
Integer removed = stock.remove("banana");                // 3
int size = stock.size();                                 // 2
The line with containsValue(7) works only because Integer.valueOf() returns cached objects for values from -128 to 127, as we explain in section 4.
3. Difference Between HashMap and IdentityHashMap
For most keys, the two classes give the same result, because a program uses the same key object for put() and get(). They behave differently when two objects are equal but not identical, and when a key changes after we put it in the map.
3.1. Reference Equality
A HashMap treats two Integer objects with the value 1000 as one key, whereas an IdentityHashMap treats them as two keys. We create the objects with Integer.valueOf(), because the constructor new Integer() is deprecated for removal.
Integer a = Integer.valueOf(1000);
Integer b = Integer.valueOf(1000);                       // a new object, outside the cache

Map<Integer, String> hashMap = new HashMap<>();
hashMap.put(a, "alex");
hashMap.put(b, "bob");
int hashSize = hashMap.size();                           // 1, b replaced the value of a

Map<Integer, String> identityMap = new IdentityHashMap<>();
identityMap.put(a, "alex");
identityMap.put(b, "bob");
int identitySize = identityMap.size();                   // 2
3.2. Mutable Keys
A HashMap loses track of a key when a field used in hashCode() changes, because get() searches a different bucket. An IdentityHashMap does not call hashCode() at all, so the identity hash code of the object stays the same and the entry stays reachable. A list is a good example of a mutable key, because its hashCode() depends on its elements.
List<String> cart = new ArrayList<>(List.of("apple"));
Map<List<String>, String> hashed = new HashMap<>();
Map<List<String>, String> identity = new IdentityHashMap<>();
hashed.put(cart, "lokesh");
identity.put(cart, "lokesh");

cart.add("banana");                                      // changes cart.hashCode()
String fromHashMap = hashed.get(cart);                   // null, wrong bucket
String fromIdentityMap = identity.get(cart);             // "lokesh"
The example does not make mutable keys a good idea in general. It shows that the identity of an object stays stable, so an IdentityHashMap fits cases where we track objects that other code keeps changing. For normal maps, good HashMap keys are immutable.
3.3. remove() and replace() Since Java 20
Until Java 19, the methods remove(key, value) and replace(key, oldValue, newValue) came from the Map default implementation, which compared the values with equals(). Java 20 fixed this with JDK-8284901, so both methods compare values by identity, like the rest of the class.
Map<String, String> settings = new IdentityHashMap<>();
String key = "theme";
settings.put(key, "dark");

boolean removed = settings.remove(key, new String("dark"));    // false on Java 20 and later
boolean replaced = settings.replace(key, "dark", "light");     // true, same literal object
Code that worked on Java 17 can return false after an upgrade if it passes a value object that is equal but not identical to the stored one.
4. Literals and Boxed Numbers as Keys
Most surprises with this class come from objects that look new but are shared, or look shared but are new. The JVM reuses some objects behind our back.
- String literals and compile-time constants come from the string pool, so “apple” in two classes is one object.
- Strings built at runtime, such as new String(“apple”), the result of substring() or text read from a file, are new objects.
- Autoboxing calls Integer.valueOf(), which returns cached objects from -128 to 127 and new objects outside that range.
- Enum constants exist once per class loader, so they behave the same in both maps.
Map<Integer, String> ids = new IdentityHashMap<>();
ids.put(100, "small");
ids.put(1000, "large");

String small = ids.get(100);                             // "small", 100 comes from the Integer cache
String large = ids.get(1000);                            // null, 1000 is boxed into a new Integer
An IdentityHashMap only works when the code that reads the map holds the same object that the code that wrote it used. Text and numbers that come from requests or files almost never meet that rule.
5. IdentityHashMap Use Cases
Two typical uses are copying an object graph so that shared references stay shared (a topology-preserving copy) and bookkeeping for proxy objects. Both need to know whether two references point to the same object, and neither can rely on the equals() of classes they do not control.
For example, a workflow tool stores tasks as records, and each task lists the tasks it depends on. A user creates a cycle, so build depends on test and test depends on build. The record’s generated hashCode() follows the list of dependencies, so a HashSet of tasks recurses forever.
record Task(String name, List<Task> dependsOn) {}static int countReachable(Task start) {
Set<Task> visited = Collections.newSetFromMap(new IdentityHashMap<>());
Deque<Task> todo = new ArrayDeque<>(List.of(start));
while (!todo.isEmpty()) {
Task task = todo.pop();
if (visited.add(task)) {
todo.addAll(task.dependsOn());
}
}
return visited.size();
}Task build = new Task("build", new ArrayList<>());
Task test = new Task("test", new ArrayList<>());
build.dependsOn().add(test);
test.dependsOn().add(build); // a cycle
Set<Task> hashed = new HashSet<>();
boolean added = hashed.add(build); // StackOverflowError, hashCode() follows the cycle
int reachable = countReachable(build); // 2The identity set from Collections.newSetFromMap() never calls hashCode() or equals() on the tasks, so the cycle does no harm, and each task is visited once. Serialization libraries and deep-copy utilities track objects they have already written in the same way.
Other good fits are caches keyed by objects that have no meaningful equals(), such as a Thread or a parser instance, and a map from original objects to their proxies. When the keys should also disappear after the program drops them, a WeakHashMap is the better choice, although it compares keys with equals().
6. IdentityHashMap FAQs
Most questions about the class come down to how it differs from HashMap in practice.
6.1. When should we use IdentityHashMap instead of HashMap?
Only when the identity of the key object is what matters, as in object graph traversal, copying or proxy tracking. For keys that represent values, such as names, IDs or numbers, a HashMap is correct, because two equal values must find the same entry.
6.2. Is IdentityHashMap faster than HashMap?
Sometimes, but we should not choose it for speed. For many operation mixes, linear probing performs better than the chaining of HashMap, and System.identityHashCode() avoids custom hashCode() calls. Any gain disappears when the code needs value equality, so we measure before deciding.
6.3. Does IdentityHashMap allow null keys?
Yes. It stores one null key and any number of null values, as the snippet in section 2 shows.
6.4. Is IdentityHashMap thread-safe?
No. We wrap it with Collections.synchronizedMap(new IdentityHashMap<>()) and lock the map while iterating. The JDK has no concurrent identity map.
6.5. How do we create an identity-based Set?
We pass an empty IdentityHashMap to Collections.newSetFromMap(), as countReachable() does. The set uses the map’s keys, so it compares elements with ==.
7. Conclusion
An IdentityHashMap compares keys and values with == and hashes them with System.identityHashCode(), so equal objects stay separate entries and a key keeps its slot even when its fields change. Since Java 20, remove(key, value) and replace() follow the same rule.
Literals and small boxed numbers are shared objects, while strings and numbers created at runtime are new objects, which makes the class a poor fit for value keys. It works well for graph traversal with cycles, deep copies and proxy tracking. Our Java Collections overview puts it next to the general-purpose maps.
8. References
- IdentityHashMap Javadoc (Java 25)
- System.identityHashCode() Javadoc
- JDK-8284901, IdentityHashMap remove and replace use identity
- Integer.valueOf() Javadoc
Happy Learning !!
