

A Kafka cluster is a group of Kafka servers (nodes) that share the work of storing and serving messages. Each topic is split into partitions, and each partition is copied to several nodes, so the cluster keeps working when one node stops. Since Kafka 4.0, the nodes manage the cluster metadata themselves in KRaft mode, and ZooKeeper is no longer used at all.
With Docker Compose, we run a single-node Kafka for development and a 3-node Kafka cluster on one machine for testing replication and failover. For example, before a parcel tracking service goes live, we stop one broker and check that the service still sends its delivery events.
The following example starts a 3-node cluster from the official apache/kafka:4.3.1 image with the docker compose command, creates a topic and stops one node.
docker compose up -d                                  # starts kafka-1, kafka-2, kafka-3
docker exec kafka-1 /opt/kafka/bin/kafka-metadata-quorum.sh \
  --bootstrap-server kafka-1:9092 describe --status   # LeaderId: 3, 3 voters
docker exec kafka-1 /opt/kafka/bin/kafka-topics.sh --bootstrap-server kafka-1:9092 \
  --create --topic deliveries --partitions 3 --replication-factor 3   # Created topic deliveries.
docker compose stop kafka-3                           # partition 2 gets a new leader
docker compose down -v                                # removes containers and data
Notice that stopping kafka-3 moves the leadership of partition 2 to another node, so the deliveries topic stays available.
We start with a single node and build the 3-node cluster from it. After that, we send messages from the console and from a Java 25 client, and we test what happens when one or two nodes stop.
1. What Is a Kafka Cluster?
A Kafka cluster has two roles. Brokers store messages and serve producers and consumers, whereas controllers store the cluster metadata, for example the list of topics and the broker that leads each partition.
In our Docker setup, every node runs both roles. Each Kafka messaging term has a concrete counterpart in our 3-node cluster, such as the topic deliveries with 3 partitions.
| Term | Meaning | In our cluster |
|---|---|---|
| Broker | A Kafka server that stores partitions and answers clients | kafka-1, kafka-2, kafka-3 on port 9092 |
| Controller | A server that stores cluster metadata in the __cluster_metadata log | The same 3 nodes, on port 9093 |
| KRaft quorum | The controllers, which use the Raft protocol to elect one active controller | 3 voters, 1 active leader |
| Topic | A named stream of messages | deliveries |
| Partition | One ordered log of a topic; messages with the same key go to the same partition | 3 partitions: 0, 1, 2 |
| Replica | A copy of a partition on one broker | Replication factor 3: a copy on every node |
| Leader | The replica that handles all writes and reads for a partition | One per partition, spread over the nodes |
| ISR | In-sync replicas: the leader plus the followers that have all its messages | Isr: 1,2,3 when all nodes are up |
| min.insync.replicas | How many ISR members must have a message before an acks=all write succeeds | 2 |
Each partition has one leader and the other replicas follow it. Kafka spreads the leaders over the brokers, so every node handles part of the traffic. In our cluster, each of the three partitions got its leader on a different node.

1.1. KRaft Mode Replaces ZooKeeper
Older Kafka versions kept the metadata in a separate Apache ZooKeeper cluster. Kafka 4.0 removed ZooKeeper mode, so a Kafka 4.x node starts only in KRaft mode. The old ZooKeeper settings no longer exist, and each one has a KRaft replacement.
| ZooKeeper mode (Kafka 3.x and older) | KRaft mode (Kafka 4.x) |
|---|---|
| Separate zookeeper containers | No extra containers |
| KAFKA_BROKER_ID | KAFKA_NODE_ID |
| KAFKA_ZOOKEEPER_CONNECT: zookeeper:2181 | KAFKA_CONTROLLER_QUORUM_VOTERS: 1@kafka-1:9093,… |
| ZooKeeper elects the controller broker | The controllers elect the active controller with Raft |
1.2. Combined Nodes or Separate Controllers
A KRaft node has a process.roles setting, which takes one of three values.
- The value broker,controller makes a combined node that runs both roles in one process.
- The value controller makes a controller only, which stores metadata and serves no clients.
- The value broker makes a broker only, which follows the controllers listed in controller.quorum.voters.
We use 3 combined nodes, which give us a real 3-voter quorum and 3 brokers with only 3 containers, so the setup runs on a laptop. Combined mode is not recommended in critical deployments, because controllers and brokers cannot be scaled or restarted separately. For production, we run 3 or 5 controller-only nodes and separate broker nodes.
2. Kafka Single-Node Setup Using Docker Compose
A single node is enough for local development and for running a Spring Boot or Java application against a real broker. The node runs both roles and is its own one-voter quorum. Without CLUSTER_ID, the image uses its built-in ID 5L6g3nShT-eMCtK–X86sw.
services:
  kafka:
    image: apache/kafka:4.3.1
    container_name: kafka
    ports:
      - "9092:9092"
    environment:
      KAFKA_NODE_ID: 1
      KAFKA_PROCESS_ROLES: broker,controller
      KAFKA_CONTROLLER_QUORUM_VOTERS: 1@kafka:9093
      KAFKA_LISTENERS: INTERNAL://:19092,EXTERNAL://:9092,CONTROLLER://:9093
      KAFKA_ADVERTISED_LISTENERS: INTERNAL://kafka:19092,EXTERNAL://localhost:9092
      KAFKA_LISTENER_SECURITY_PROTOCOL_MAP: INTERNAL:PLAINTEXT,EXTERNAL:PLAINTEXT,CONTROLLER:PLAINTEXT
      KAFKA_INTER_BROKER_LISTENER_NAME: INTERNAL
      KAFKA_CONTROLLER_LISTENER_NAMES: CONTROLLER
      KAFKA_LOG_DIRS: /var/lib/kafka/data
      KAFKA_OFFSETS_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_TRANSACTION_STATE_LOG_REPLICATION_FACTOR: 1
      KAFKA_TRANSACTION_STATE_LOG_MIN_ISR: 1
      KAFKA_SHARE_COORDINATOR_STATE_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_SHARE_COORDINATOR_STATE_TOPIC_MIN_ISR: 1
      KAFKA_GROUP_INITIAL_REBALANCE_DELAY_MS: 0
    volumes:
      - kafka-data:/var/lib/kafka/data

volumes:
  kafka-data:
The image turns every KAFKA_ variable into a server property. It drops the prefix, lowercases the name and replaces underscores with dots, so KAFKA_NODE_ID becomes node.id. When we pass any of these variables, the image no longer applies its built-in configuration, so every required property must be in the file. Eight properties matter most for a single node.
| Variable | Property | Why we set it |
|---|---|---|
| KAFKA_NODE_ID | node.id | Unique, permanent ID of the node in the cluster |
| KAFKA_PROCESS_ROLES | process.roles | Runs the broker and the controller in one process |
| KAFKA_CONTROLLER_QUORUM_VOTERS | controller.quorum.voters | The controllers as id@host:port; here only node 1 |
| KAFKA_LISTENERS | listeners | The ports the node opens inside the container |
| KAFKA_ADVERTISED_LISTENERS | advertised.listeners | The addresses the node gives to clients; localhost:9092 for the host |
| KAFKA_LISTENER_SECURITY_PROTOCOL_MAP | listener.security.protocol.map | Maps each listener name to a protocol; all PLAINTEXT here |
| KAFKA_LOG_DIRS | log.dirs | Where data is written; without it the image writes to /tmp/kafka-logs and the volume stays empty |
| KAFKA_OFFSETS_TOPIC_REPLICATION_FACTOR | offsets.topic.replication.factor | The default is 3, which a single node cannot satisfy |
The node needs three listeners. EXTERNAL is for applications on the host, INTERNAL is for CLI tools and other containers in the Docker network, and CONTROLLER is for the KRaft quorum. So a host application connects to localhost:9092, whereas a container connects to kafka:19092.
With -d, Docker Compose starts the node in the background.
docker compose -f docker-compose-single-node.yaml up -d
docker compose -f docker-compose-single-node.yaml ps
NAME STATUS PORTS
kafka Up 15 seconds 0.0.0.0:9092->9092/tcpA topic on a single node can have only 1 replica, and every partition leader is node 1.
Topic: deliveries	PartitionCount: 3	ReplicationFactor: 1	Configs: min.insync.replicas=1
	Topic: deliveries	Partition: 0	Leader: 1	Replicas: 1	Isr: 1
	Topic: deliveries	Partition: 1	Leader: 1	Replicas: 1	Isr: 1
	Topic: deliveries	Partition: 2	Leader: 1	Replicas: 1	Isr: 1
3. Kafka Multi-Node Cluster Setup Using Docker Compose
For proof-of-concept or non-critical development work, a single node is enough, but a single node has three limits.
- Scalability is limited, because the replication factor is 1 and all partitions are on one broker, so the load cannot be spread.
- There is no failover, so when the node’s disk is lost, the data is lost too, because no other node has a copy.
- Availability depends on one broker, so when the broker stops, producers and consumers stop too.
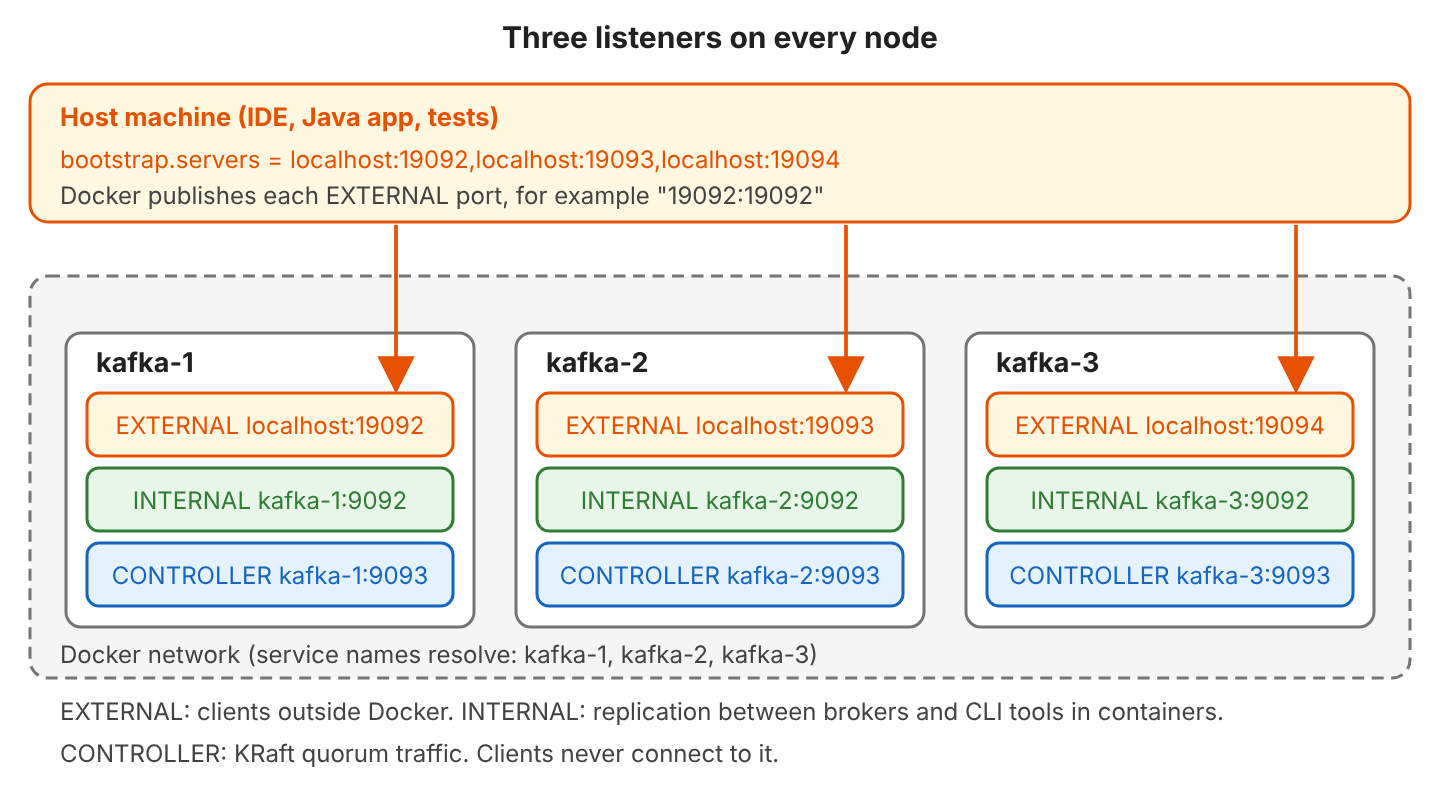
The 3-node cluster has three services, kafka-1, kafka-2 and kafka-3, which differ only in the node ID, the host name and the external port. We show the kafka-1 service, and the other two follow the same pattern.
services:
  kafka-1:
    image: apache/kafka:4.3.1
    container_name: kafka-1
    hostname: kafka-1
    ports:
      - "19092:19092"
    environment:
      CLUSTER_ID: cirCrmlfR1KIv_dQKZVYNA
      KAFKA_NODE_ID: 1
      KAFKA_PROCESS_ROLES: broker,controller
      KAFKA_CONTROLLER_QUORUM_VOTERS: 1@kafka-1:9093,2@kafka-2:9093,3@kafka-3:9093
      KAFKA_LISTENERS: INTERNAL://:9092,EXTERNAL://:19092,CONTROLLER://:9093
      KAFKA_ADVERTISED_LISTENERS: INTERNAL://kafka-1:9092,EXTERNAL://localhost:19092
      KAFKA_LISTENER_SECURITY_PROTOCOL_MAP: INTERNAL:PLAINTEXT,EXTERNAL:PLAINTEXT,CONTROLLER:PLAINTEXT
      KAFKA_INTER_BROKER_LISTENER_NAME: INTERNAL
      KAFKA_CONTROLLER_LISTENER_NAMES: CONTROLLER
      KAFKA_LOG_DIRS: /var/lib/kafka/data
      KAFKA_DEFAULT_REPLICATION_FACTOR: 3
      KAFKA_MIN_INSYNC_REPLICAS: 2
      KAFKA_AUTO_CREATE_TOPICS_ENABLE: "false"
      KAFKA_GROUP_INITIAL_REBALANCE_DELAY_MS: 0
    volumes:
      - kafka-1-data:/var/lib/kafka/data
Three settings are new compared to the single node.
- CLUSTER_ID must be the same on all nodes. We generated it once with kafka-storage.sh random-uuid; the image formats the data directory with it on the first start.
- KAFKA_CONTROLLER_QUORUM_VOTERS lists all 3 controllers, identical on every node.
- KAFKA_MIN_INSYNC_REPLICAS: 2 and KAFKA_DEFAULT_REPLICATION_FACTOR: 3 make every topic keep 3 copies and accept a write only when 2 of them have it.
The service name, KAFKA_NODE_ID and the external port must be different for each service.
| Service | KAFKA_NODE_ID | Host port (EXTERNAL) | Docker network (INTERNAL) | Controller |
|---|---|---|---|---|
| kafka-1 | 1 | localhost:19092 | kafka-1:9092 | kafka-1:9093 |
| kafka-2 | 2 | localhost:19093 | kafka-2:9092 | kafka-2:9093 |
| kafka-3 | 3 | localhost:19094 | kafka-3:9092 | kafka-3:9093 |
Each advertised address must be reachable from where the client runs. A Java application on the host uses the three localhost ports, while CLI tools inside the containers use the kafka-N:9092 names.
3.1. Starting the Cluster
We start the cluster from the folder that contains docker-compose.yaml and list the running containers.
docker compose up -d
docker compose ps
NAME STATUS PORTS
kafka-1 Up 20 seconds 9092/tcp, 0.0.0.0:19092->19092/tcp
kafka-2 Up 20 seconds 9092/tcp, 0.0.0.0:19093->19093/tcp
kafka-3 Up 20 seconds 9092/tcp, 0.0.0.0:19094->19094/tcp3.2. Checking the KRaft Quorum
The tool kafka-metadata-quorum.sh shows which controller is the active leader and whether the followers are up to date.
docker exec kafka-1 /opt/kafka/bin/kafka-metadata-quorum.sh \
  --bootstrap-server kafka-1:9092 describe --status
ClusterId: cirCrmlfR1KIv_dQKZVYNA
LeaderId: 3
LeaderEpoch: 1
HighWatermark: 52
MaxFollowerLag: 0
MaxFollowerLagTimeMs: 201
CurrentVoters: [{"id": 1, "endpoints": ["CONTROLLER://kafka-1:9093"]}, {"id": 2, "endpoints": ["CONTROLLER://kafka-2:9093"]}, {"id": 3, "endpoints": ["CONTROLLER://kafka-3:9093"]}]
CurrentObservers: []| Field | Meaning |
|---|---|
| LeaderId: 3 | Node 3 is the active controller |
| LeaderEpoch: 1 | Increases by one with every new controller election |
| HighWatermark | Offset of the last metadata record that a majority of controllers have |
| MaxFollowerLag: 0 | The followers are not behind the leader |
| CurrentVoters | The 3 controllers in the quorum |
| CurrentObservers | Broker-only nodes that read the metadata; none yet |
4. Creating Topics
Kafka stores messages in topics. We create topics explicitly before using them; our cluster sets auto.create.topics.enable to false, so a producer cannot create a topic with wrong settings by mistake. Topics can also be created from code with Spring KafkaAdmin.
In a parcel tracking app, the deliveries topic holds one event for every status change of a parcel. The command creates the topic with 3 partitions and 3 replicas.
docker exec kafka-1 /opt/kafka/bin/kafka-topics.sh --bootstrap-server kafka-1:9092 \
  --create --topic deliveries --partitions 3 --replication-factor 3
# Created topic deliveries.
The –describe option shows the leader, the replicas and the ISR of every partition.
docker exec kafka-1 /opt/kafka/bin/kafka-topics.sh --bootstrap-server kafka-1:9092 \
  --describe --topic deliveries
Topic: deliveries TopicId: KyBwXIx7TpGSotmvrI-iSw PartitionCount: 3 ReplicationFactor: 3 Configs: min.insync.replicas=2
Topic: deliveries Partition: 0 Leader: 1 Replicas: 1,2,3 Isr: 1,2,3 Elr: LastKnownElr:
Topic: deliveries Partition: 1 Leader: 2 Replicas: 2,3,1 Isr: 2,3,1 Elr: LastKnownElr:
Topic: deliveries Partition: 2 Leader: 3 Replicas: 3,1,2 Isr: 3,1,2 Elr: LastKnownElr: Each line of the output describes one partition.
- Leader: 1 is the node that handles reads and writes for partition 0.
- Replicas: 1,2,3 are the nodes that hold a copy. The first one is the preferred leader.
- Isr: 1,2,3 are the replicas that are in sync. All 3 are in sync on a healthy cluster.
- Elr and LastKnownElr belong to the eligible leader replicas feature (KIP-966), which tracks replicas that left the ISR but can still safely become leader. Both stay empty while all nodes are up.
5. Testing the Message Producer and Consumer
Kafka includes a console producer and a console consumer, which are good for experiments and troubleshooting; applications use the producer and consumer APIs instead, as we see in section 6.
The producer reads one message per line from standard input. With parse.key=true, the text before the colon is the message key.
printf 'parcel-1:picked up\nparcel-2:picked up\nparcel-3:picked up\n' | \
  docker exec -i kafka-1 /opt/kafka/bin/kafka-console-producer.sh \
    --bootstrap-server kafka-1:9092,kafka-2:9092,kafka-3:9092 --topic deliveries \
    --reader-property parse.key=true --reader-property key.separator=:
We read the messages from another node, kafka-3, to confirm that the cluster replicates them. The –from-beginning option reads the topic from the first offset.
docker exec kafka-3 /opt/kafka/bin/kafka-console-consumer.sh \
  --bootstrap-server kafka-1:9092,kafka-2:9092,kafka-3:9092 --topic deliveries \
  --from-beginning --max-messages 3 \
  --formatter-property print.key=true --formatter-property print.partition=true
Partition:2 parcel-2 picked up
Partition:2 parcel-3 picked up
Partition:0 parcel-1 picked up
Processed a total of 3 messagesKafka keeps the order only inside one partition. The key decides the partition, so all messages for parcel-1 stay in order, while messages from different partitions can arrive in any order.
6. Connecting a Java Application to the Cluster
A Java application on the host uses the three EXTERNAL addresses. The kafka-clients library needs only one reachable broker to start, but listing all three lets the client start when one node is down.
<dependency>
  <groupId>org.apache.kafka</groupId>
  <artifactId>kafka-clients</artifactId>
  <version>4.3.1</version>
</dependency>
props.put(ProducerConfig.BOOTSTRAP_SERVERS_CONFIG, "localhost:19092,localhost:19093,localhost:19094");
props.put(ProducerConfig.ACKS_CONFIG, "all"); // wait for min.insync.replicas
props.put(ProducerConfig.ENABLE_IDEMPOTENCE_CONFIG, "true"); // no duplicates on retry
RecordMetadata meta = producer.send(
new ProducerRecord<>("deliveries", "parcel-4", "out for delivery")).get();
int partition = meta.partition(); // 2
long offset = meta.offset(); // 2props.put(ConsumerConfig.GROUP_ID_CONFIG, "app-" + UUID.randomUUID());
props.put(ConsumerConfig.AUTO_OFFSET_RESET_CONFIG, "earliest");
props.put(ConsumerConfig.GROUP_PROTOCOL_CONFIG, "consumer"); // new rebalance protocol
consumer.subscribe(Set.of("deliveries"));
ConsumerRecords<String, String> records = consumer.poll(Duration.ofMillis(500)); // records for parcel-4, parcel-5, parcel-6The demo sends three parcels and reads them back.
Cluster cirCrmlfR1KIv_dQKZVYNA, nodes 3
Sent parcel-4 to partition 2 at offset 2
Sent parcel-5 to partition 1 at offset 0
Sent parcel-6 to partition 2 at offset 3
Read parcel-4=out for delivery from partition 2
Read parcel-6=out for delivery from partition 2
Read parcel-5=out for delivery from partition 1
The complete project has the compose files and a Maven module, kafka-client, with the producer, the consumer and 3 JUnit 6 tests. The tests check that the cluster has 3 nodes with 3 replicas per partition, and that two messages with the same key land in the same partition in order. We run them with mvn test while the cluster is up. In a Spring Boot application with Kafka, the same settings go into the *spring.kafka.** properties.
7. Testing Broker Failover
Replication is useful only if the cluster survives a stopped node. We stop the node that is the active controller and the leader of partition 2, which tests both elections at once.
7.1. Stopping One Node
docker compose stop kafka-3A new controller takes over within seconds, and LeaderEpoch grows from 1 to 2.
ClusterId:              cirCrmlfR1KIv_dQKZVYNA
LeaderId:               1
LeaderEpoch:            2
The new controller elects a new leader for partition 2 and removes node 3 from every ISR.
	Topic: deliveries	Partition: 0	Leader: 1	Replicas: 1,2,3	Isr: 1,2
	Topic: deliveries	Partition: 1	Leader: 2	Replicas: 2,3,1	Isr: 2,1
	Topic: deliveries	Partition: 2	Leader: 1	Replicas: 3,1,2	Isr: 1,2
Producers and consumers keep working, because every ISR still has 2 members, which meets min.insync.replicas=2.
printf 'parcel-1:delivered\nparcel-5:delivered\n' | \
  docker exec -i kafka-1 /opt/kafka/bin/kafka-console-producer.sh \
    --bootstrap-server kafka-1:9092,kafka-2:9092 --topic deliveries \
    --reader-property parse.key=true --reader-property key.separator=:
Partition:2 parcel-2 picked up
Partition:2 parcel-3 picked up
Partition:2 parcel-4 out for delivery
Partition:2 parcel-6 out for delivery
Partition:0 parcel-1 picked up
Partition:0 parcel-1 deliveredAll messages written before the failure are still readable, including partition 2, whose leader was the stopped node.
7.2. Stopping Two of Three Nodes
With kafka-1 stopped as well, only kafka-2 is left, and two rules fail at the same time.
- The KRaft quorum needs a majority, 2 of 3 controllers, to elect a leader. With 1 of 3, no controller is active.
- Every ISR has only 1 member, but min.insync.replicas is 2.
Kafka then rejects writes instead of accepting messages that exist on only one disk.
WARN [Producer clientId=console-producer] Got error produce response with correlation id 5 on topic-partition deliveries-2, retrying (2 attempts left). Error: NOT_ENOUGH_REPLICAS
ERROR Error when sending message to topic deliveries with key: 8 bytes, value: 9 bytes with error:
org.apache.kafka.common.errors.NotEnoughReplicasException: Messages are rejected since there are fewer in-sync replicas than required.
Creating a topic needs the active controller, so the command times out.
Error while executing topic command : Call(callName=createTopics, ...) timed out at 1791060489180 after 1 attempt(s)Each operation we tried behaved differently with only one node left.
| Operation with only kafka-2 up | Result |
|---|---|
| Produce with acks=all | Rejected with NotEnoughReplicasException |
| Read a partition with –partition 0 –offset earliest (no group) | Works; every stored message in all 3 partitions was readable |
| Consumer with a group (–group dispatch) | Times out; the broker log shows the group coordinator’s writes to __consumer_offsets timing out |
| kafka-topics.sh –create | Times out after 60 seconds |
| kafka-metadata-quorum.sh describe | No answer within 45 seconds |

7.3. Starting the Nodes Again
After docker compose start kafka-3 kafka-1, the stopped nodes copy the messages they missed and rejoin every ISR. Leadership does not move back at once, so node 2 leads all three partitions for a while.
	Topic: deliveries	Partition: 0	Leader: 2	Replicas: 1,2,3	Isr: 1,2,3
	Topic: deliveries	Partition: 1	Leader: 2	Replicas: 2,3,1	Isr: 1,2,3
	Topic: deliveries	Partition: 2	Leader: 2	Replicas: 3,1,2	Isr: 1,2,3
The controller moves leaders back to the preferred replica (the first one in Replicas) every 300 seconds, the default of leader.imbalance.check.interval.seconds. We can trigger the election right away with kafka-leader-election.sh.
docker exec kafka-1 /opt/kafka/bin/kafka-leader-election.sh --bootstrap-server kafka-1:9092 \
  --election-type preferred --topic deliveries --partition 0
# Successfully completed leader election (PREFERRED) for partitions deliveries-0
After the election for partitions 0 and 2, the leaders are 1, 2 and 3 again.
8. Modifying the Cluster Configuration
Adding a broker does not need a restart of the existing nodes. A broker-only node has KAFKA_PROCESS_ROLES: broker, the same CLUSTER_ID and the same voters list, and no CONTROLLER listener of its own.
  kafka-4:
    image: apache/kafka:4.3.1
    ports:
      - "19095:19095"
    environment:
      CLUSTER_ID: cirCrmlfR1KIv_dQKZVYNA
      KAFKA_NODE_ID: 4
      KAFKA_PROCESS_ROLES: broker
      KAFKA_CONTROLLER_QUORUM_VOTERS: 1@kafka-1:9093,2@kafka-2:9093,3@kafka-3:9093
      KAFKA_LISTENERS: INTERNAL://:9092,EXTERNAL://:19095
      KAFKA_ADVERTISED_LISTENERS: INTERNAL://kafka-4:9092,EXTERNAL://localhost:19095
Compose merges the second file into the running project and starts only the new service.
docker compose -f docker-compose.yaml -f docker-compose-add-broker.yaml up -dThe quorum lists node 4 as an observer, which is a broker that reads the metadata but does not vote.
CurrentObservers: [{"id": 4, "directoryId": "aUd2pA8AFatq4uXu4PHEkA"}]A new broker gets no existing partitions on its own. We move replicas to it with kafka-reassign-partitions.sh, which runs in three steps.
- The –generate option proposes a plan for brokers 1 to 4.
- The –execute option applies the plan.
- The –verify option confirms that the reassignment is complete.
kafka-reassign-partitions.sh --bootstrap-server kafka-1:9092 \
  --topics-to-move-json-file /tmp/topics.json --broker-list 1,2,3,4 --generate
kafka-reassign-partitions.sh --bootstrap-server kafka-1:9092 \
  --reassignment-json-file /tmp/plan.json --execute
kafka-reassign-partitions.sh --bootstrap-server kafka-1:9092 \
  --reassignment-json-file /tmp/plan.json --verify
# Reassignment of partition deliveries-0 is completed.
Topic: deliveries Partition: 0 Leader: 1 Replicas: 4,1,2 Isr: 1,2,4
Topic: deliveries Partition: 1 Leader: 2 Replicas: 1,2,3 Isr: 1,2,3
Topic: deliveries Partition: 2 Leader: 3 Replicas: 2,3,4 Isr: 2,3,4Other changes need more care.
- To remove a broker, we move its replicas to other brokers with kafka-reassign-partitions.sh first, and stop and remove the service after that.
- The controllers are hard to change, because the image uses a static voters list (controller.quorum.voters), which is fixed when the cluster is formatted. For a local cluster, it is simpler to change all services and recreate the cluster with docker compose down -v.
- To change a broker setting, we edit the file and run docker compose up -d. Compose recreates only the changed services, and the volumes keep the data.
9. Kafka Cluster FAQs
9.1. Can I Still Use the Confluent cp-kafka Image?
Yes, but not with ZooKeeper. Confluent Platform 8.0 is based on Kafka 4.0 and removed ZooKeeper. The confluentinc/cp-kafka:latest tag points to an 8.x release (8.3.2 on Docker Hub when we checked). An old compose file with confluentinc/cp-zookeeper and KAFKA_ZOOKEEPER_CONNECT needs a KRaft configuration like the one in section 3, or a pinned 7.x tag. The cp-kafka image uses the same KAFKA_ variable style, and it adds Confluent’s own components and support.
9.2. Why Can My Application Not Connect to Kafka in Docker?
The client first connects to the bootstrap address, and the broker answers with its advertised addresses, which the client uses for all further requests. If KAFKA_ADVERTISED_LISTENERS returns kafka-1:9092 to an application on the host, the host cannot resolve kafka-1 and the connection fails. Each client must receive an address it can reach, which is localhost:19092 for the host and kafka-1:9092 for other containers.
9.3. How Many Nodes Does a Kafka Cluster Need?
| Nodes | Replication factor | Survives |
|---|---|---|
| 1 | 1 | No failures; development only |
| 3 | 3, min.insync.replicas=2 | 1 stopped node, without losing writes |
| 5 controllers | 3 or more | 2 stopped controllers |
A KRaft quorum of 3 controllers tolerates 1 failure, and a quorum of 5 tolerates 2. An even number adds no tolerance, because 4 controllers still need 3 for a majority.
9.4. What Is the Difference Between docker-compose and docker compose?
The docker-compose command is the old standalone Compose v1 tool, which is no longer maintained. The docker compose command is the Compose plugin of the Docker CLI. Our files follow the Compose specification and have no version: line. If a file has one, Compose prints a warning that the attribute is obsolete and ignores it.
9.5. How Do I Reset the Cluster?
The command docker compose down removes the containers but keeps the named volumes, so the topics and messages are still there on the next up. With -v, the command removes the volumes too, so the next cluster starts empty. A new CLUSTER_ID on existing volumes does not work, because the node stores the ID in meta.properties and exits on start when the ID differs.
java.lang.RuntimeException: Invalid cluster.id in: /var/lib/kafka/data/meta.properties. Expected AAAAAAAAAAAAAAAAAAAAAA, but read 5L6g3nShT-eMCtK--X86sw9.6. Does Kafka Need ZooKeeper?
No. Kafka 4.0 and newer cannot use ZooKeeper. Kafka 3.x can run in either mode, and a ZooKeeper-based cluster must be migrated to KRaft on Kafka 3.x before an upgrade to 4.x.
10. Conclusion
A single combined node is enough for local development, and three combined nodes give a real KRaft quorum and replication on one machine. With replication factor 3 and min.insync.replicas=2, the cluster survived one stopped node, and new leaders were elected within seconds. With two nodes down, the cluster rejected writes instead of risking data loss. For production, we use separate controller nodes.
11. References
- Apache Kafka 4.3 documentation
- KRaft operations (Kafka 4.3)
- Broker configuration reference (Kafka 4.3)
- Upgrading to Kafka 4.0: ZooKeeper removal
- apache/kafka image on Docker Hub
- Docker Compose documentation
- Confluent Platform deprecations
Happy Learning !!

Great Article, Thanks for your effort.