

A Java Spliterator (splittable iterator) is an interface in java.util that traverses the elements of a source and can split off part of them into a second Spliterator, so that two threads can process the parts in parallel. Every collection in the Java Collections Framework has one, and streams use it to read their source and to divide the work of a parallel stream.
Most of the time we use a Spliterator without seeing it, through stream() and parallelStream(). We call it ourselves when we turn an unusual source into a stream, process elements in batches, or split work for a fork/join task. The following example splits a list of books and reads one element.
List<String> books = new ArrayList<>(List.of("Dune", "Emma", "Ulysses", "Beloved"));
Spliterator<String> rest = books.spliterator();
Spliterator<String> prefix = rest.trySplit();
long prefixSize = prefix.estimateSize();                        // 2, holds Dune and Emma
long restSize = rest.estimateSize();                            // 2, holds Ulysses and Beloved
boolean moved = rest.tryAdvance(b -> System.out.println(b));    // true, prints Ulysses
boolean sized = rest.hasCharacteristics(Spliterator.SIZED);     // true
long total = StreamSupport.stream(books.spliterator(), true).count();   // 4
Notice that trySplit() returns the first half and the original keeps the second half. We go through the features and methods, the link between spliterators and streams, an example for each method, the late-binding and fail-fast rules of the ArrayList spliterator, batching, fork/join splitting and a custom Spliterator for a paged source.
1. Features of Spliterator
The Spliterator interface was added in Java 8 together with streams. It does the job of an Iterator with fewer calls per element, and adds the information a parallel stream needs to divide the work.
- The tryAdvance() method combines hasNext() and next() into one call that passes the next element to a lambda and returns false when no element is left.
- The forEachRemaining() method processes all remaining elements sequentially in the current thread.
- The trySplit() method hands part of the elements to a new Spliterator, or returns null when the source cannot or should not be split further.
- The characteristics() method reports facts about the source, such as ORDERED, SIZED or SORTED, which streams use to skip unneeded work.
- The estimateSize() method reports how many elements are left, which helps decide whether splitting is worth it.
A single Spliterator is not thread-safe. The parallel model is that we split first and give each resulting Spliterator to a single thread, so no two threads ever share an instance.
2. Spliterator Methods
The interface has four abstract methods, tryAdvance(), trySplit(), estimateSize() and characteristics(). The rest are default methods built on top of them.
| Method Name | Description |
|---|---|
| tryAdvance(Consumer action) | If a remaining element exists, performs the action on it and returns true, else returns false |
| forEachRemaining(Consumer action) | Performs the action for each remaining element, sequentially in the current thread, until all elements are processed or the action throws an exception |
| trySplit() | If the spliterator can be partitioned, returns a Spliterator covering some of the elements, which this one no longer covers, else returns null |
| estimateSize() | Returns an estimate of the remaining elements, or Long.MAX_VALUE if infinite, unknown or too expensive to compute |
| getExactSizeIfKnown() | Returns estimateSize() if this spliterator is SIZED, else -1 |
| characteristics() | Returns the characteristics as an int bit set of ORDERED, DISTINCT, SORTED, SIZED, NONNULL, IMMUTABLE, CONCURRENT and SUBSIZED |
| hasCharacteristics(int) | Returns true if all given characteristics are present |
| getComparator() | Returns the Comparator of a SORTED source, null for natural ordering, and throws IllegalStateException if the source is not SORTED |
3. Spliterator with Stream
The Collection interface implements stream() and parallelStream() as default methods that pass the collection’s spliterator() to StreamSupport.stream(). The boolean argument selects a sequential or a parallel stream.
// does not compile: simplified excerpt of java.util.Collection
default Stream<E> stream() {
    return StreamSupport.stream(spliterator(), false);
}

default Stream<E> parallelStream() {
    return StreamSupport.stream(spliterator(), true);
}
We call StreamSupport.stream() ourselves when a source offers only an Iterator. The Spliterators.spliteratorUnknownSize() method wraps the iterator, and the resulting spliterator splits by copying elements into batches, so it works in a parallel stream but splits less evenly than a collection’s own spliterator.
Iterator<String> legacy = List.of("Dune", "Emma").iterator();
Spliterator<String> wrapped = Spliterators.spliteratorUnknownSize(legacy, Spliterator.ORDERED);
List<String> titles = StreamSupport.stream(wrapped, false).map(String::toUpperCase).toList();   // [DUNE, EMMA]
4. Java Spliterator Example
The examples use small lists, so every result fits in a comment. Each one shows one method or group of methods from section 2.
4.1. Spliterator characteristics() Example
The characteristics depend on the collection class. A stream uses them to skip work, for example it skips distinct() on a DISTINCT source and knows the exact count of a SIZED source without counting. The table lists the values that JDK 25 reports.
| Source | Characteristics |
|---|---|
| ArrayList, LinkedList, List.of() | ORDERED, SIZED, SUBSIZED |
| HashSet | DISTINCT, SIZED |
| TreeSet | ORDERED, DISTINCT, SORTED, SIZED |
| CopyOnWriteArrayList | ORDERED, SIZED, IMMUTABLE, SUBSIZED |
| ConcurrentHashMap.keySet() | DISTINCT, NONNULL, CONCURRENT |
| IntStream.range() | ORDERED, DISTINCT, SORTED, SIZED, NONNULL, IMMUTABLE, SUBSIZED |
List<String> list = new ArrayList<>(List.of("Dune"));
Spliterator<String> spliterator = list.spliterator();
int expected = Spliterator.ORDERED | Spliterator.SIZED | Spliterator.SUBSIZED;
boolean same = spliterator.characteristics() == expected;            // true
boolean ordered = spliterator.hasCharacteristics(Spliterator.ORDERED);   // true
boolean sorted = spliterator.hasCharacteristics(Spliterator.SORTED);     // false
boolean distinct = new HashSet<>(list).spliterator().hasCharacteristics(Spliterator.DISTINCT);   // true
The IMMUTABLE flag on CopyOnWriteArrayList means that the spliterator reads a snapshot, not that the list cannot change. The CONCURRENT flag on ConcurrentHashMap means that other threads may change the map safely during traversal.
4.2. Spliterator estimateSize() and getExactSizeIfKnown()
For a SIZED source, both methods return the exact number of remaining elements. When a source loses SIZED after a split, as a HashSet does, estimateSize() still returns a guess and getExactSizeIfKnown() returns -1.
Spliterator<String> fromList = new ArrayList<>(List.of("A", "B", "C", "D")).spliterator();
long estimate = fromList.estimateSize();                  // 4
long exact = fromList.getExactSizeIfKnown();              // 4
Spliterator<Integer> fromSet = new HashSet<>(Set.of(1, 2, 3, 4, 5, 6)).spliterator();
Spliterator<Integer> half = fromSet.trySplit();
long guess = fromSet.estimateSize();                      // 3
long unknown = fromSet.getExactSizeIfKnown();             // -1
4.3. Spliterator getComparator()
The getComparator() method returns the Comparator of a SORTED source, so a stream can tell whether a later sorted() call is needed. It returns null when the source uses natural ordering, and it throws IllegalStateException when the source is not sorted at all.
SortedSet<String> reversed = new TreeSet<>(Comparator.reverseOrder());
reversed.addAll(List.of("A", "D", "C", "B"));
String content = reversed.toString();                     // "[D, C, B, A]"
boolean custom = reversed.spliterator().getComparator() != null;     // true
Comparator<? super String> natural = new TreeSet<String>().spliterator().getComparator();   // null
Comparator<? super String> none = new ArrayList<String>().spliterator().getComparator();    // IllegalStateException
4.4. Spliterator trySplit() Example
The trySplit() method moves a prefix of the remaining elements into a new Spliterator and returns it, while the original keeps the rest. An ArrayList splits at the midpoint, and repeated splits form a tree whose leaves are processed by different threads.
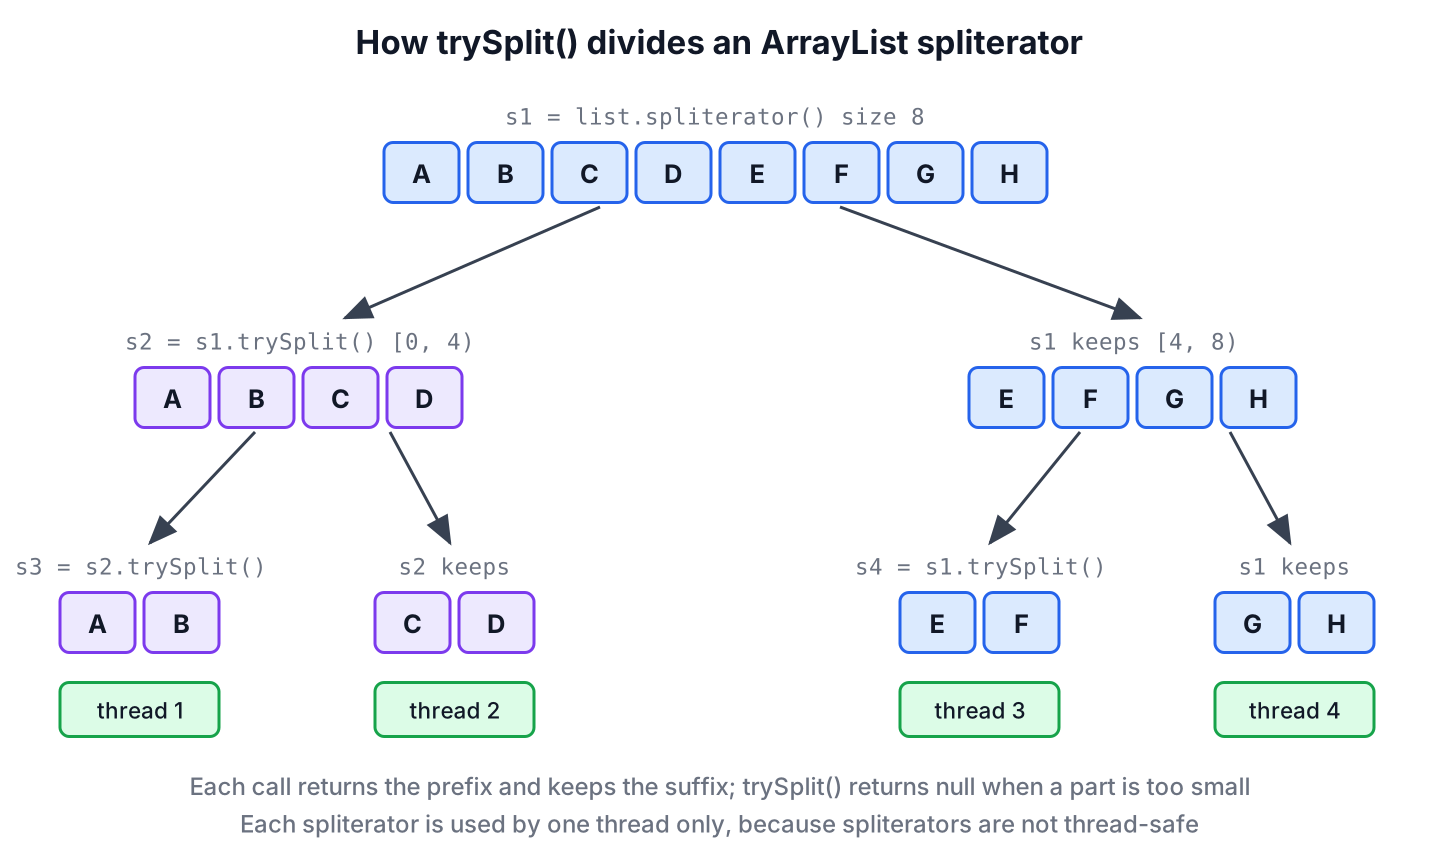
List<String> letters = new ArrayList<>(List.of("A", "B", "C", "D", "E", "F"));
Spliterator<String> spliterator1 = letters.spliterator();
Spliterator<String> spliterator2 = spliterator1.trySplit();
List<String> kept = new ArrayList<>();
spliterator1.forEachRemaining(kept::add);
List<String> splitOff = new ArrayList<>();
spliterator2.forEachRemaining(splitOff::add);
String original = kept.toString();                        // "[D, E, F]"
String returned = splitOff.toString();                    // "[A, B, C]"
Spliterator<String> tiny = new ArrayList<>(List.of("A")).spliterator();
Spliterator<String> nothing = tiny.trySplit();            // null
Equal halves are an ArrayList detail, not a rule of the interface. A LinkedList cannot jump to its middle, so its trySplit() copies a batch of elements from the front into an array, and for a short list that batch holds every element and leaves the original empty.
4.5. Spliterator tryAdvance() and forEachRemaining()
The tryAdvance() method reads one element per call, which suits loops that stop early or read a few elements first. The forEachRemaining() method reads all the rest in one call, which saves a method call per element.
List<Integer> pageViews = new ArrayList<>(List.of(120, 80, 45, 300, 10, 75));
Spliterator<Integer> views = pageViews.spliterator();
List<Integer> seen = new ArrayList<>();
boolean first = views.tryAdvance(seen::add);              // true
boolean second = views.tryAdvance(seen::add);             // true
views.forEachRemaining(seen::add);
String all = seen.toString();                             // "[120, 80, 45, 300, 10, 75]"
boolean more = views.tryAdvance(seen::add);               // false
5. ArrayList spliterator() Is Late-Binding and Fail-Fast
The ArrayList.spliterator() method returns a Spliterator that is late-binding and fail-fast. Late-binding means it reads the list size at the first traversal, first split or first size query, not when spliterator() is called. Fail-fast means it throws ConcurrentModificationException when the list changes structurally, such as by add() or remove(), after binding.
List<Integer> numbers = new ArrayList<>(List.of(1, 2, 3));
Spliterator<Integer> lazy = numbers.spliterator();
boolean added = numbers.add(4);                           // true, before binding
long boundSize = lazy.estimateSize();                     // 4
boolean read = lazy.tryAdvance(n -> {});                  // true
boolean addedLate = numbers.add(5);                       // true, after binding
lazy.forEachRemaining(n -> {});                           // ConcurrentModificationException
Replacing an element with set() is not a structural change, so it does not throw, and the spliterator reads the new value if it has not passed that index yet. The ArrayList spliterator reports ORDERED, SIZED and SUBSIZED, and it is not SORTED, because a list keeps insertion order.
6. Processing Elements in Batches
Say an e-commerce app exports order ids to a shipping API that accepts at most 3 ids per request. The tryAdvance() method fills one batch at a time, so the code never builds an extra list of all batches when the source is large.
List<Integer> orderIds = IntStream.rangeClosed(1, 7).boxed().toList();
Spliterator<Integer> source = orderIds.spliterator();
List<List<Integer>> requests = new ArrayList<>();
List<Integer> batch = new ArrayList<>();
while (source.tryAdvance(batch::add)) {
    if (batch.size() == 3) {
        requests.add(List.copyOf(batch));      // send the batch here
        batch.clear();
    }
}
if (!batch.isEmpty()) {
    requests.add(List.copyOf(batch));
}
int requestCount = requests.size();                       // 3
List<Integer> lastBatch = requests.getLast();             // [7]
On Java 24 and later, the Gatherers.windowFixed() stream operation does the same in one line, and it is the better choice when the code already uses a stream.
List<Integer> orderIds = IntStream.rangeClosed(1, 7).boxed().toList();
List<List<Integer>> windows = orderIds.stream().gather(Gatherers.windowFixed(3)).toList();   // [[1, 2, 3], [4, 5, 6], [7]]
7. Splitting Work with Fork/Join
A parallel stream splits its spliterator recursively and runs the parts on the common ForkJoinPool. Writing the same thing by hand shows how trySplit() is meant to be used, with one thread per part and no shared spliterator.
class SumTask extends RecursiveTask<Long> {
    private final Spliterator<Integer> source;

    SumTask(Spliterator<Integer> source) {
        this.source = source;
    }

    @Override
    protected Long compute() {
        if (source.estimateSize() > 1_000) {
            Spliterator<Integer> prefix = source.trySplit();
            if (prefix != null) {
                SumTask left = new SumTask(prefix);
                left.fork();
                long right = new SumTask(source).compute();
                return right + left.join();
            }
        }
        long[] sum = {0};
        source.forEachRemaining(n -> sum[0] += n);
        return sum[0];
    }
}
List<Integer> views = IntStream.rangeClosed(1, 10_000).boxed().toList();
long byTask = ForkJoinPool.commonPool().invoke(new SumTask(views.spliterator())); // 50005000
long byStream = views.parallelStream().mapToLong(Integer::longValue).sum(); // 50005000Both lines return the same sum. In real code, the parallel stream is shorter and does the same splitting, so a hand-written task makes sense only when each part needs its own setup, such as a database connection per thread.
8. Writing a Custom Spliterator
A custom Spliterator turns a source that is not a collection into a stream. The Spliterators.AbstractSpliterator class implements trySplit() with batching, so we write only tryAdvance().
The following example reads book titles from a paged source, such as a REST API that returns one page per call, and fetches the next page only when the stream needs more elements.
class PageSpliterator extends Spliterators.AbstractSpliterator<String> {
    private final IntFunction<List<String>> fetchPage;
    private int page = 0;
    private Iterator<String> current = Collections.emptyIterator();

    PageSpliterator(IntFunction<List<String>> fetchPage) {
        super(Long.MAX_VALUE, Spliterator.ORDERED | Spliterator.NONNULL);
        this.fetchPage = fetchPage;
    }

    @Override
    public boolean tryAdvance(Consumer<? super String> action) {
        while (!current.hasNext()) {
            List<String> next = fetchPage.apply(page++);
            if (next.isEmpty()) {
                return false;
            }
            current = next.iterator();
        }
        action.accept(current.next());
        return true;
    }
}
List<List<String>> server = List.of(List.of("Dune", "Emma"), List.of("Ulysses"), List.of());
List<String> allTitles = StreamSupport.stream(new PageSpliterator(server::get), false).toList(); // [Dune, Emma, Ulysses]
Optional<String> firstTitle = StreamSupport.stream(new PageSpliterator(server::get), false).findFirst(); // Optional[Dune]The size is unknown, so we pass Long.MAX_VALUE and leave out SIZED. The findFirst() call fetches only the first page, because the stream pulls elements one by one through tryAdvance().
9. Iterator vs. Spliterator
Both interfaces traverse elements, and a Spliterator is the one streams are built on. The Iterator vs ListIterator vs Spliterator article compares them with ListIterator as well.
| Iterator | Spliterator | |
|---|---|---|
| Since | Java 1.2 | Java 8 |
| Read one element | hasNext() and next() | tryAdvance(action) |
| Remove elements | remove() | Not supported |
| Split for parallel work | No | trySplit() |
| Size and characteristics | No | estimateSize(), characteristics() |
| Available from | Every collection | Every collection, arrays via Arrays.spliterator(), every stream |
10. Spliterator FAQs
Developers search for these questions about Spliterator and parallel streams.
10.1. Is Spliterator thread-safe?
No. A single Spliterator must be used by one thread at a time. Parallel code splits it first and gives each resulting part to a different thread.
10.2. What does trySplit() return when it cannot split?
The method returns null. That happens when the remaining elements are too few to split, as with a one-element ArrayList, or when the source does not support splitting.
10.3. Can we get a Spliterator from a Map?
Not from the map itself, because Map is not a Collection. Call spliterator() on entrySet(), keySet() or values().
10.4. Should we use Spliterator in application code?
Rarely. Streams cover filtering, mapping, batching and parallel work. We write against Spliterator to adapt a custom source into a stream or to control splitting in a fork/join task.
10.5. Why is my parallel stream not faster?
Splitting and merging cost time, and sources such as LinkedList or Iterator-based spliterators split poorly. Parallel streams pay off for large, SIZED sources such as ArrayList or arrays with CPU-heavy work per element.
11. Conclusion
A Spliterator traverses elements with tryAdvance() and forEachRemaining(), splits work with trySplit(), and describes its source with characteristics and a size estimate. Streams build on it, so stream() and parallelStream() cover most use cases.
The ArrayList spliterator binds late, fails fast and splits at the midpoint. We call spliterators ourselves for batching, fork/join tasks and custom sources such as paged APIs, and we never share one instance between threads.
12. References
- Java SE 25 API, Spliterator
- Java SE 25 API, Spliterators
- Java SE 25 API, StreamSupport
- JEP 485, Stream Gatherers
Happy Learning !!

nice understanding with example
Why would you use spliterator if you can use stream?