
JPAstreamer is a library that lets us write JPA queries as standard Java streams, such as jpaStreamer.stream(Book.class).filter(Book$.pages.greaterThan(400)), and translates the stream into a JPA query that runs in the database. It works on top of an existing JPA provider such as Hibernate, so the entities and the EntityManagerFactory stay the same.
We use JPAstreamer for read-heavy code where a type-safe stream reads better than JPQL strings or the Criteria API, such as search screens with optional filters, paging and sorting. It generates a metamodel class (Book$ for Book) at compile time, so a renamed field breaks the build instead of a query at runtime.
The following example finds all books with more than 400 pages, sorted by title, and shows the SQL that Hibernate runs.
List<String> longBooks = jpaStreamer.stream(Book.class)
        .filter(Book$.pages.greaterThan(400))
        .sorted(Book$.title)
        .map(Book::getTitle)
        .toList();                     // [Dune, Emma, Ulysses]
select b1_0.id,b1_0.author,b1_0.available,b1_0.pages,b1_0.title
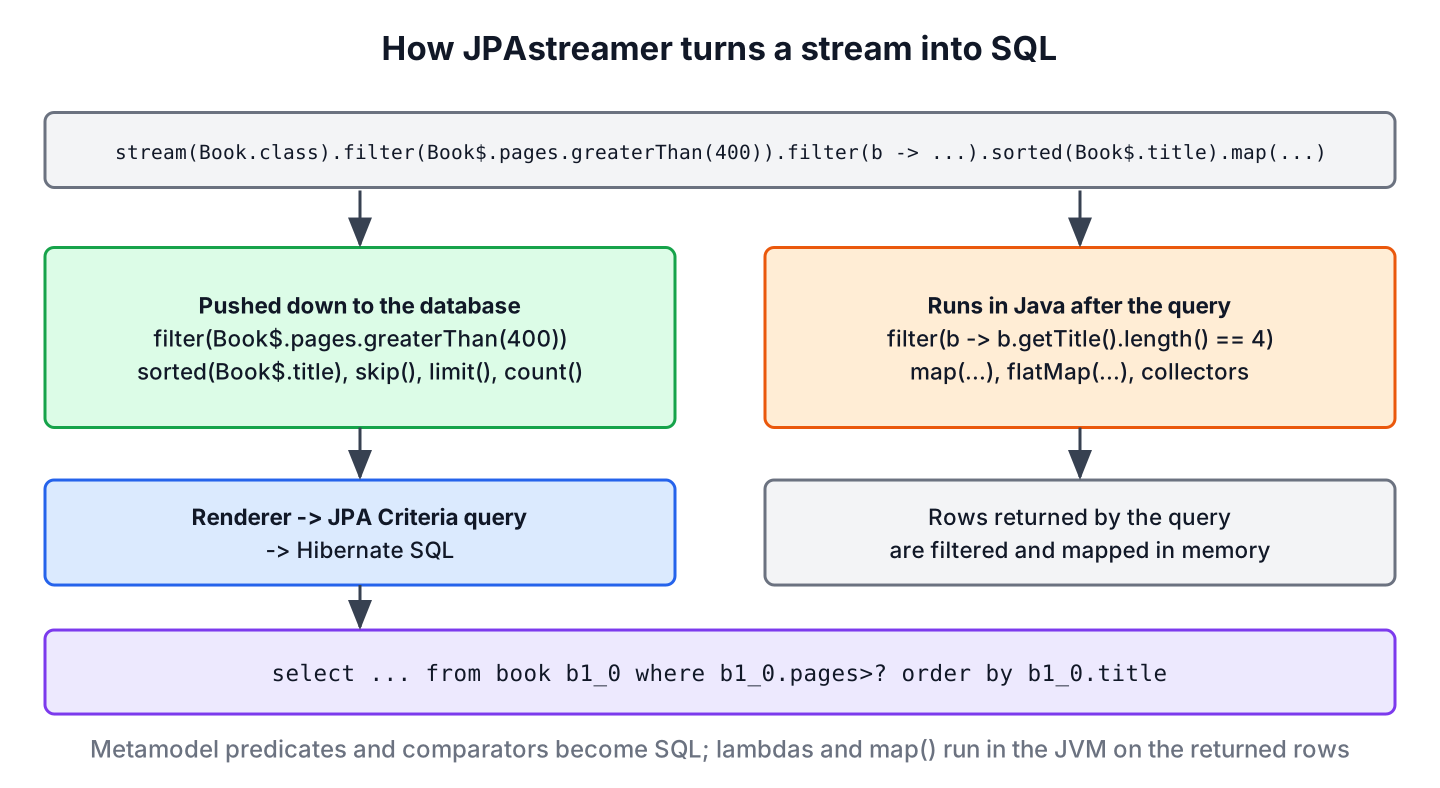
from book b1_0 where b1_0.pages>? order by b1_0.titleNotice that the filter() and sorted() steps became where and order by clauses, so only matching rows leave the database. We set up JPAstreamer on Spring Boot 4.1.1 with Hibernate 7.4 and Java 25, go through predicates, sorting and paging, and look at the current status of the library, including two problems we hit on the current stack and their workarounds.
1. Project Status and Compatibility
Before adding a library to a project, we check that it fits the stack. The latest JPAstreamer release is 3.0.4 from August 2023, published on Maven Central under the LGPL 2.1 license. Version 3 uses the jakarta.persistence namespace, so it compiles against Spring Boot 3 and 4 entities, unlike the 1.x line that required javax.persistence and Spring Boot 2.
On Spring Boot 4.1.1, Hibernate 7.4.5.Final, H2 2.4.240 and JDK 25, the results are mixed, as the table shows.
| Area | Result on Spring Boot 4.1.1 and Hibernate 7.4 |
|---|---|
| Spring Boot autoconfiguration | Not applied; we declare the JPAStreamer bean ourselves (section 2.2) |
| Metamodel generation on JDK 23+ | Works only with explicit annotation processing (section 2.1) |
| Range, like, in, null predicates | Work and run in SQL |
| equal(), notEqual(), isTrue() | Fail with SemanticException; in(value) works as a replacement |
| Sorting, skip(), limit(), count() | Work and run in SQL |
Because the last release is from 2023 and equality predicates fail on Hibernate 7, we use JPAstreamer on new projects only after testing every query shape we need. The GitHub repository lists the open issues. For a long-lived service, Spring Data JPA derived queries, the Criteria API or jOOQ are safer choices, as compared in section 6.
2. Setting Up JPAstreamer in Spring Boot
Setup takes three steps. We add the dependencies, make sure the annotation processor runs, and make a JPAStreamer instance available for injection.
2.1. Maven Dependencies and the Annotation Processor
The jpastreamer-core artifact contains the stream API, the query renderer and the annotation processor that generates the metamodel. The Spring integration artifact only adds autoconfiguration, which Spring Boot 3 and 4 ignore, as the next section explains.
<dependency>
    <groupId>com.speedment.jpastreamer</groupId>
    <artifactId>jpastreamer-core</artifactId>
    <version>3.0.4</version>
</dependency>
Since JDK 23, javac runs annotation processors from the classpath only when the build asks for it. Without the following setting, the build fails with cannot find symbol Book$, because the metamodel class is never generated.
<plugin>
    <groupId>org.apache.maven.plugins</groupId>
    <artifactId>maven-compiler-plugin</artifactId>
    <configuration>
        <compilerArgs>
            <arg>-proc:full</arg>
        </compilerArgs>
    </configuration>
</plugin>
2.2. Declaring the JPAStreamer Bean
The spring-boot-jpastreamer-autoconfigure 3.0.4 artifact registers its configuration in META-INF/spring.factories, which Spring Boot 3 and later no longer read for autoconfiguration. With only that artifact, the application fails at startup with “required a bean of type ‘JPAStreamer’ that could not be found”. A small configuration class fixes it.
@Configuration
public class JpaStreamerConfig {

    @Bean(destroyMethod = "close")
    public JPAStreamer jpaStreamer(EntityManagerFactory emf) {
        return JPAStreamer.of(emf);
    }
}
The bean uses the EntityManagerFactory that Spring Boot created from the spring.datasource properties. Spring closes the instance on shutdown through destroyMethod, so we never call jpaStreamer.close() after a single query, because that would close the whole instance. Streams close themselves after their terminal operation. Outside Spring, JPAStreamer.of(“persistence-unit-name”) creates an instance from a persistence.xml unit.
2.3. The Entity and Its Generated Metamodel
The example uses a Book entity of a library catalog with a title, an author, a page count and an availability flag. JPAstreamer reads the getters to build its metamodel, so the entity needs them.
@Entity
public class Book {
    @Id
    @GeneratedValue
    private Long id;
    private String title;
    private String author;
    private int pages;
    private boolean available;

    protected Book() {
    }

    public Long getId() { return id; }
    public String getTitle() { return title; }
    public String getAuthor() { return author; }
    public int getPages() { return pages; }
    public boolean isAvailable() { return available; }
}
At compile time, the annotation processor writes Book$ into target/generated-sources/annotations. Each field becomes a typed constant, such as IntField for pages or StringField for title, and the field type decides which predicates the compiler offers. The generated code looks like this trimmed version.
public final class Book$ {
    public static final IntField<Book> pages = IntField.create(Book.class, "pages", Book::getPages, false);
    public static final StringField<Book> title = StringField.create(Book.class, "title", Book::getTitle, false);
    public static final StringField<Book> author = StringField.create(Book.class, "author", Book::getAuthor, false);
    public static final BooleanField<Book> available = BooleanField.create(Book.class, "available", Book::isAvailable, false);
}
3. Filtering with Field Predicates
A predicate built from a metamodel field, such as Book$.pages.greaterThan(400), carries the column name and the operator, so JPAstreamer can turn it into SQL. A lambda such as b -> b.getPages() > 400 is opaque Java code, so JPAstreamer has to load the rows and run it in memory.
long between = jpaStreamer.stream(Book.class)
        .filter(Book$.pages.between(300, 450))
        .count();                      // 2
List<String> byAuthor = jpaStreamer.stream(Book.class)
        .filter(Book$.author.startsWith("A"))
        .map(Book::getTitle)
        .toList();                     // [Emma]
long known = jpaStreamer.stream(Book.class)
        .filter(Book$.author.in("Austen", "Joyce"))
        .count();                      // 2
where b1_0.pages>=? and b1_0.pages<? -- between(300, 450)
where b1_0.author like ? escape '' -- startsWith("A")
where b1_0.author in (?,?) -- in("Austen", "Joyce")We can see from the >= and < operators that between() includes the start and excludes the end. The predicates reference lists all predicates, and the most common ones, grouped by field type, are listed in the table with the status we saw on Hibernate 7.4.
| Predicate | Field types | Status on Hibernate 7.4 |
|---|---|---|
| greaterThan, greaterOrEqual, lessThan, lessOrEqual | Numbers, dates, strings | Works |
| between, notBetween | Numbers, dates, strings | Works (start inclusive, end exclusive) |
| in, notIn | All comparable fields | Works |
| isNull, isNotNull | Reference fields | Works |
| startsWith, endsWith, contains, equalIgnoreCase | Strings | Works (like and lower()) |
| equal, notEqual | All fields | Fails with SemanticException |
| isTrue, isFalse | boolean fields | Fails with SemanticException |
| and(), or(), negate() | Combined predicates | Works when the parts work |
The failing predicates throw org.hibernate.query.SemanticException: Cannot compare left expression of type ‘java.lang.String’ with right expression of type ‘java.lang.Object’, which points to a type mismatch between the Criteria query that JPAstreamer 3.0.4 builds and the stricter type checks of Hibernate 7. A single-value in() has the same meaning as equal() and runs as where b1_0.author in (?).
long joyceEqual = jpaStreamer.stream(Book.class).filter(Book$.author.equal("Joyce")).count();   // SemanticException
long joyceIn = jpaStreamer.stream(Book.class).filter(Book$.author.in("Joyce")).count();   // 1
4. Sorting, Paging and Counting
The metamodel fields are also comparators. Passing Book$.title to sorted() becomes an order by clause, and reversed() sorts in descending order. The skip() and limit() steps become offset and fetch first, which makes pagination look like stream code.
int page = 1;                          // zero-based, so the second page
int pageSize = 2;
List<String> secondPage = jpaStreamer.stream(Book.class)
        .sorted(Book$.pages.reversed())
        .skip((long) page * pageSize)
        .limit(pageSize)
        .map(Book::getTitle)
        .toList();                     // [Dune, Beloved]
select b1_0.id,b1_0.author,b1_0.available,b1_0.pages,b1_0.title
from book b1_0 order by b1_0.pages desc offset ? rows fetch first ? rows onlyA count() after a filter becomes select count(b1_0.id), so no entities are loaded. A map() step does not shrink the select list, though. Even map(Book$.title) loads whole entities and extracts the title in Java. For wide tables, the documentation describes projections with StreamConfiguration.of(Book.class).selecting(Projection.select(…)), which we did not test on Hibernate 7.4, and a projection query in Spring Data JPA or JPQL is the proven alternative.
5. What Runs in the Database and What Runs in Memory
Say the catalog search page of a library app lets users filter by page count and author, and someone adds a filter for short titles with a lambda. On a test database with four books, nothing looks wrong. In production, with 200,000 books, every search loads the whole table into memory, because the lambda cannot be translated.
List<String> shortTitles = jpaStreamer.stream(Book.class)
        .filter(b -> b.getTitle().length() == 4)   // lambda, runs in Java
        .sorted(Book$.title)
        .map(Book::getTitle)
        .toList();                                 // [Dune, Emma]
select b1_0.id,b1_0.author,b1_0.available,b1_0.pages,b1_0.title
from book b1_0 order by b1_0.titleThe SQL has no where clause, so the application loads all rows. Notice that the order by clause is still there, even though sorted() comes after the lambda, because JPAstreamer moves steps it can translate into the query when the result stays the same, and runs the rest in memory.
- Metamodel predicates in filter(), metamodel comparators in sorted(), skip(), limit() and count() run in SQL.
- Lambdas in filter(), any map(), flatMap() and collectors run in Java after the query.
- Turning on spring.jpa.show-sql=true during development shows the SQL of every stream, so a missing where clause is visible before production.
6. JPAstreamer vs Spring Data JPA, Criteria API and jOOQ
JPAstreamer is one of several ways to build type-safe queries. The choice depends on how complex the queries are and how much risk the project accepts from a slow-moving dependency.
| Option | Query style | Type safety | Status |
|---|---|---|---|
| JPAstreamer 3.0.4 | Java streams on entities | Generated Book$ metamodel | Last release 2023, issues on Hibernate 7 |
| Spring Data JPA derived queries | Method names such as findByPagesGreaterThan() | Checked at startup | Actively maintained |
| JPA Criteria API with the JPA metamodel | Builder API | Generated Book_ metamodel | Part of Jakarta Persistence |
| QueryDSL | Fluent SQL-like API on entities | Generated QBook classes | Community fork maintained |
| jOOQ | SQL DSL on tables, not entities | Generated table classes | Actively maintained, commercial editions |
For simple filters with paging, Spring Data JPA derived queries or a Specification cover the same needs without an extra library. JPAstreamer is still a good fit for prototypes and internal tools, and for teams that test every query shape they use.
7. JPAstreamer FAQs
Compatibility with current Spring Boot versions and the SQL behind a stream are the two things developers want to know before adopting JPAstreamer.
7.1. Does JPAstreamer work with Spring Boot 3 and 4?
Partly. Version 3.0.4 uses jakarta.persistence and runs on Spring Boot 4.1.1, but its autoconfiguration is not picked up and equality predicates fail on Hibernate 7.4, as listed in section 1. Declaring the bean and using in() works around both problems.
7.2. Is JPAstreamer still maintained?
Releases have stopped since version 3.0.4 in August 2023, and the repository still has open issues and pull requests. We treat it as a library to test carefully, not as a default choice for new services.
7.3. Why is Book$ not found when compiling?
The annotation processor did not run. On JDK 23 and later, add -proc:full to the compiler arguments, or list the processor in annotationProcessorPaths, and rebuild so that target/generated-sources/annotations contains Book$.java.
7.4. Can JPAstreamer join entities?
Yes. A StreamConfiguration with joining(Book$.someAssociation) fetches an association in the same query, as described in the stream examples. We did not test joins on Hibernate 7.4, so they need the same testing as the predicates.
7.5. How do I update entities found with JPAstreamer?
The entities come from an EntityManager that JPAstreamer manages, so we change them inside a Spring @Transactional method and call EntityManager.merge(), or we load them by ID with Spring Data JPA and let dirty checking save the change. JPAstreamer itself only reads data.
8. Conclusion
JPAstreamer turns stream pipelines with metamodel predicates into SQL, so filter(), sorted(), skip(), limit() and count() run in the database, while lambdas and map() run in memory after the query.
Version 3.0.4 runs on Spring Boot 4.1.1 and Java 25 with two changes, a manually declared JPAStreamer bean and -proc:full for the metamodel. Equality predicates fail on Hibernate 7.4, and the last release is from 2023, so we test every query shape before using it and keep Spring Data JPA or the Criteria API as the default for long-lived services.
9. References
- JPAstreamer on GitHub
- JPAstreamer documentation
- jpastreamer-core on Maven Central
- Jakarta Persistence 3.2 specification
- Hibernate ORM 7 introduction
Happy Learning !!
