
Pagination in Hibernate means loading a large query result in small pieces, one page at a time, with setFirstResult() (how many rows to skip) and setMaxResults() (how many rows to return). Hibernate adds the paging clause of our database to the SQL, such as OFFSET … FETCH FIRST on H2.
We use pagination for every list that can grow, for example a job board that shows 5 job postings per screen instead of all 10,000. A second count query tells the UI how many pages exist, and for large or fast-changing tables, keyset pagination continues after the last row instead of counting rows to skip.
The following example maps a JobPosting entity and loads page 2 of 5 postings, newest first, together with the total count.
@Entity
public class JobPosting {

  @Id
  @GeneratedValue(strategy = GenerationType.IDENTITY)
  private Long id;

  private String title;
  private String city;
  private LocalDate postedOn;
  private BigDecimal salary;
}
List<JobPosting> page2 = em.createQuery("from JobPosting p order by p.postedOn desc, p.id desc", JobPosting.class)
.setFirstResult(5) // skip the 5 rows of page 1
.setMaxResults(5) // return at most 5 rows
.getResultList(); // [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst]
// select ... from JobPosting jp1_0 order by jp1_0.postedOn desc,jp1_0.id desc offset ? rows fetch first ? rows only
long total = em.createQuery("select count(p) from JobPosting p", Long.class)
.getSingleResult(); // 12, so 3 pages of 5
// select count(jp1_0.id) from JobPosting jp1_0Notice that the order by ends with p.id, so every posting has one fixed position, and the count of 12 rows gives us 3 pages.
Next, we compare offset and keyset pagination and see why the sort order must be unique. After that, we use Hibernate’s KeyedPage for keyset pages and page Criteria and join fetch queries. The last example streams a large result with ScrollableResults.
1. Offset vs Keyset Pagination
Hibernate supports two ways to find the rows of a page. Offset pagination counts rows, so for page 3 it skips the first 10 rows and returns the next 5. Keyset pagination (also called key-based or cursor pagination) remembers the sort values of the last row on the previous page and asks for the rows that come after them, with a where condition.
The database does very different work for the two. With an OFFSET, it still reads and sorts the skipped rows and then drops them. With a key, an index on the sort columns lets it start reading right after the last row we showed.
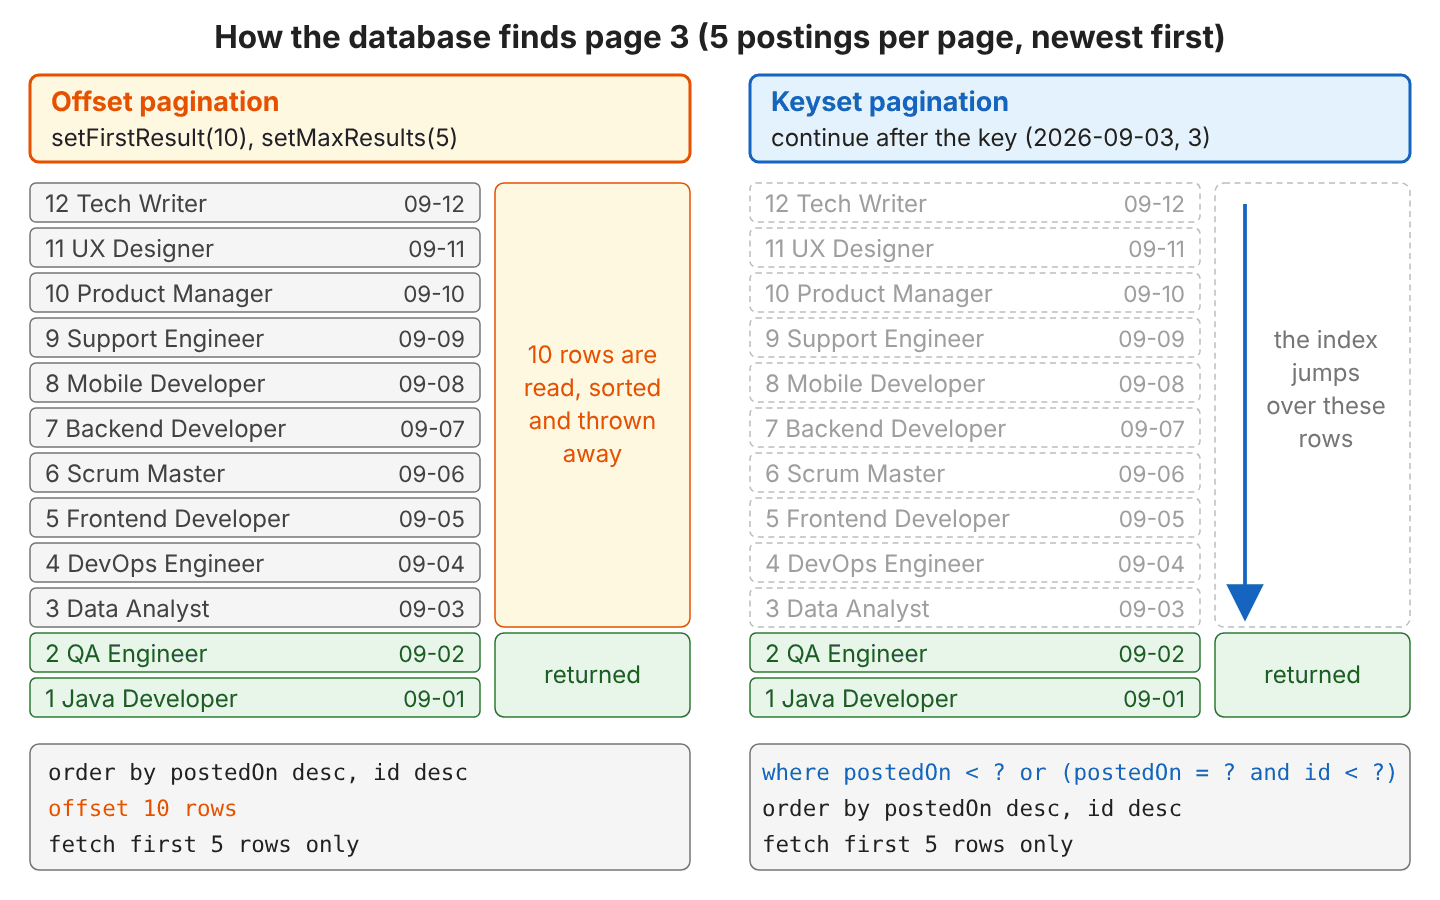
Neither style is always better. Offset pagination supports page numbers, whereas keyset pagination stays fast and correct on large tables that change.
| Question | Offset pagination | Keyset pagination |
|---|---|---|
| Hibernate API | setFirstResult(), setMaxResults(), Page | where on the last key, or KeyedPage and KeyedResultList |
| SQL on H2 | offset ? rows fetch first ? rows only | where postedOn<? or … fetch first ? rows only |
| Jump to page 7 | Yes | No, only next and previous |
| Rows the database reads for a deep page | All skipped rows plus the page | Only the page, with an index on the key |
| A row is added between two requests | Rows shift: one row shows twice | The next page starts after the last row seen |
| Sort requirement | A unique order, so add the id | The key columns are the sort order and must be unique together |
| Good fit | Page-number screens, admin tables, small tables | Infinite scroll, “Load more” buttons, REST APIs, exports |
2. Hibernate Pagination Example
The following example is a job board with Hibernate 7.4.11, Java 25 and an in-memory H2 database. The complete project on GitHub runs every query and prints the SQL, and its 19 JUnit tests check each result (mvn compile exec:java, mvn test).
2.1. The Job Board Model
A Company publishes many JobPosting rows. We use the @OneToMany collection only in the join fetch section, and every other query pages the postings themselves.
@Entity
public class JobPosting {

  @Id
  @GeneratedValue(strategy = GenerationType.IDENTITY)
  private Long id;

  private String title;
  private String city;
  private LocalDate postedOn;
  private BigDecimal salary;

  @ManyToOne(fetch = FetchType.LAZY)
  @JoinColumn(name = "company_id")
  private Company company;
}
@Entity
public class Company {
@Id
@GeneratedValue(strategy = GenerationType.IDENTITY)
private Long id;
private String name;
@OneToMany(mappedBy = "company")
private List<JobPosting> postings = new ArrayList<>();
}The test data has 12 postings, one per day from September 1, 2026, so the id and the LocalDate postedOn grow together. Each city and each company has 4 postings.
| id | title | city | postedOn | salary | company |
|---|---|---|---|---|---|
| 1 | Java Developer | Austin | 2026-09-01 | 95000 | Acme |
| 2 | QA Engineer | Berlin | 2026-09-02 | 70000 | Bluebird |
| 3 | Data Analyst | Pune | 2026-09-03 | 60000 | Cedar |
| 4 | DevOps Engineer | Austin | 2026-09-04 | 105000 | Acme |
| 5 | Frontend Developer | Berlin | 2026-09-05 | 80000 | Bluebird |
| 6 | Scrum Master | Pune | 2026-09-06 | 75000 | Cedar |
| 7 | Backend Developer | Austin | 2026-09-07 | 98000 | Acme |
| 8 | Mobile Developer | Berlin | 2026-09-08 | 85000 | Bluebird |
| 9 | Support Engineer | Pune | 2026-09-09 | 50000 | Cedar |
| 10 | Product Manager | Austin | 2026-09-10 | 110000 | Acme |
| 11 | UX Designer | Berlin | 2026-09-11 | 72000 | Bluebird |
| 12 | Tech Writer | Pune | 2026-09-12 | 55000 | Cedar |
2.2. Fetching a Page With setFirstResult() and setMaxResults()
Screens count pages from 1, but setFirstResult() takes a row position that starts at 0. The offset of a page is (pageNumber – 1) * pageSize, so page 1 starts at row 0 and page 3 at row 10.
public static List<JobPosting> findPage(EntityManager em, int pageNumber, int pageSize) {
  return em.createQuery("from JobPosting p order by p.postedOn desc, p.id desc", JobPosting.class)
      .setFirstResult((pageNumber - 1) * pageSize)
      .setMaxResults(pageSize)
      .getResultList();
}
List<JobPosting> page1 = findPage(em, 1, 5); // [Tech Writer, UX Designer, Product Manager, Support Engineer, Mobile Developer]
List<JobPosting> page2 = findPage(em, 2, 5); // [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst]
List<JobPosting> page3 = findPage(em, 3, 5); // [QA Engineer, Java Developer]
List<JobPosting> page4 = findPage(em, 4, 5); // [] (no error after the last page)Hibernate sends the same SQL for every page and binds the offset and the page size as parameters.
select jp1_0.id,jp1_0.city,jp1_0.company_id,jp1_0.postedOn,jp1_0.salary,jp1_0.title
from JobPosting jp1_0
order by jp1_0.postedOn desc,jp1_0.id desc
offset ? rows fetch first ? rows only
Hibernate takes the paging syntax from the database dialect, so the same Java code works on every database.
Hibernate also has its own Page class. We pass it to setPage() on a Hibernate SelectionQuery, which we get by unwrapping the Session. The page number of Page.page(size, number) starts at 0, so Page.page(5, 1) is the second page.
List<JobPosting> second = em.unwrap(Session.class)
    .createSelectionQuery("from JobPosting p order by p.postedOn desc, p.id desc", JobPosting.class)
    .setPage(Page.page(5, 1))
    .getResultList();   // [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst]
2.3. Counting the Total Pages
A pager that shows “Page 2 of 3” needs the number of rows. We get it with a count query, one of the aggregate functions of JPQL, and divide it by the page size, rounding up.
public record PageResult<T>(List<T> content, int pageNumber, int pageSize, long totalElements) {

  public int totalPages() {
    return (int) Math.ceilDiv(totalElements, (long) pageSize);
  }

  public boolean hasNext() {
    return pageNumber < totalPages();
  }
}

long total = em.createQuery("select count(p) from JobPosting p", Long.class)
    .getSingleResult();                                         // 12
PageResult<JobPosting> page = new PageResult<>(findPage(em, 2, 5), 2, 5, total);

int pages = page.totalPages();                                  // 3
boolean next = page.hasNext();                                  // true
The count query must use the same where clause as the page query, otherwise the page count is wrong. Hibernate’s getResultCount() builds the count from the page query itself, so the filter is always the same. It also drops the order by, which a count does not need.
long berlin = em.unwrap(Session.class)
    .createSelectionQuery("from JobPosting p where p.city = :city order by p.postedOn desc", JobPosting.class)
    .setParameter("city", "Berlin")
    .getResultCount();   // 4
// select count(*) from JobPosting jp1_0 where jp1_0.city=?
2.4. Why the Sort Order Must Be Unique
SQL does not promise any row order without an order by, and Hibernate does not add one for us, so from JobPosting p with setFirstResult(5) sends SQL that has the offset and fetch first clauses but no order by. An order by on a column with duplicate values is not enough either. Four postings share each city, and the database may return those four in a different order for every page request.
List<JobPosting> byCity = em.createQuery("from JobPosting p order by p.city", JobPosting.class)
    .setFirstResult((pageNumber - 1) * pageSize)
    .setMaxResults(pageSize)
    .getResultList();
page 1 = [Product Manager, Backend Developer, DevOps Engineer, Java Developer, UX Designer]
page 2 = [UX Designer, Frontend Developer, QA Engineer, Tech Writer, Scrum Master]
page 3 = [Scrum Master, Support Engineer]UX Designer and Scrum Master appear twice, and two postings never appear. On H2, about 9 of 10 runs of the three page queries go wrong, each time with a different mix.
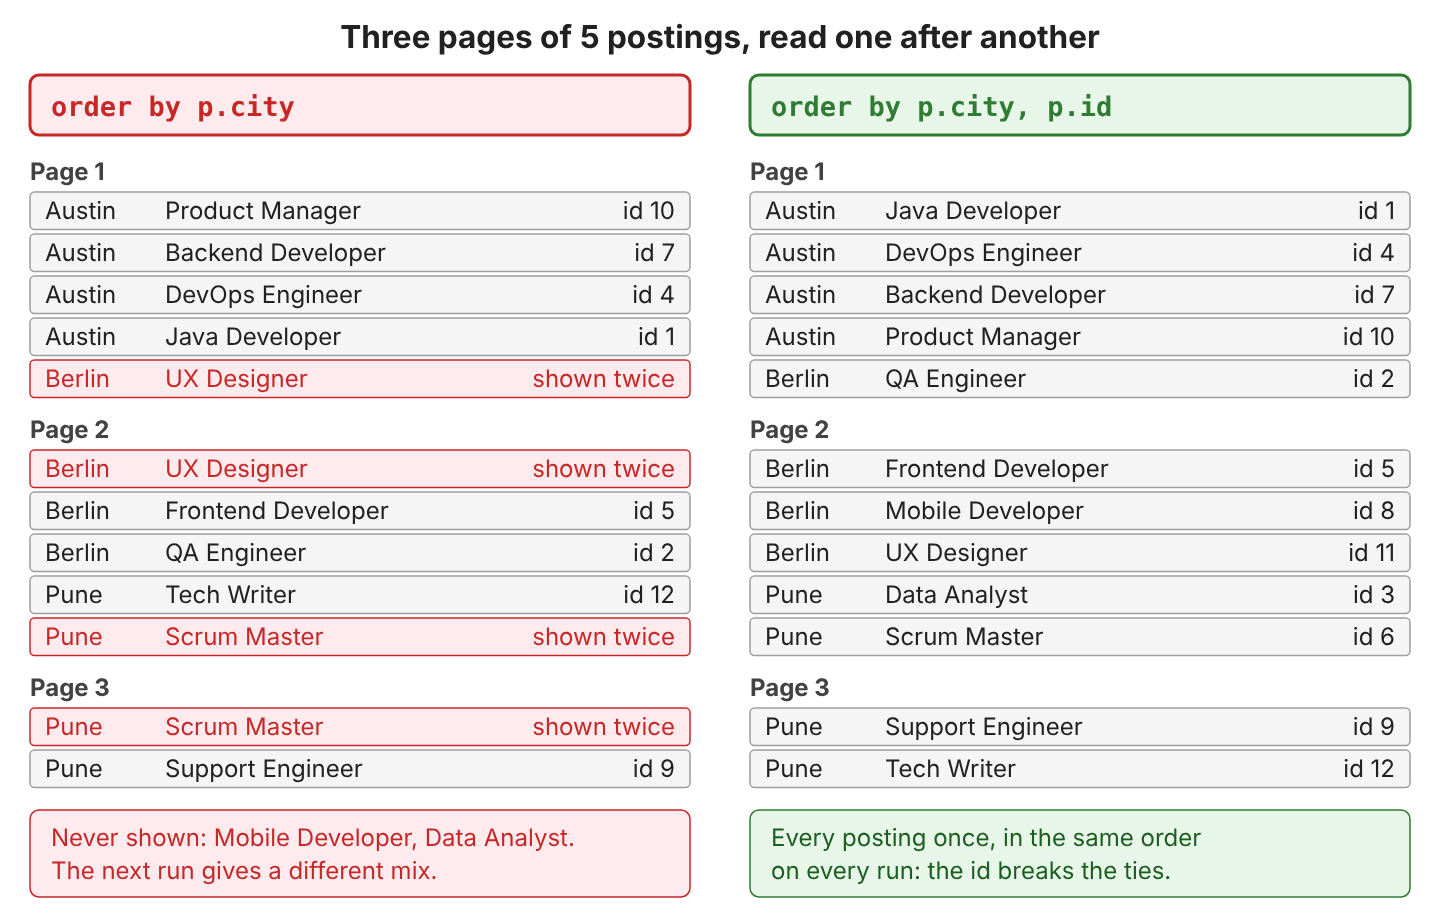
The fix is to add a unique column, such as the id, as the last sort column.
TypedQuery<JobPosting> query = em.createQuery("from JobPosting p order by p.city, p.id", JobPosting.class); // same 12 postings, each once, every runThe unique-order rule also applies to user-selected sorting, so when the reader sorts by salary or city, we append the id to the order by.
2.5. What Happens When a Row Is Added Between Pages
Offset pagination remembers a row count, not a row. When a company publishes a new posting after a reader loaded page 1, every older posting moves one position down, and page 2 starts with the last posting of page 1.
List<JobPosting> page1 = findPage(em, 1, 5);   // [Tech Writer, UX Designer, Product Manager, Support Engineer, Mobile Developer]

em.persist(new JobPosting("Java Architect", "Austin", LocalDate.of(2026, 9, 13), new BigDecimal("120000")));

List<JobPosting> page2 = findPage(em, 2, 5);   // [Mobile Developer, Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer]
The reader sees Mobile Developer twice. A deleted row causes the opposite problem. When we delete Tech Writer after page 1, page 2 starts with Scrum Master, and the reader never sees Backend Developer. Keyset pagination avoids both, because the next page starts after a key, not after a row count.
2.6. Keyset Pagination With a WHERE Clause
For keyset pagination, we sort by a unique key and ask for the rows after the last key the reader saw. With the id as the key and newest first, page 1 is a plain query with setMaxResults(), and every later page adds where p.id < :lastId.
public static List<JobPosting> findNextById(EntityManager em, Long lastId, int pageSize) {
  if (lastId == null) {
    return em.createQuery("from JobPosting p order by p.id desc", JobPosting.class)
        .setMaxResults(pageSize)
        .getResultList();
  }
  return em.createQuery("from JobPosting p where p.id < :lastId order by p.id desc", JobPosting.class)
      .setParameter("lastId", lastId)
      .setMaxResults(pageSize)
      .getResultList();
}
List<JobPosting> first = findNextById(em, null, 5); // [Tech Writer, ..., Mobile Developer]
Long lastId = first.getLast().getId(); // 8
List<JobPosting> next = findNextById(em, lastId, 5); // [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst]
// select ... from JobPosting jp1_0 where jp1_0.id<? order by jp1_0.id desc fetch first ? rows onlyThe client sends lastId back with the next request, for example as ?after=8 in a REST API. There is no offset in the SQL, so the database does not read the earlier pages again; with an index on the key column (the primary key always has one), it starts reading right after lastId.
2.7. Keyset Pagination With KeyedPage and KeyedResultList
When the key has more than one column, such as postedOn plus id, the where clause gets longer. Hibernate 6.5 and later build it for us with KeyedPage and getKeyedResultList(). We describe the sort order with Order objects, and Hibernate adds the order by and the where condition.
KeyedPage<JobPosting> firstPage = Page.first(5).keyedBy(List.of(
    Order.desc(JobPosting.class, "postedOn"),
    Order.desc(JobPosting.class, "id")));

Session session = em.unwrap(Session.class);
KeyedResultList<JobPosting> first = session
    .createSelectionQuery("from JobPosting p", JobPosting.class)
    .getKeyedResultList(firstPage);

List<JobPosting> rows1 = first.getResultList();             // [Tech Writer, UX Designer, Product Manager, Support Engineer, Mobile Developer]
List<Comparable<?>> key = first.getNextPage().getKey();     // [2026-09-08, 8]

KeyedResultList<JobPosting> second = session
    .createSelectionQuery("from JobPosting p", JobPosting.class)
    .getKeyedResultList(first.getNextPage());
List<JobPosting> rows2 = second.getResultList();            // [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst]
select jp1_0.id,jp1_0.city,jp1_0.company_id,jp1_0.postedOn,jp1_0.salary,jp1_0.title
from JobPosting jp1_0
where jp1_0.postedOn<? or jp1_0.id<? and jp1_0.postedOn=?
order by 4 desc,1 desc
fetch first ? rows onlyThe query string has no order by, because keyedBy() defines it (4 and 1 are the positions of postedOn and id in the select list). A KeyedResultList also tells us the position of the page in the whole result.
| Method | Returns | Page 3 in our data |
|---|---|---|
| getResultList() | The rows of this page | [QA Engineer, Java Developer] |
| getNextPage() | A KeyedPage that starts after the last row | null |
| getPreviousPage() | A KeyedPage that ends before the first row | The page before |
| isLastPage() / isFirstPage() | Whether more rows exist | true / false |
| getKeyList() | The key of every row | [[2026-09-02, 2], [2026-09-01, 1]] |
We repeat the experiment from section 2.5 with keyed pages. After we save the new Java Architect posting, the second keyed page is still [Backend Developer, Scrum Master, Frontend Developer, DevOps Engineer, Data Analyst], with no duplicate.
2.8. Paging a Criteria Query
A Criteria query builds the JPQL in Java code, which suits search screens with optional filters. Paging works the same way, on the TypedQuery that em.createQuery(criteria) returns.
CriteriaBuilder cb = em.getCriteriaBuilder();
CriteriaQuery<JobPosting> query = cb.createQuery(JobPosting.class);
Root<JobPosting> posting = query.from(JobPosting.class);
query.select(posting)
    .where(cb.equal(posting.get("city"), city))
    .orderBy(cb.desc(posting.get("postedOn")), cb.desc(posting.get("id")));

List<JobPosting> austin = em.createQuery(query)
    .setFirstResult((pageNumber - 1) * pageSize)
    .setMaxResults(pageSize)
    .getResultList();   // page 1 of 3 for "Austin": [Product Manager, Backend Developer, DevOps Engineer]
// select ... from JobPosting jp1_0 where jp1_0.city=? order by jp1_0.postedOn desc,jp1_0.id desc offset ? rows fetch first ? rows only
The count query for the same filter uses cb.count().
CriteriaQuery<Long> count = cb.createQuery(Long.class);
Root<JobPosting> root = count.from(JobPosting.class);
count.select(cb.count(root)).where(cb.equal(root.get("city"), city));

long austinTotal = em.createQuery(count).getSingleResult();   // 4
// select count(jp1_0.id) from JobPosting jp1_0 where jp1_0.city=?
Hibernate 6 removed the legacy session.createCriteria() API with its own setFirstResult(), and Hibernate 7.4 has no org.hibernate.Criteria class, so the CriteriaBuilder API replaces it.
2.9. Paging a join fetch Query
A join fetch loads an entity together with its collection in one query, which avoids lazy loading one collection at a time. Paging a join fetch query is harder than it looks. The SQL join returns one row per posting, not one row per company, so a plain fetch first 2 rows would return Acme with only 2 of its 4 postings. Hibernate never cuts a collection this way.
List<Company> page = em.createQuery("select c from Company c join fetch c.postings order by c.name", Company.class)
    .setFirstResult(0)
    .setMaxResults(2)
    .getResultList();   // [Acme, Bluebird], 4 postings each
What Hibernate does instead depends on the version and the database.
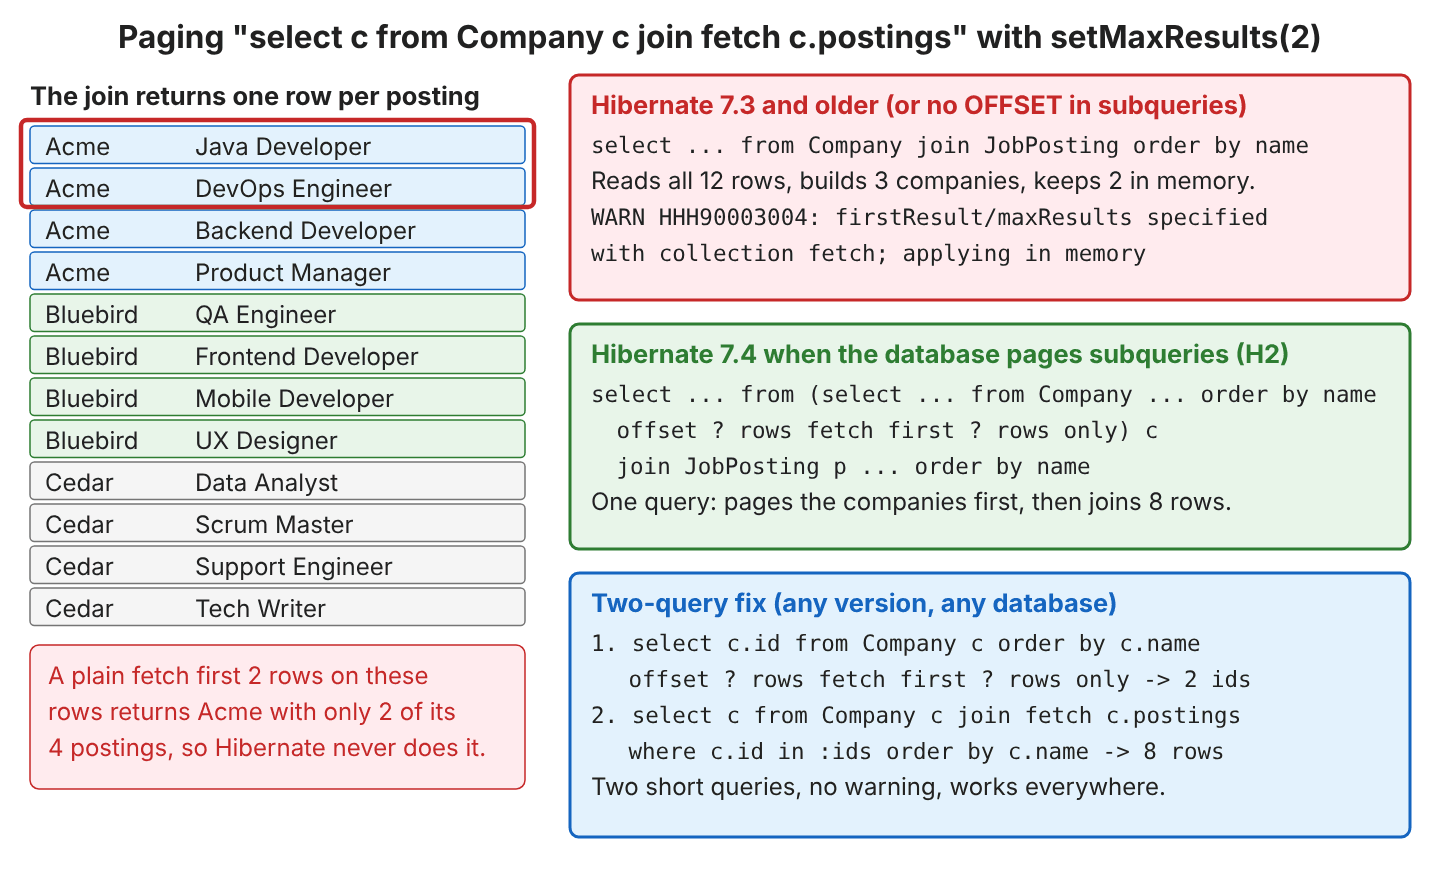
Hibernate 7.4 pages the companies in a subquery and joins the postings to that page, on databases that allow OFFSET inside a subquery, such as H2.
select c1_0.id,c1_0.name,p1_0.company_id,p1_0.id,p1_0.city,p1_0.postedOn,p1_0.salary,p1_0.title
from (select c1_0.id,c1_0.name from Company c1_0
      where exists(select 1 from JobPosting p1_0 where c1_0.id=p1_0.company_id)
      order by c1_0.name offset ? rows fetch first ? rows only) c1_0(id,name)
join JobPosting p1_0 on c1_0.id=p1_0.company_id
order by c1_0.name
Hibernate 7.3 and older, and Hibernate 7.4 on a database without that feature (Sybase ASE, for example), read every row and page in memory. The SQL has no offset or fetch at all, and Hibernate logs a warning.
WARN org.hibernate.orm.query - HHH90003004: firstResult/maxResults specified with collection fetch; applying in memory
Hibernate: select c1_0.id,c1_0.name,p1_0.company_id,p1_0.id,p1_0.city,p1_0.postedOn,p1_0.salary,p1_0.title from Company c1_0 join JobPosting p1_0 on c1_0.id=p1_0.company_id order by c1_0.name
With 3 companies, nobody notices. With 50,000 companies, every page request loads all of them and their postings into memory. Hibernate 5 logged the same text as HHH000104: firstResult/maxResults specified with collection fetch; applying in memory!. To catch it in tests, we turn the warning into an exception.
hibernate.query.fail_on_pagination_over_collection_fetch=trueorg.hibernate.HibernateException: setFirstResult() or setMaxResults() specified with collection fetch join (in-memory pagination was about to be applied, but 'hibernate.query.fail_on_pagination_over_collection_fetch' is enabled)The fix that works on every version and database uses two queries. The first one pages the ids, and the second one fetches the companies and their postings for those ids only.
List<Long> ids = em.createQuery("select c.id from Company c order by c.name", Long.class)
    .setFirstResult((pageNumber - 1) * pageSize)
    .setMaxResults(pageSize)
    .getResultList();   // 2 ids
// select c1_0.id from Company c1_0 order by c1_0.name offset ? rows fetch first ? rows only

List<Company> companies = em.createQuery(
        "select c from Company c join fetch c.postings where c.id in :ids order by c.name", Company.class)
    .setParameter("ids", ids)
    .getResultList();   // [Acme, Bluebird], 4 postings each
// select ... from Company c1_0 join JobPosting p1_0 on c1_0.id=p1_0.company_id where c1_0.id in (?,?) order by c1_0.name
The second query repeats the order by, because in (?,?) does not keep the order of the id list.
2.10. Streaming Large Results With ScrollableResults
Sometimes we need every row, for a CSV export or a nightly report, but not all of them in memory at once. A ScrollableResults keeps the JDBC ResultSet open and gives us one entity at a time. We call em.clear() every few hundred rows, because the persistence context keeps a reference to every entity it loaded.
BigDecimal total = BigDecimal.ZERO;
int count = 0;
try (ScrollableResults<JobPosting> postings = em.unwrap(Session.class)
    .createSelectionQuery("from JobPosting p order by p.id", JobPosting.class)
    .setFetchSize(100)
    .scroll(ScrollMode.FORWARD_ONLY)) {
  while (postings.next()) {
    total = total.add(postings.get().getSalary());
    if (++count % 100 == 0) {
      em.clear();   // free the entities we already processed
    }
  }
}
// total = 955000.00
// select ... from JobPosting jp1_0 order by jp1_0.id   (one query, no offset)
Jakarta Persistence offers the same with getResultStream(). We close the stream with try-with-resources, because it also holds the ResultSet open.
try (Stream<JobPosting> postings = em.createQuery("from JobPosting p order by p.id", JobPosting.class)
    .getResultStream()) {
  BigDecimal sum = postings.map(JobPosting::getSalary).reduce(BigDecimal.ZERO, BigDecimal::add);   // 955000.00
}
The method setFetchSize() is a hint to the JDBC driver about how many rows to read per round trip. For writing many rows in chunks, batch processing uses the same clear() pattern.
3. Hibernate Pagination FAQs
3.1. Is the First Page 0 or 1?
It depends on the method. Mixing them up causes an off-by-one-page bug, for example a pager whose page 1 skips the first five postings.
| API | Counts from | First page of 5 |
|---|---|---|
| setFirstResult(int) | Row 0 | setFirstResult(0) |
| Hibernate Page.page(size, number) | Page 0 | Page.page(5, 0) or Page.first(5) |
| Our findPage(em, pageNumber, pageSize) | Page 1 | findPage(em, 1, 5) |
3.2. Can I Write LIMIT and OFFSET in HQL?
Yes. HQL accepts limit, offset and fetch first in the query string, and Hibernate translates them into the database syntax, with the numbers written into the SQL.
List<JobPosting> limited = em.createQuery("from JobPosting p order by p.id limit 5 offset 5", JobPosting.class)
    .getResultList();   // [Scrum Master, Backend Developer, Mobile Developer, Support Engineer, Product Manager]
// select ... from JobPosting jp1_0 order by jp1_0.id offset 5 rows fetch first 5 rows only
For a page number that changes per request, setFirstResult() and setMaxResults() are simpler than building the query string or binding extra parameters.
3.3. Does setMaxResults() Work With Native SQL Queries?
Yes. Hibernate adds the paging clause to a native SQL query too, so we do not write it ourselves.
List<String> titles = em.createNativeQuery("select title from JobPosting order by id", String.class)
    .setFirstResult(5)
    .setMaxResults(5)
    .getResultList();   // [Scrum Master, Backend Developer, Mobile Developer, Support Engineer, Product Manager]
// select title from JobPosting order by id offset ? rows fetch next ? rows only
We still write the order by in the SQL string.
3.4. Should I Use ScrollableResults for Pagination?
No. A page query with setFirstResult() and setMaxResults() asks the database for 5 rows. A scroll query has no offset or fetch clause. It moves the cursor through the result set, and calling last() to count the rows walks to the end of it. We use ScrollableResults or getResultStream() to process every row once, and offset or keyset pagination to show pages to a reader.
3.5. Why Do Later Pages Get Slower?
Because the database must produce every skipped row before it can drop it. In PostgreSQL, for example, the rows skipped by an OFFSET clause still have to be computed inside the server, so a large OFFSET is slow. Page 2 skips 5 rows, page 2,000 skips 9,995. Keyset pagination with an index on the key columns reads only the rows of the page, which is why APIs with “load more” use it.
4. Conclusion
Offset pagination in Hibernate is two method calls, setFirstResult() and setMaxResults(), plus a count query (or getResultCount()) for the page numbers. It needs a unique sort order, so we always end the order by with the id. For large tables and data that changes between requests, keyset pagination with a where on the last key, or Hibernate’s KeyedPage, returns the next page without duplicates. Before paging a join fetch, we check the Hibernate version. Hibernate 7.4 pages the parent rows in a subquery, while older versions page in memory, which the two-query approach avoids.
5. References
- TypedQuery JavaDoc (Jakarta Persistence 3.2)
- Hibernate ORM 7.4 Introduction: Limits and pagination
- Hibernate ORM 7.4 Introduction: Key-based pagination
- Hibernate ORM 7.4 User Guide: Limits and offsets
- Hibernate ORM 7.4 User Guide: Scrollable result sets
- KeyedPage JavaDoc (Hibernate 7.4)
- PostgreSQL Documentation: LIMIT and OFFSET
Happy Learning !!
