
Hibernate save(), update() and saveOrUpdate() were the Session methods that inserted a new entity, reattached a detached entity, or chose between the two by looking at the id. Hibernate 6.0 deprecated all three, and Hibernate 7.0 removed them, so code that calls them no longer compiles. Their replacements are the two standard Jakarta Persistence methods, persist() for a new object and merge() for an object that already has a row.
We meet these methods when we upgrade an older app to Hibernate 7, where every save() or saveOrUpdate() call turns into a compile error.
The following example shows the Hibernate 7 calls for a Plant entity, with the old method names in the comments.
@Id
@GeneratedValue(strategy = GenerationType.IDENTITY)
private Long id;

private String name;
private String species;
private String potSize;
private double price;
em.persist(basil); // was save(basil)
// insert into Plant (name,potSize,price,species,id) values (?,?,?,?,default)
Long id = basil.getId(); // id = 2, the value save() used to return
Plant copy = em.merge(repotted); // was update(repotted)
// select p1_0.id,...,p1_0.species from Plant p1_0 where p1_0.id=?
// commit: update Plant set name=?,potSize=?,price=?,species=? where id=?
boolean same = copy == repotted; // false, keep using copy
Plant saved = PlantStore.save(em, aloe); // was saveOrUpdate(aloe): persist() if the id is null, else merge()Notice that merge() returns a different object than the one we pass, so we keep using copy.
Next, we run the old methods on Hibernate 6.6 to see what they did. After that, we run persist() and merge() on Hibernate 7.4 for the same cases.
1. What Did save(), update() and saveOrUpdate() Do?
Each method was made for an object in a particular state. Hibernate knows three entity states that matter here.
- A new (transient) object was created with new Plant(…), so it has no id and no row.
- A managed object is tracked by an open Session. Hibernate saves its changes at commit by comparing it with the values it loaded, which is called dirty checking.
- A detached object has an id and a row, but the Session that loaded it is closed. A plant that came back from a web form is a typical example.
The method save() was for new objects, update() for detached ones, and saveOrUpdate() for both. Running the old Session methods on Hibernate 6.6.58 with an IDENTITY id shows how each one treats a new or a detached object.
| save() | update() | saveOrUpdate() | |
|---|---|---|---|
| Meant for | A new object | A detached object | A new or a detached object |
| Returns | The generated id, as Object (here a Long) | void | void |
| The object we pass | Becomes managed | Becomes managed | Becomes managed |
| SQL | INSERT at the call | UPDATE at commit, even when nothing changed | INSERT at the call, or UPDATE at commit |
| Id is null | Inserts | TransientObjectException | Inserts |
| Detached object | Inserts a second row | Updates the row | Updates the row |
| Id that has no row | Ignores the id and inserts | OptimisticLockException at commit | OptimisticLockException at commit |
| Cascades along | CascadeType.SAVE_UPDATE | CascadeType.SAVE_UPDATE | CascadeType.SAVE_UPDATE |
The INSERT runs at the call because the id comes from an IDENTITY column, so Hibernate must insert the row to learn it. The method saveOrUpdate() decides by the id, where null means new and anything else means detached.
1.1. The Old Calls on Hibernate 6.6
The nursery table starts with one plant, Monstera with id 1. In each call, monstera is a detached copy of that row, loaded in an earlier session.
Object id = session.save(basil);      // insert into Plant (name,potSize,price,species,id) values (?,?,?,?,default)
                                      // id = 2, a Long

session.update(monstera);             // no SQL, monstera is managed again
                                      // commit: update Plant set name=?,potSize=?,price=?,species=? where id=?

session.saveOrUpdate(fern);           // id is null: insert into Plant ...
session.saveOrUpdate(monstera);       // id is set: no SQL, commit: update Plant ...
The update() call sends an UPDATE even though we changed nothing. The method update() never reads the row, so Hibernate cannot know whether the values differ and writes all columns.
1.2. save() on a Detached Plant Inserts a Second Row
The method save() treats every object as new. With a generated id, it ignores the id the object already has, inserts a new row and overwrites the id field with the new value.
Object id = session.save(monstera);   // insert into Plant (name,potSize,price,species,id) values (?,?,?,?,default)
                                      // id = 2, monstera.getId() = 2
After the call, the table holds the same plant twice. In a nursery catalog, an admin who edits the price of Monstera in a form ends up with two Monstera entries.
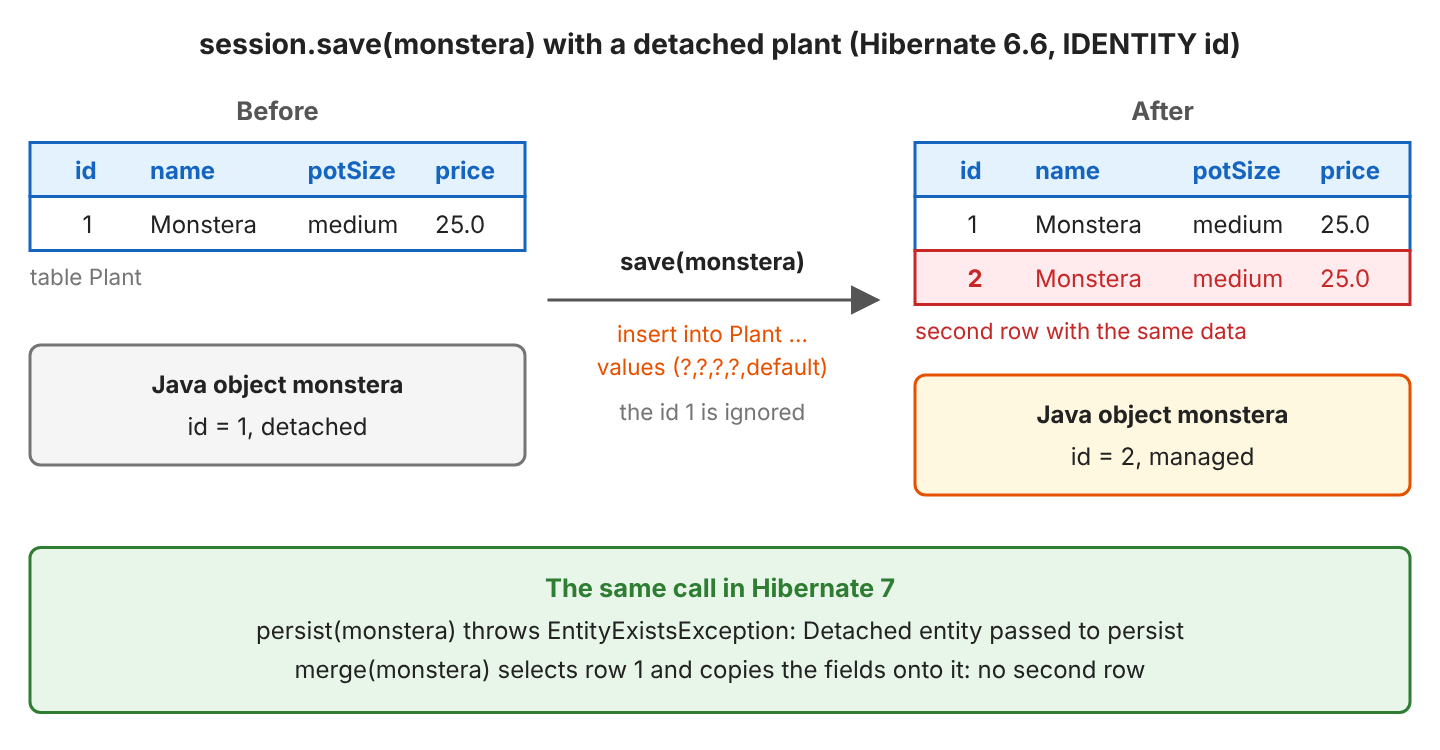
A plant whose id has no row at all, such as 99, gets the same treatment, so save() inserts it with the next id.
1.3. Errors From update() and saveOrUpdate()
The method update() attaches the object we pass, so it fails whenever Hibernate cannot attach it. Three cases come up in practice.
session.update(new Plant("Fern", ...));   // id is null: TransientObjectException

Plant loaded = session.get(Plant.class, 1L);
session.update(monstera);                 // a second object with id 1: NonUniqueObjectException

session.update(cactus);                   // id 99, no row: no SQL at the call
                                          // commit: OptimisticLockException
org.hibernate.TransientObjectException: The given object has a null identifier: com.howtodoinjava.hibernate.saveorupdate.legacy.Plant
org.hibernate.NonUniqueObjectException: A different object with the same identifier value was already associated with the session: [com.howtodoinjava.hibernate.saveorupdate.legacy.Plant#1]
jakarta.persistence.OptimisticLockException: Row was updated or deleted by another transaction (or unsaved-value mapping was incorrect): [com.howtodoinjava.hibernate.saveorupdate.legacy.Plant#99]The method saveOrUpdate() throws the last two in the same situations. The NonUniqueObjectException exists because a Session holds at most one object per id in its persistence context, the set of entities it tracks. The OptimisticLockException appears because the UPDATE changed zero rows.
2. Saving Plants With persist() and merge() in Hibernate 7
Hibernate 7.0 removed all forms of the three methods from Session. The Session interface in hibernate-core 7.4.11 has persist() and merge() and none of the old names, so an old call fails at compile time.
OldCall.java:7: error: cannot find symbol
    session.save(basil);
           ^
  symbol:   method save(Plant)
  location: variable session of type Session
Hibernate 7.0 also removed CascadeType.SAVE_UPDATE from org.hibernate.annotations, and its replacements are the JPA cascade types PERSIST and MERGE.
2.1. The Plant Nursery Example
The following example is a plant nursery app that runs on Hibernate 7.4.11, Java 25 and an in-memory H2 database. The Plant entity from the intro has an @Id with an IDENTITY generator and four plain columns. We create the EntityManagerFactory without a persistence.xml.
EntityManagerFactory emf = new HibernatePersistenceConfiguration("plant-nursery")
    .managedClasses(Plant.class)
    .jdbcUrl("jdbc:h2:mem:nursery;DB_CLOSE_DELAY=-1")
    .jdbcCredentials("sa", "")
    .schemaToolingAction(Action.CREATE_DROP)
    .createEntityManagerFactory();
Each case starts with one row, Monstera (medium pot, 25.0) with id 1. The comments show the SQL that Hibernate sent at the call and at commit.
2.2. Saving a New Plant
The method persist() replaces save(). It returns nothing, and the object we pass becomes managed and gets its id.
Plant basil = new Plant("Basil", "Ocimum basilicum", "small", 4.00);
em.persist(basil);                      // insert into Plant (name,potSize,price,species,id) values (?,?,?,?,default)
Long id = basil.getId();                // 2
boolean managed = em.contains(basil);   // true
The method merge() accepts a new object too, but it inserts a copy. The object we pass keeps a null id.
Plant fern = new Plant("Fern", "Nephrolepis exaltata", "medium", 9.00);
Plant copy = em.merge(fern);           // insert into Plant (name,potSize,price,species,id) values (?,?,?,?,default)
Long copyId = copy.getId();            // 2
Long fernId = fern.getId();            // null
boolean managed = em.contains(fern);   // false
For a new object we call persist(), so the object in our variable is the one Hibernate saves.
2.3. Saving a Detached Plant
The method merge() replaces update(). For example, a customer changed the pot size of Monstera in a form, and repotted is the detached plant with that change.
repotted.setPotSize("large");
Plant copy = em.merge(repotted);                   // select p1_0.id,p1_0.name,p1_0.potSize,p1_0.price,p1_0.species from Plant p1_0 where p1_0.id=?
boolean same = copy == repotted;                   // false
boolean repottedManaged = em.contains(repotted);   // false
boolean copyManaged = em.contains(copy);           // true
                                                   // commit: update Plant set name=?,potSize=?,price=?,species=? where id=?
The method merge() loads row 1, copies the fields of repotted onto the loaded object and returns it. Dirty checking then compares the copy with the row. When we merge a detached plant that has no change, the SELECT runs and the UPDATE does not, while the old update() wrote the row anyway.
Passing the detached plant to persist() fails at the call, before any SQL.
em.persist(monstera); // EntityExistsExceptionjakarta.persistence.EntityExistsException: Detached entity passed to persist: com.howtodoinjava.hibernate.saveorupdate.PlantThis exception is the Hibernate 7 answer to the duplicate row from section 1.2. Jakarta Persistence allows persist() to reject a detached object, and Hibernate does so as soon as the id of a generated-id entity is not null.
2.4. Saving a Plant That Is Already Managed
A plant loaded with find() in the same transaction needs no save call at all. Its setters are enough, and Hibernate ignores both methods.
Plant monstera = em.find(Plant.class, 1L);   // select ...
monstera.setPrice(27.00);
em.persist(monstera);                        // ignored, no SQL
Plant merged = em.merge(monstera);           // returns monstera itself, no SQL
                                             // commit: update Plant set name=?,potSize=?,price=?,species=? where id=?
When the transaction already holds row 1 and we merge a detached copy of it, merge() copies the fields onto the loaded object and returns it. There is no SELECT, and no NonUniqueObjectException as with update().
Plant loaded = em.find(Plant.class, 1L);
priced.setPrice(30.00);              // priced: detached copy of row 1
Plant copy = em.merge(priced);       // no SQL
boolean same = copy == loaded;       // true
double price = loaded.getPrice();    // 30.0
                                     // commit: update Plant set name=?,potSize=?,price=?,species=? where id=?
2.5. Saving a Plant With an Id That Has No Row
A cactus with the id 99 set by hand looks detached to Hibernate, because its id is not null. Neither method inserts it.
em.persist(cactus);                // EntityExistsException: Detached entity passed to persist: ...Plant

Plant merged = em.merge(cactus);   // select ... where p1_0.id=?  (sent twice)
                                   // OptimisticLockException at the call
jakarta.persistence.OptimisticLockException: Row was already updated or deleted by another transaction for entity [com.howtodoinjava.hibernate.saveorupdate.Plant with id '99']The old save() inserted this plant under a new id, and update() failed only at commit. With a generated id, a new plant must reach Hibernate with a null id, for example by not copying the id from a request body into a new entity.
3. persist() vs merge()
The two methods differ in which object ends up managed. The method persist() puts our object into the persistence context, whereas merge() leaves our object outside and returns another one.
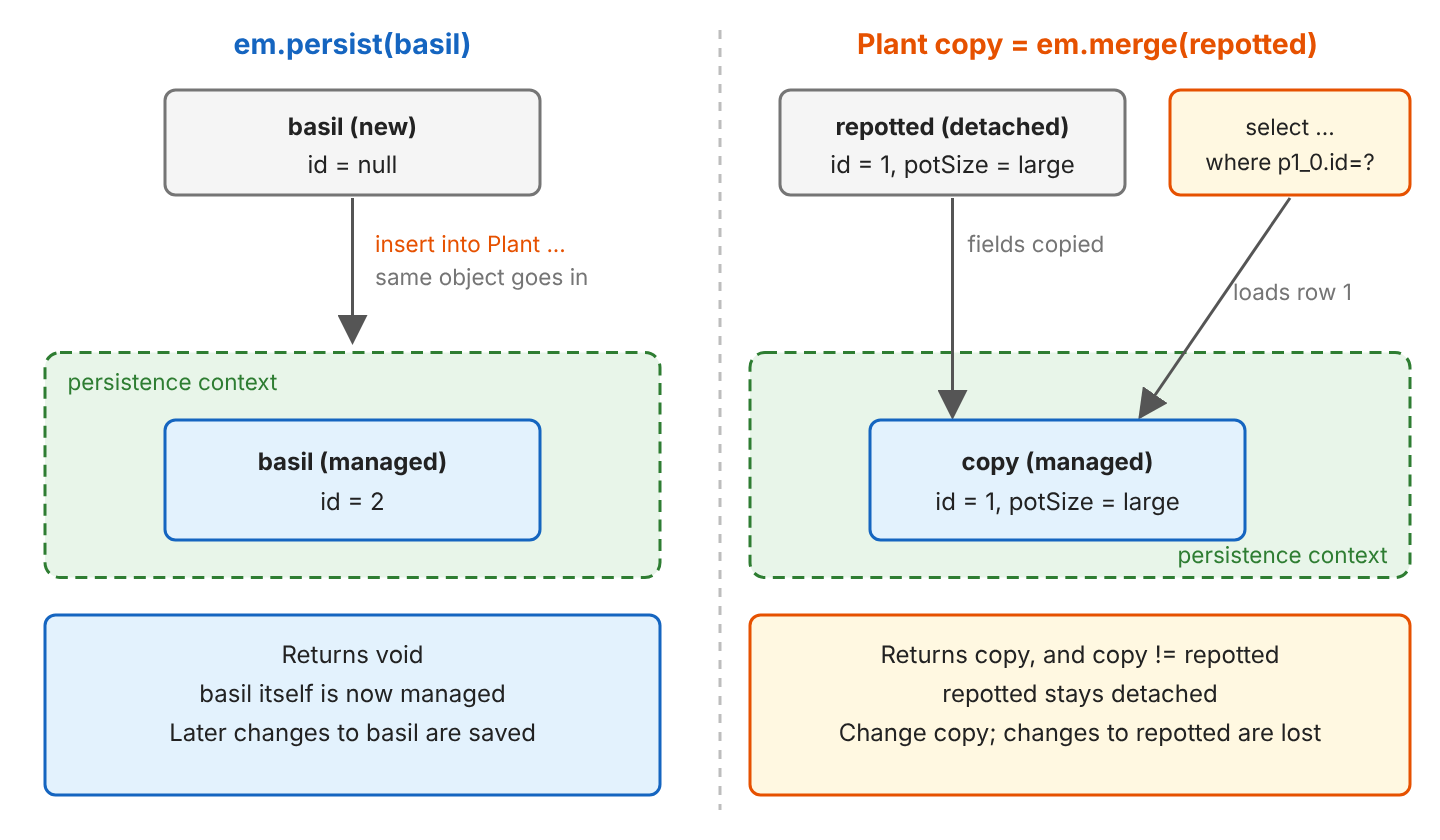
Which object ends up managed explains every other row of the comparison.
| persist() | merge() | |
|---|---|---|
| Returns | void | The managed instance |
| New plant (id null) | Inserts this object | Inserts a copy; our object keeps id null |
| Detached plant | EntityExistsException | SELECT, then UPDATE at commit if a field changed |
| Managed plant | Ignored | Returns the same object, no SQL |
| Id with no row | EntityExistsException | OptimisticLockException |
| Cascades along | CascadeType.PERSIST | CascadeType.MERGE |
| Replaces | save() | update() |
After merge(), we continue with the returned object. A change to the argument after the call is lost, while a change to the copy is saved.
emf.runInTransaction(em -> {
  Plant copy = em.merge(plant);
  plant.setPrice(99.00);          // lost: plant is not managed
  copy.setPotSize("large");       // saved at commit
});
// row 1: price = 25.0, potSize = large
4. Migrating From save(), update() and saveOrUpdate()
Most old calls have a one-line replacement. The one to watch is update(), because the variable has to take the returned object.
| Hibernate 5 and 6 | Hibernate 7 |
|---|---|
| Object id = session.save(plant); | session.persist(plant); then plant.getId() |
| session.update(plant); | plant = session.merge(plant); |
| session.saveOrUpdate(plant); | persist() for a new plant, merge() for a detached one |
| session.update(plant) on a plant loaded in the same session | Nothing; dirty checking saves it |
| session.delete(plant); | session.remove(plant); |
| @Cascade(CascadeType.SAVE_UPDATE) | cascade = {CascadeType.PERSIST, CascadeType.MERGE} |
The method session.delete() was removed in the same release, and remove() replaces it. When code holds a SessionFactory and Session instead of an EntityManager, the same persist() and merge() methods are on Session.
Which call to write depends on the state of the plant, and the same two questions decide every case.
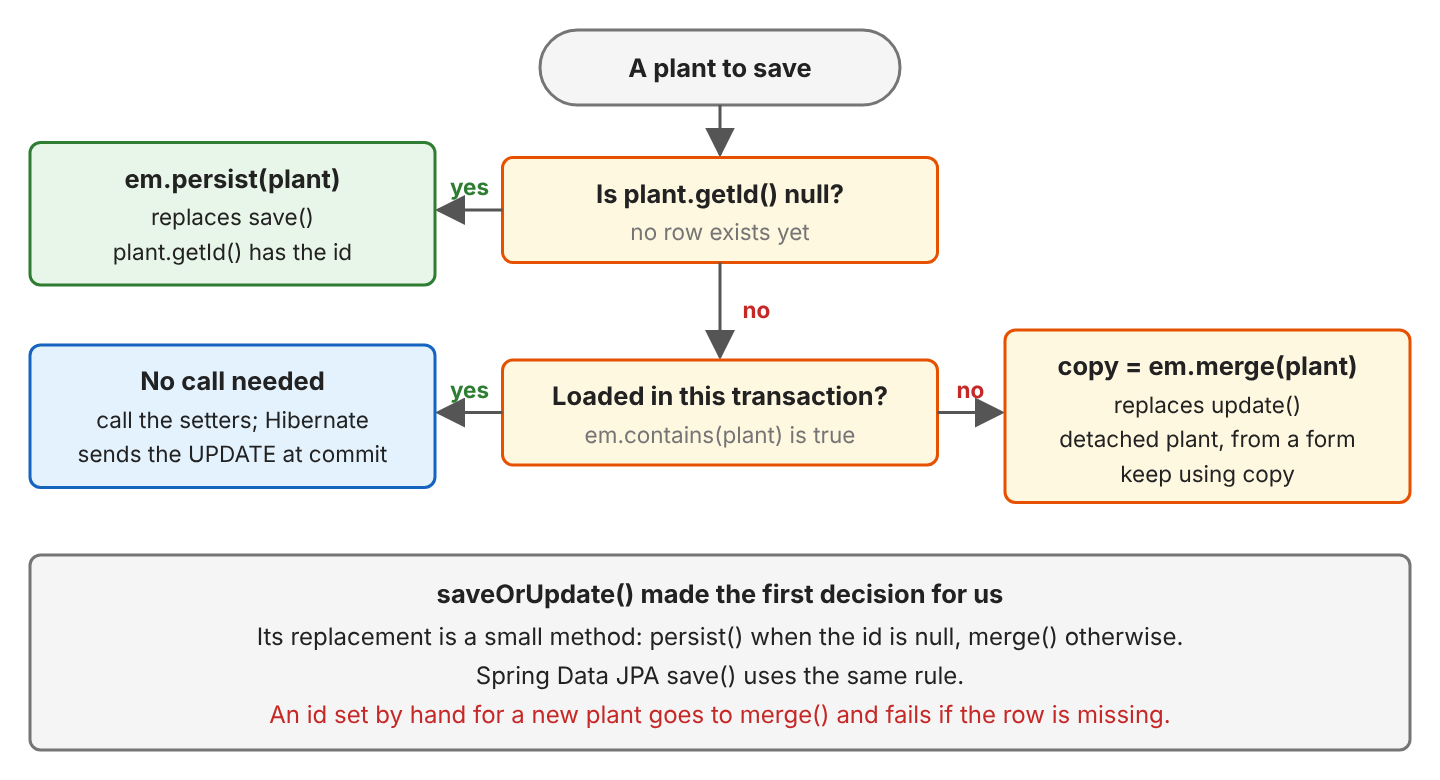
The method saveOrUpdate() has no single replacement, so we write the first question as a small method. It follows the same rule as Spring Data’s save().
public static Plant save(EntityManager em, Plant plant) {
  if (plant.getId() == null) {
    em.persist(plant);
    return plant;
  }
  return em.merge(plant);
}
Plant saved = PlantStore.save(em, aloe); // id is null: insert into Plant ..., saved == aloe
aloe.setPrice(8.00); // aloe is detached after that transaction
saved = PlantStore.save(em, aloe); // id is set: select ... where p1_0.id=?, saved != aloe
// commit: update Plant set name=?,potSize=?,price=?,species=? where id=?The method returns the managed object in both branches, so callers always continue with the result.
The complete project on GitHub contains the Hibernate 7 cases with 13 JUnit tests. Its hibernate6-legacy folder is a separate Maven project on Hibernate 6.6.58 that runs the old methods from section 1 with 15 tests (mvn -q compile exec:java, mvn test in each folder).
5. save(), update() and saveOrUpdate() FAQs
5.1. What Is the Difference Between save() and persist()?
Both inserted a new object, and persist() is the one that still exists. The other differences come from their origin, because save() was Hibernate’s own method, whereas persist() comes from Jakarta Persistence.
| save() (removed in 7.0) | persist() | |
|---|---|---|
| Returns | The id | void; read plant.getId() |
| Detached object | Inserts a duplicate row | EntityExistsException |
| Id with no row | Inserts under a new id | EntityExistsException |
| Defined by | Hibernate Session | EntityManager and Session |
With an IDENTITY id, both send the INSERT at the call.
5.2. What Is the Difference Between update() and merge()?
The method update() attached the object we passed, whereas merge() attaches a copy and returns it.
| update() (removed in 7.0) | merge() | |
|---|---|---|
| Returns | void | The managed copy |
| Our object afterwards | Managed | Still detached |
| SQL for an unchanged plant | UPDATE at commit | SELECT only |
| Same id already loaded | NonUniqueObjectException | Copies onto the loaded object |
| New object (id null) | TransientObjectException | Inserts a copy |
| Id with no row | OptimisticLockException at commit | OptimisticLockException at the call |
The common bug after migrating is a line like session.merge(plant); that ignores the result, followed by more changes to plant, so those changes are lost.
5.3. What Replaces saveOrUpdate() in Spring Data JPA?
The method CrudRepository.save() plays that role. The Spring Data JPA 4.1 implementation in SimpleJpaRepository calls persist() for a new entity and merge() for any other.
if (entityInformation.isNew(entity)) {
  entityManager.persist(entity);
  return entity;
}
return entityManager.merge(entity);
By default an entity is new when its non-primitive @Version field is null, or, without such a field, when its id is null. Always use the entity that save() returns, because for an existing entity it is the copy from merge().
5.4. Does merge() Always Run a SELECT?
No, merge() reads the row only when the persistence context does not hold that id yet.
| Situation | SQL at the merge() call |
|---|---|
| Detached plant, id 1 not loaded | One SELECT |
| Detached plant, id 1 already loaded with find() | None |
| Managed plant | None |
| New plant (id null) | INSERT (with IDENTITY) |
6. Conclusion
The methods save(), update() and saveOrUpdate() are gone in Hibernate 7, and the replacements behave more safely. The method persist() saves a new object and rejects a detached one instead of inserting a duplicate row. Its counterpart merge() saves a detached object by copying it onto a managed instance, which we must use afterwards, and a managed entity needs no call at all. For saveOrUpdate(), a small method that picks persist() or merge() by the id does the same job, as Spring Data’s save() does.
7. References
- Hibernate ORM 7.0 Migration Guide: Session#save, Session#update, Session#saveOrUpdate
- Session JavaDoc (Hibernate ORM 6.6)
- Session JavaDoc (Hibernate ORM 7.4)
- Hibernate ORM 7.4 User Guide: Making entities persistent
- Hibernate ORM 7.4 User Guide: Merging detached data
- Jakarta Persistence 3.2 specification: Persisting an Entity Instance
- EntityManager JavaDoc (Jakarta Persistence 3.2)
- Spring Data JPA: Saving Entities
Happy Learning !!

awesome , conceptually explained so well.
Dear Sir,
While submitting the web form entitymanager.merge() is inserting data instead of updating.Why is it happening.
Regards
Vinay
In Clusterred environment, we have 2 nodes. I have a job which runs on clustered env. Situation is , when this cron job started, using its status whether it is PENDING or InProgress , node will pick that job and start it.
Node picks up the job on basis of status ie. if Status is PENDING then job will start by respective node. So here to avoid , job to be picked up by both the node, before start the job we, updated the status from Pending to In Progress.
In current code, we first update Status=IN Progress and start the process but this change doesn’t get committed to DB till whole transaction gets completed and in between that 2nd node picks this job again and starts working on it.
This situation puts job into deadlock.
Is there any way in Hibernate Transaction where i can commit status before complete the transaction so other node can understand that this job is already in progress with first node.?
Hi Deepak, I am not aware of any such technique in hibernate. Though I have faced similar problem in one of projects, but we were using iBatis there so the solution does not apply here.
Session session = sessionFactory.openSession();
Transaction tx = session.beginTransaction();

for ( int i=0; i<100000; i++ ) {
    Customer customer = new Customer(.....);
    session.save(customer);
    if ( i % 20 == 0 ) { //20, same as the JDBC batch size
        //flush a batch of inserts and release memory:
        session.flush();
        session.clear();
    }
}

tx.commit();
session.close();
In this example, for every 20 records data will be flushed i.e. data will be persisted in the database, if any record thrown error while processing any record after flush what will happen? as per the transaction concept whole activity i.e. saving 1000000 records should be rollback , but we already saved first 20 records in the database. How Transaction concept will work this scenario? please explain me in understanding session.flush vs tx.commit when we use together .
Well, you are right in your understanding. Ultimately, it all boils down to fact how you want to handle the error.
I will put the code inside for-loop in a try-catch block, if any error is received I will try again to run that 20 statements, if succeeded – move ahead to next set of 20; if not then simply log them somewhere and continue processing next set of 20 records.
Hi Satish,
You can also used try catch block. As Lokesh suggest. If you want to continue you can do something in catch block( mean get the index number where it stop and start again).
If you want to stop execution and you want those 20 record should not be in database you can rollback the transaction in catch block.
Thanks,
Bhargav
2.SaveOrUpdate() calls either save() or update() on the basis of identifier exists or not. e.g if identifier does not exist, save() will be called or else update() will be called
I am confused as ID is given when we save so it should not be vice- versa.
i.e if identifier does not exist, update() will be called or else save() will be called ?
ID is given when we save – but only if it does not exist already. If it exist, then duplicate key exception will be thrown.
I didn’t understand the contents of “Suggestion For Production Code” section. In this section you are telling to pass VO object instead of calling session.save() or session.saveOrUpdate(). What is the meaning of VO object here. we generally use saveOrUpdate() method. What’s wrong in using it explicitly. What’s the benefit of using VO object???
Probably in your application, VO and entities are same objects. In that case, your argument is valid.
If both are different objects, then I “suggested” the way. How you guys do it?
We use AbstractDao layer or baseDao you can say. And we write DAO classes extending this abstract dao class. So all I understand that it removes boiler plate code. And after all we define these generic methods like saveOrupdate(), delete, findById(). So that we don’t have to write these methods in every DAO class. But I don’t know what you mean here using VO object. What is this term VO. Could you please elaborate it.
VO = View Objects; which you pass to your view layer. These are generally separate than DTO (or entities in this case) objects. You fetch data onto DTO, copy to VO and then return VO to controller. Controller passes VO to view later. Generally happen like this.
Keeping DTO and VO separate helps in evolving view layer and data layer independently.
Yes, I think you are telling that sometime DTO objects are exactly as same as entity class and sometime some of the fields of DTO are different from entity class. For example One DTO or VO may contain data from two entity classes and we process it in service layer I mean transfer the values to entity object so that we can save or update in database. I don’t know if I understood the same what you meant or not. But what ever you are telling sounds good. Could you please provide some link or example where I can see this scenario implemented. I mean I can practically understand the benefit of using VO object. Thanks :-)
You got it right. Please note that what I call View Object, is called Domain Object [DO] as well by many others. If you search for “DO vs DTO”, you will find many good links.
In short, most notifiable difference between them is that DO can have some view related business logic i.e. formatting field or validating it; whereas DTOs contain only setter and getter methods (well mostly).
How to issue insert all in hibernate if i want to suppose insert 100 records into database at once.
It depends on what you want to do. e.g. If you want to store 100 entities with all associated/managed entities then you can use session.flush() after every 100 save() calls. But if you are inserting purely raw data using hibernate without any dependency then StatelessSession could be a good choice.
Consider I am reading 100 records from CSV file of employee details. I need to insert all at once by generating my own sequence generator. How the process works from view upto dao implementation ?. Should I first construct 100 employee entities and call save on each entity and session.flush().
Yes. You are right. You can do something like this: https://docs.jboss.org/hibernate/orm/3.3/reference/en/html/batch.html#batch-inserts