

Kafka Streams is a client library for building applications that read records from Kafka topics, process them and write the results back to Kafka topics. Spring for Apache Kafka integrates the library with Spring Boot through the annotation @EnableKafkaStreams, the class StreamsBuilderFactoryBean and the class KafkaStreamsConfiguration. In this Apache Kafka tutorial, we configure a Kafka Streams application with Spring Boot, build a stream processing pipeline that counts orders per product and write tests for it.
1. Introduction to Kafka Streams
The Kafka Streams library enriches data with operations such as data transformation, data aggregation and joining data from multiple Kafka topics. Kafka Streams uses functional programming techniques, like lambda expressions, mapping, filtering, and flatMap, which are common in modern Java code.
Kafka Streams supports stateless and stateful operations, so we can maintain and update state while processing streams. Stateful processing is useful for complex event processing and for correlating data across different streams. For example, we can calculate the real-time total number of orders, the total revenue or the total number of tickets sold.
Kafka Streams provides a high-level DSL (Domain-Specific Language) and a low-level Processor API. The DSL offers a declarative approach, whereas the Processor API gives fine-grained control and allows custom logic.
2. What is a Processor Topology?
The processor topology represents the structure of the stream processing application. A processor topology defines how the input data streams are read, transformed, processed and produced. It consists of a directed acyclic graph (DAG) of processing nodes, where each node represents a processing step. The topology defines the flow of data and the relationships between different processing stages.
Kafka Streams has three types of processors, as the diagram shows.
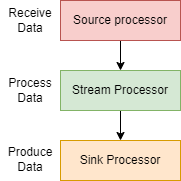
Source processors receive data from one or more Kafka topics and deserialize it before forwarding the records to the stream processor node, which contains the main transformation or computation logic. A sink processor writes the processed data to one or more output Kafka topics or to a state store.
3. Setting up Kafka Streams in Spring Boot Application
3.1. Maven
To use Kafka Streams with the Spring Boot application we add spring-kafka and kafka-streams dependency.
<dependency>
        <groupId>org.springframework.kafka</groupId>
        <artifactId>spring-kafka</artifactId>
</dependency>
<dependency>
        <groupId>org.apache.kafka</groupId>
        <artifactId>kafka-streams</artifactId>
</dependency>
We also need spring-kafka-test, kafka-streams-test-utils and awaitility dependencies for writing unit and integration tests.
<dependency>
        <groupId>org.springframework.kafka</groupId>
        <artifactId>spring-kafka-test</artifactId>
</dependency>
<dependency>
        <groupId>org.apache.kafka</groupId>
        <artifactId>kafka-streams-test-utils</artifactId>
</dependency>
<dependency>
        <groupId>org.awaitility</groupId>
        <artifactId>awaitility</artifactId>
</dependency>
3.2. Configuration
The annotation @EnableKafkaStreams enables the default components of Kafka Streams. When we use it, Spring imports the default configuration class KafkaStreamsDefaultConfiguration, which registers a StreamsBuilderFactoryBean using the class KafkaStreamsConfiguration.
@Configuration
@EnableKafkaStreams
public class StreamsConfig {

}
The KafkaStreamsConfiguration connects to the bootstrap servers that the property spring.kafka.streams.bootstrap-servers specifies. We also specify the application-id, which acts as the consumer group name for the stream.
spring:
  kafka:
    streams:
      bootstrap-servers: localhost:9092
      application-id: order-streams-app
4. Kafka Streams in Action
4.1. Prerequisites
The following docker-compose.yml file creates a single-node Kafka server with one ZooKeeper instance and one broker instance. The configuration also makes the ZooKeeper server start before the Kafka server (broker) and stop after it.
For a more resilient Kafka setup, we can use the docker cluster configuration using Docker Compose. We can change the configuration to match our requirements.
---
version: '3.6'
services:
  zookeeper:
    image: confluentinc/cp-zookeeper:latest
    platform: linux/amd64
    hostname: zookeeper
    container_name: zookeeper
    ports:
      - "2181:2181"
    environment:
      ZOOKEEPER_CLIENT_PORT: 2181
      ZOOKEEPER_TICK_TIME: 2000

  broker:
    image: confluentinc/cp-server:latest
    platform: linux/amd64
    hostname: broker
    container_name: broker
    depends_on:
      - zookeeper
    ports:
      - "9092:9092"
      - "9101:9101"
    environment:
      KAFKA_BROKER_ID: 1
      KAFKA_ZOOKEEPER_CONNECT: 'zookeeper:2181'
      KAFKA_LISTENER_SECURITY_PROTOCOL_MAP: PLAINTEXT:PLAINTEXT,PLAINTEXT_HOST:PLAINTEXT
      KAFKA_ADVERTISED_LISTENERS: PLAINTEXT://broker:29092,PLAINTEXT_HOST://localhost:9092
      KAFKA_METRIC_REPORTERS: io.confluent.metrics.reporter.ConfluentMetricsReporter
      KAFKA_OFFSETS_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_GROUP_INITIAL_REBALANCE_DELAY_MS: 0
      KAFKA_CONFLUENT_LICENSE_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_CONFLUENT_BALANCER_TOPIC_REPLICATION_FACTOR: 1
      KAFKA_TRANSACTION_STATE_LOG_MIN_ISR: 1
      KAFKA_TRANSACTION_STATE_LOG_REPLICATION_FACTOR: 1
      KAFKA_JMX_PORT: 9101
      KAFKA_JMX_HOSTNAME: localhost
      CONFLUENT_METRICS_REPORTER_BOOTSTRAP_SERVERS: broker:29092
      CONFLUENT_METRICS_REPORTER_TOPIC_REPLICAS: 1
      CONFLUENT_METRICS_ENABLE: 'true'
      CONFLUENT_SUPPORT_CUSTOMER_ID: 'anonymous'
4.2. Topology Design
Spring Boot offers a lightweight abstraction over the Streams API and manages the lifecycle of our KStream instance. Spring creates and configures the components that the topology needs and runs our Streams application, so we can concentrate on the business logic.
The following topology counts the total number of orders sold for a given product.
Our example uses the high-level DSL to define the transformations.
- We create a KStream from the input topic using the specified key and value SerDes. Apache Kafka provides the interface Serde, which wraps the serializer and the deserializer of a data type, and it has implementations for common data types such as String, Long and Json. Our code uses String and Json Serdes for the key and the value respectively.
- We use selectKey(..) to set a new key for each input record. The methods print(..) and Printed(..) then print the KStream data in the logs with the specified label.
- We create a KTable by transforming, grouping and counting the data.
- We produce the result to an output stream (a Kafka topic).
@Component
@Slf4j
public class OrdersTopology {

	@Autowired
	public void process(StreamsBuilder streamsBuilder) {

	  KStream<String, Order> orderStreams = streamsBuilder
	    .stream(ORDERS,
	            Consumed.with(Serdes.String(), new JsonSerde<>(Order.class))
	    )
	    .selectKey((key, value) -> value.productId());

	  orderStreams
	    .print(Printed.<String, Order>toSysOut().withLabel("orders"));

	  KTable<String, Long> ordersCount =  ordersStream
	    .map((key, order) -> KeyValue.pair(order.productId(), order))
	    .groupByKey(Grouped.with(Serdes.String(), new JsonSerde<>(Order.class)))
	    .count(Named.as(OrdersTopology.ORDERS_COUNT));

	  ordersCount
	    .toStream()
	    .print(Printed.<String,Long>toSysOut().withLabel(OrdersTopology.ORDERS_COUNT));

	  ordersCount
	    .toStream()
	    .to(ORDERS_OUTPUT, Produced.with(Serdes.String(), Serdes.Long()));
	}

	//...
}
The annotation @Autowired on the method injects a matching bean from the container into the StreamsBuilder parameter.
4.3. State Store
Instead of publishing the data to an output Kafka topic, we can materialize the result into a StateStore, which allows us to query the data without writing a consumer for the output topic. We can either provide a custom StateStore or use the default RocksDB by providing a store name.
RocksDB is an embedded state store, so writes do not need a network call. This removes network latency, and the store does not become a bottleneck or a point of failure in the stream processing. It is a key/value store that persists records as their byte representation, which gives fast reads and writes. It is a persistent state store rather than an in-memory one, and it flushes writes to disk asynchronously.
In our example, RocksDB stores the result. We modify the KTable from earlier and materialize the aggregated order count as a local state store.
@Autowired
public void process(StreamsBuilder streamsBuilder) {

         //...

        KTable<String, Long> ordersCount =  ordersStream
                .map((key, order) -> KeyValue.pair(order.productId(), order))
                .groupByKey(Grouped.with(Serdes.String(), new JsonSerde<>(Order.class)))
                .count(Named.as(OrdersTopology.ORDERS_COUNT),

                        Materialized.as(OrdersTopology.ORDERS_COUNT)
                );

       //...
}
With StateStore, we can write a REST API that fetches the data from the store.
@Autowired
 private StreamsBuilderFactoryBean streamsBuilderFactoryBean;

@GetMapping("/count")
public List<OrdersCountPerStoreDTO> ordersCount() {

        ReadOnlyKeyValueStore<String, Long> ordersStoreData = streamsBuilderFactoryBean.getKafkaStreams()
                .store(StoreQueryParameters.fromNameAndType(
                        ORDERS_COUNT,
                        QueryableStoreTypes.keyValueStore()
                ));

        var orders = ordersStoreData.all();

        var spliterator = Spliterators.spliteratorUnknownSize(orders, 0);

        return StreamSupport.stream(spliterator, false)
                .map(data -> new OrdersCountPerStoreDTO(data.key, data.value))
                .collect(Collectors.toList());
}
In the controller, we autowire the StreamsBuilderFactoryBean, which gives us access to the KafkaStreams instance that the factory bean manages. We use KafkaStreams to fetch the results from the ORDERS_COUNT key/value state store, which the KTable represents.
5. Testing
5.1. Unit Test
We write a unit test for our topology using the TopologyTestDriver, a class that verifies the behavior of topologies created with StreamsBuilder.
We instantiate StreamsBuilder and use it to create a bean of OrdersTopology, which has our business logic. We then instantiate the TopologyTestDriver by providing a topology (StreamsBuilder.build()) and use the driver to create an input topic for testing.
class OrdersTopologyTest {

    TopologyTestDriver topologyTestDriver = null;
    TestInputTopic<String, Order> ordersInputTopic = null;

    static String INPUT_TOPIC = ORDERS;
    StreamsBuilder streamsBuilder;

    OrdersTopology ordersTopology = new OrdersTopology();

    @BeforeEach
    void setUp() {
        streamsBuilder = new StreamsBuilder();
        ordersTopology.process(streamsBuilder);
        topologyTestDriver = new TopologyTestDriver(streamsBuilder.build());

        ordersInputTopic =
                topologyTestDriver.
                        createInputTopic(
                                INPUT_TOPIC, Serdes.String().serializer(),
                                new JsonSerde<Order>(Order.class).serializer());


    }

    @AfterEach
    void tearDown() {
        topologyTestDriver.close();
    }

    @Test
    void ordersCount() {

        ordersInputTopic.pipeKeyValueList(orders());

        ReadOnlyKeyValueStore<String, Long> OrdersCountStore = topologyTestDriver.getKeyValueStore(ORDERS_COUNT);

        var product1234OrdersCount = OrdersCountStore.get("product_1234");
        assertEquals(2, product1234OrdersCount);

        var product4567OrdersCount = OrdersCountStore.get("product_4567");
        assertEquals(2, product4567OrdersCount);

    }

    static List<KeyValue<String, Order>> orders(){

          // create some orders
    }

}
5.2. Integration Test
We use EmbeddedKafka and TestPropertySource to set up the environment for the integration test. We also use Awaitility to test asynchronous code.
@SpringBootTest
@EmbeddedKafka(topics = {ORDERS})
@TestPropertySource(properties = {
        "spring.kafka.streams.bootstrap-servers=${spring.embedded.kafka.brokers}",
        "spring.kafka.producer.bootstrap-servers=${spring.embedded.kafka.brokers}"
 ,"spring.kafka.streams.auto-startup=false"
})
@DirtiesContext(classMode = DirtiesContext.ClassMode.AFTER_EACH_TEST_METHOD)
public class OrdersTopologyIntegrationTest {

    @Autowired
    KafkaTemplate<String, String> kafkaTemplate;

    @Autowired
    StreamsBuilderFactoryBean streamsBuilderFactoryBean;
    @Autowired
    ObjectMapper objectMapper;

    @Autowired
    OrderService orderService;

    @BeforeEach
    public void setUp() {
        streamsBuilderFactoryBean.start();
    }

    @AfterEach
    public void destroy() {
        streamsBuilderFactoryBean.getKafkaStreams().close();
        streamsBuilderFactoryBean.getKafkaStreams().cleanUp();
    }

    @Test
    void ordersCount() {
        publishOrders();

        Awaitility.await().atMost(10, SECONDS)
                .pollDelay(Duration.ofSeconds(1))
                .ignoreExceptions()
                .until(() -> orderService.ordersCount().size(), equalTo(1));

        var ordersCount = orderService.ordersCount();
        assertEquals(1, ordersCount.get(0).count());

    }

    private void publishOrders() {
        orders()
                .forEach(order -> {
                    String orderJSON = null;
                    try {
                        orderJSON = objectMapper.writeValueAsString(order.value);
                    } catch (JsonProcessingException e) {
                        throw new RuntimeException(e);
                    }
                    kafkaTemplate.send(ORDERS, order.key, orderJSON);
                });
    }


    static List<KeyValue<String, Order>> orders() {


          // create some orders
    }


}
6. Conclusion
Kafka Streams processes records from Kafka topics with a processor topology that consists of source, stream and sink processors. In a Spring Boot application, the annotation @EnableKafkaStreams and the class StreamsBuilderFactoryBean set up the library, and the DSL defines the topology. A state store makes the aggregated results available to a REST API, and TopologyTestDriver and EmbeddedKafka cover unit and integration tests.
Happy Learning !!

You might the only one to share working/complete/brief example to the kafka example . Others tutorial like ‘hiding/abstract’ many things . They just explain the main thing and don’t bother to give us example. So THANK YOU!