
pgvector adds vector storage and similarity search to PostgreSQL. Spring AI’s PgVectorStore uses it to persist document text, metadata, and embeddings, then retrieve documents related to a query.
For an application that already uses PostgreSQL, this can avoid operating another database service. It still requires the extension, suitable schema and permissions, an embedding model, and an index configured for the chosen vector type.
This example runs PostgreSQL with pgvector in Docker, connects the existing OrderDesk ingestion and search code, and inspects the stored rows. The troubleshooting sections explain dimension mismatches and how the selected index constrains vector size.
1. What pgvector Adds to PostgreSQL
An embedding is an array of numbers (a float[] in Java) that stands for the meaning of a text. Texts with a similar meaning get arrays that sit close to each other.
The pgvector extension adds three things:
- The vector(n) column type, which holds exactly n numbers. Our embedding model returns 768, so the column is vector(768).
- Distance operators. <=> gives the cosine distance, which Spring AI uses for text. pgvector also has <-> (Euclidean distance) and <#> (inner product).
- Two index types for fast search: HNSW and IVFFlat (see FAQ 6.2).
The cosine distance is 0 for two arrays that point the same way, and it grows as the texts differ. Spring AI reports a score instead, which is 1 minus the distance. So a higher score means a closer match.
Spring AI’s PgVectorStore implements the VectorStore interface on top of this. Its add() method inserts rows, similaritySearch() runs a SELECT ordered by distance, and delete() removes rows. The other columns of the table hold the text and the metadata (extra key-value pairs such as topic = returns) as JSON.
2. The Example App
This article is part of the OrderDesk series. OrderDesk is the support assistant of a demo online store, and the full app is on GitHub in the orderdesk folder. It runs on Spring Boot 4.1.1, Spring AI 2.0.1, and Java 21, with Ollama 0.40.6.
The basic setup (installing Ollama, the Spring Boot project, the Spring AI BOM, and the Ollama starter) is explained in Getting Started with Spring AI. Make sure Ollama is running. You also need Docker (a tool that runs packaged applications in containers) for the database.
2.1. The Embedding Model
We use nomic-embed-text in Ollama as the embedding model. It returns 768 numbers for each text. Let’s download it and name it in application.properties:
ollama pull nomic-embed-text# Embedding model for RAG (ollama pull nomic-embed-text)
spring.ai.ollama.embedding.options.model=nomic-embed-textThe Ollama starter creates the EmbeddingModel bean (an object that Spring creates and hands to every class that asks for it) from this property. PgVectorStore calls it to embed each document and each question.
2.2. The Policy Files and the Code That Loads Them
OrderDesk’s knowledge lives in four Markdown files in src/main/resources/policies: returns.md, shipping.md, warranty.md, and payments.md. Each “##” heading and the text under it is one section. The four files have 16 sections in total. This is returns.md:
# Returns and Refunds

## Return window

You can return most items within 10 days of delivery. The item must be unused and in its original box with all tags.

## Damaged or wrong items

If an item arrives damaged or is not what you ordered, report it within 48 hours of delivery. Upload a photo of the item and the parcel on the order page. We send a replacement or give a full refund, and you do not pay for the return pickup.

## Items you cannot return

- Earphones and headphones once the seal is opened
- Groceries and other perishable items
- Gift cards

## Refunds

Refunds go back to the original payment method within 5 to 7 working days after we receive the item. If you choose store credit instead, it is added to your OrderDesk wallet at once.
This article adds no Java code. It reuses these files from earlier articles, which you can copy from GitHub:
- PolicyIngestion.java reads the policy files, makes one Document per section and saves them in the VectorStore. Explained in Spring AI ETL Pipeline Example for Data Ingestion.
- IngestController.java maps POST /ingest to PolicyIngestion. It returns the number of files, sections and chunks, and the time in milliseconds. Explained in the same ETL article.
- SimpleVectorStoreConfig.java creates OrderDesk’s default in-memory store. It is off with the pgvector profile, but PolicyIngestion refers to it, so copy it too. Explained in Spring AI VectorStore Example: SimpleVectorStore and ChromaDB.
- The policies folder with all four Markdown files.
A Document is Spring AI’s class for one piece of text with its metadata. PolicyIngestion gives each section a topic (the file name without “.md”) and a source (the file name). Its last part writes to the store. Here files is the array of the four policy files, and chunks is the list of Document objects made from them:
// Load: remove the old chunks of each file, then add the new ones
for (Resource file : files) {
    String topic = file.getFilename().replace(".md", "");
    vectorStore.delete("topic == '" + topic + "'");
}
vectorStore.add(chunks);
The loader removes sections associated with each controlled source topic before adding replacements. This prevents duplicate copies in the example, but deletion and reloading are separate operations: plan for partial failures if the pipeline must remain continuously available.
2.3. The Search Endpoint
PolicySearchController handles the search. It turns the request parameters into a SearchRequest:
package com.howtodoinjava.orderdesk.vectorstore;

import java.util.List;

import org.springframework.ai.document.Document;
import org.springframework.ai.vectorstore.SearchRequest;
import org.springframework.ai.vectorstore.VectorStore;
import org.springframework.ai.vectorstore.filter.FilterExpressionBuilder;
import org.springframework.web.bind.annotation.GetMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;

@RestController
public class PolicySearchController {

    private final VectorStore vectorStore;

    PolicySearchController(VectorStore vectorStore) {
        this.vectorStore = vectorStore;
    }

    @GetMapping("/search")
    List<SearchHit> search(@RequestParam String query,
                           @RequestParam(defaultValue = "3") int topK,
                           @RequestParam(defaultValue = "0.0") double threshold,
                           @RequestParam(required = false) String topic) {

        SearchRequest.Builder request = SearchRequest.builder()
            .query(query)
            .topK(topK)
            .similarityThreshold(threshold);
        if (topic != null) {
            // the builder treats topic as a value, never as part of the expression
            request.filterExpression(new FilterExpressionBuilder().eq("topic", topic).build());
        }

        List<Document> documents = vectorStore.similaritySearch(request.build());
        return documents.stream()
            .map(d -> new SearchHit(
                Math.round(d.getScore() * 1000) / 1000.0,
                String.valueOf(d.getMetadata().get("topic")),
                d.getText()))
            .toList();
    }

    record SearchHit(double score, String topic, String text) {
    }
}
topK caps the number of returned documents, and the threshold removes candidates below the configured score. FilterExpressionBuilder treats the topic parameter as a value rather than executable filter syntax. Authorization to search a topic is a separate application check.
Both classes use only the VectorStore interface, so moving to pgvector changes no Java code.
3. Configure PostgreSQL and the Vector Store
We start Postgres in Docker, add two dependencies and a profile file, and then load and search the policies.
Step 1: Start PostgreSQL with pgvector in Docker
The pgvector project’s Docker image builds on PostgreSQL and includes the extension files. It is distinct from the plain official postgres image. The following command starts the example database:
docker run -d --name pgvector -p 5432:5432 -e POSTGRES_USER=orderdesk -e POSTGRES_PASSWORD=orderdesk -e POSTGRES_DB=orderdesk pgvector/pgvector:pg17The three -e options create a user, its password, and a database, all named orderdesk. The -p option publishes Postgres’s port 5432 on our computer. The tag pg17 means PostgreSQL 17 (pgvector 0.8.7 in our run).
If you already have PostgreSQL, you can install the extension in it instead. Spring AI runs CREATE EXTENSION IF NOT EXISTS vector for us, but the extension’s files must be installed on the database server first.
Step 2: Add the Starter and the Driver
We add two dependencies to pom.xml. The Spring AI BOM and Spring Boot set their versions:
<dependency>
  <groupId>org.springframework.ai</groupId>
  <artifactId>spring-ai-starter-vector-store-pgvector</artifactId>
</dependency>
<dependency>
  <groupId>org.postgresql</groupId>
  <artifactId>postgresql</artifactId>
  <scope>runtime</scope>
</dependency>
The starter brings PgVectorStore and its auto-configuration. It also brings Spring’s JDBC support (JDBC is Java’s standard API for relational databases). The postgresql driver is the JDBC driver that talks to the server. It has the runtime scope, because our code never calls it directly.
Step 3: Configure the Datasource and the Store
Now we add the settings. OrderDesk keeps them in a Spring profile, a named set of properties that we turn on at startup. The file is src/main/resources/application-pgvector.properties:
# docker run -d --name pgvector -p 5432:5432 -e POSTGRES_USER=orderdesk -e POSTGRES_PASSWORD=orderdesk -e POSTGRES_DB=orderdesk pgvector/pgvector:pg17
spring.datasource.url=jdbc:postgresql://localhost:5432/orderdesk
spring.datasource.username=orderdesk
spring.datasource.password=orderdesk

spring.ai.vectorstore.type=pgvector
spring.ai.vectorstore.pgvector.initialize-schema=true
spring.ai.vectorstore.pgvector.dimensions=768
spring.ai.vectorstore.pgvector.distance-type=COSINE_DISTANCE
spring.ai.vectorstore.pgvector.index-type=HNSW
Line by line:
- The three spring.datasource lines are Spring Boot’s normal database settings. PgVectorStore uses the app’s main DataSource, the object that hands out database connections.
- spring.ai.vectorstore.type=pgvector turns on the pgvector auto-configuration. It is needed only when several vector store starters are on the classpath, as in OrderDesk.
- initialize-schema=true lets Spring AI create the extension, the table and the index at startup. It is off by default.
- dimensions=768 sets the size of the vector column. It must match the embedding model.
- distance-type picks how closeness is measured. COSINE_DISTANCE is the usual choice for text.
- index-type picks HNSW, IVFFLAT or NONE.
Without the pgvector profile, OrderDesk uses its default in-memory store. The embedding model line stays in application.properties, because every store uses it. In your own app, you can put all these lines in application.properties and skip the profile.
These are the other spring.ai.vectorstore.pgvector properties that you may need:
| Property | Default | Use |
|---|---|---|
| table-name | vector_store | Name of the table |
| schema-name | public | Postgres schema of the table |
| remove-existing-vector-store-table | false | Drops the table at startup; useful after a model change |
| id-type | UUID | Type of the id column |
| max-document-batch-size | 10000 | Most documents inserted in one batch |
| schema-validation | false | Checks the table and the column size at startup |
Step 4: Load and Search the Policies
Now we start the app with the pgvector profile:
mvn spring-boot:run -Dspring-boot.run.profiles=pgvectorThe log shows the line The following 1 profile is active: “pgvector”.
The new table is empty, so we load the policies. Then we search with words that the policies don’t use. The -G option with –data-urlencode makes curl send the query as an encoded URL parameter:
curl -X POST localhost:8080/ingest
curl -G localhost:8080/search --data-urlencode "query=How many days do I have to send back a jacket?"
{"files":4,"sections":16,"chunks":16,"millis":2616}
[{"score":0.667,"topic":"returns","text":"Return window\nYou can return most items within 10 days of delivery. The item must be unused and in its original box with all tags."},{"score":0.644,"topic":"returns","text":"Refunds\nRefunds go back to the original payment method within 5 to 7 working days after we receive the item. If you choose store credit instead, it is added to your OrderDesk wallet at once."},{"score":0.607,"topic":"returns","text":"Damaged or wrong items\nIf an item arrives damaged or is not what you ordered, report it within 48 hours of delivery. Upload a photo of the item and the parcel on the order page. We send a replacement or give a full refund, and you do not pay for the return pickup."}]The search found the 10-day return window first, with a score of 0.667. Running /ingest again still leaves 16 rows, because the old rows are deleted first. The rows also survive an app restart.
Step 5: Inspect the Stored Rows with psql
Now let’s see what Spring AI created. The psql tool is Postgres’s command-line client:
PGPASSWORD=orderdesk psql -h localhost -U orderdesk -d orderdesk -c '\d vector_store'If psql is not installed on your computer, run it inside the container instead. The command is docker exec -it pgvector psql -U orderdesk -d orderdesk -c ‘\d vector_store’.
                     Table "public.vector_store"
  Column   |    Type     | Collation | Nullable |      Default
-----------+-------------+-----------+----------+--------------------
 id        | uuid        |           | not null | uuid_generate_v4()
 content   | text        |           |          |
 metadata  | json        |           |          |
 embedding | vector(768) |           |          |
Indexes:
    "vector_store_pkey" PRIMARY KEY, btree (id)
    "spring_ai_vector_index" hnsw (embedding vector_cosine_ops)
The table has four columns. The content column holds the text, metadata holds our topic and source keys as JSON, and embedding holds the 768 numbers. The HNSW index uses vector_cosine_ops because we chose cosine distance.
The rows look like any other table:
PGPASSWORD=orderdesk psql -h localhost -U orderdesk -d orderdesk -c "select id, left(content,40) content, metadata->>'topic' topic from vector_store limit 3" id | content | topic
--------------------------------------+--------------------------------------+----------
f9a2b21b-3495-4d40-b080-b2661858db7a | Payment methods +| payments
| We accept UPI, debit car |
70e7789b-a354-4990-86c4-2ebadbe69a32 | Cash on delivery +| payments
| Cash on delivery is ava |
e5b6014b-1397-41cd-9be3-8819486ffa94 | EMI +| payments
| No-cost EMI is available on credit c |The “+” marks a line break inside the text: each section starts with its heading on its own line.
4. Metadata Filters Become SQL
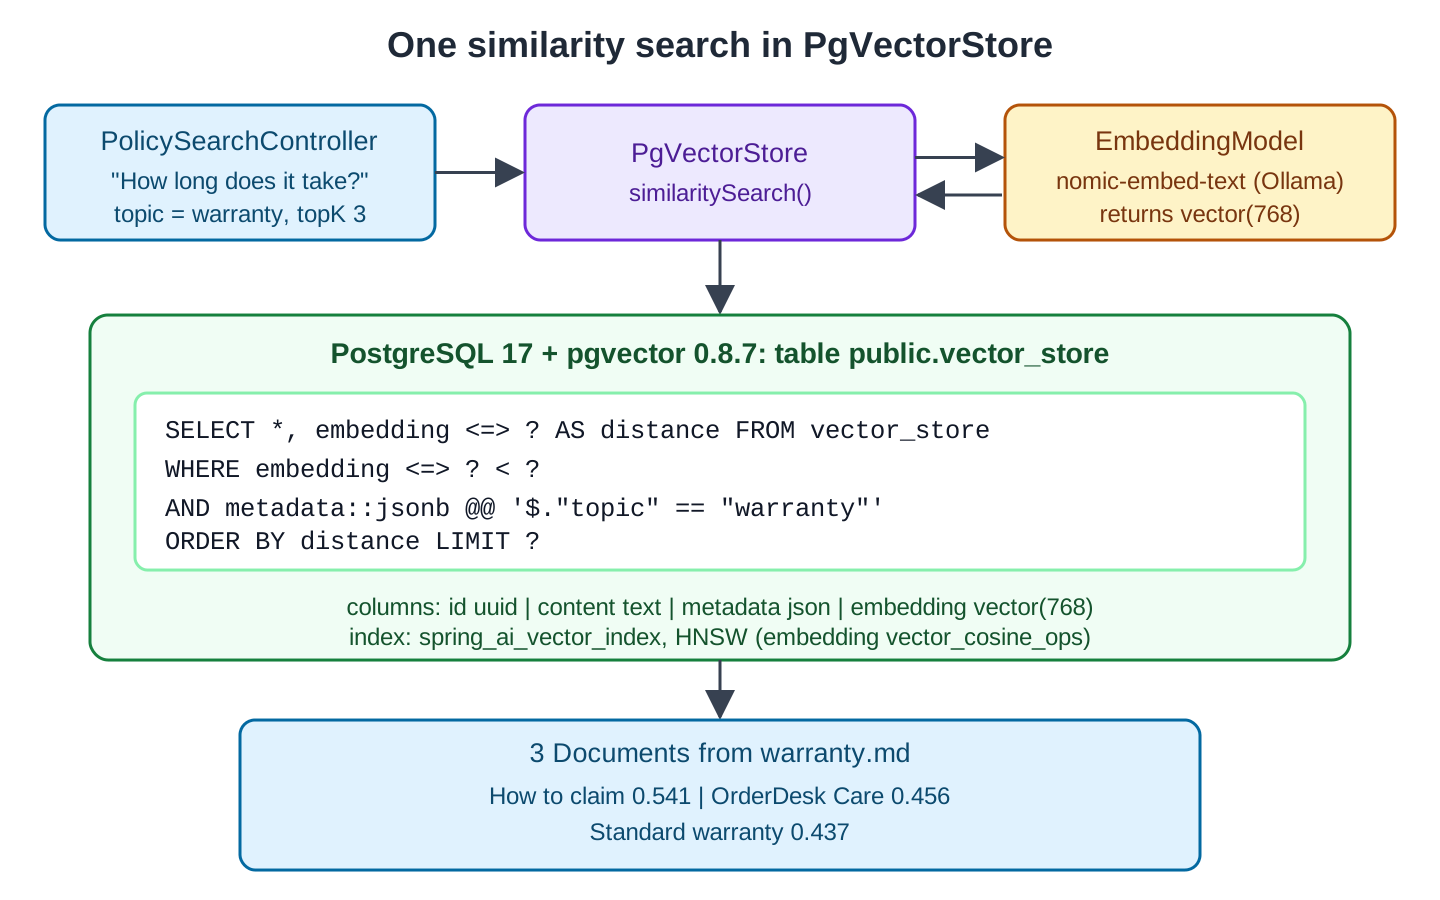
A filter expression such as topic == ‘warranty’ is a small text language that Spring AI converts for each store. FilterExpressionBuilder builds the same expressions in Java. Besides eq(), it has ne(), gt(), gte(), lt(), lte(), in(), nin(), and(), or() and not(). For pgvector, the expression becomes a JSON path condition on the metadata column. Let’s search with the filter:
curl -G localhost:8080/search --data-urlencode "query=How long does it take?" --data-urlencode "topic=warranty"[{"score":0.541,"topic":"warranty","text":"How to claim\nOpen the order page, choose the item and click Claim Warranty. A pickup is arranged within 3 working days."},{"score":0.456,"topic":"warranty","text":"OrderDesk Care\nOrderDesk Care adds one more year of warranty for INR 299. You can buy it only within 30 days of delivery."},{"score":0.437,"topic":"warranty","text":"Standard warranty\nElectronics sold on OrderDesk come with a 1-year manufacturer warranty from the date of delivery. Keep the invoice from the order page; the service centre asks for it."}]All three results came from warranty.md. To see the SQL, set the property logging.level.org.springframework.jdbc.core.JdbcTemplate to DEBUG and restart the app. This is the query that ran for the request above:
SELECT *, embedding <=> ? AS distance FROM public.vector_store WHERE embedding <=> ? < ? AND metadata::jsonb @@ '$."topic" == "warranty"'::jsonpath ORDER BY distance LIMIT ?The first two ? values are the question’s embedding. The third is the maximum distance, which Spring AI computes as 1 minus the similarity threshold. The last is topK. The filter is a JSON path match on metadata. The delete() call in PolicyIngestion used the same kind of condition:
DELETE FROM public.vector_store WHERE metadata::jsonb @@ '$."topic" == "returns"'::jsonpathThe add() call ran an INSERT … ON CONFLICT (id) DO UPDATE statement, so adding a Document with an existing id updates that row instead of failing.
This diagram shows how one search travels from the controller into Postgres:
5. Common Traps
5.1. Postgres Is Not Running
The app connects to Postgres during startup, for example when PgVectorStore creates its table (initialize-schema=true). With the container stopped, the app didn’t start:
Caused by: org.postgresql.util.PSQLException: Connection to localhost:5432 refused. Check that the hostname and port are correct and that the postmaster is accepting TCP/IP connections.Start the container with docker start pgvector, and start the app again.
5.2. The Dimensions Don’t Match the Model
The vector column has a fixed size. We set dimensions=1024 while nomic-embed-text returns 768 numbers. The app started, but /ingest failed on the first insert:
org.postgresql.util.PSQLException: ERROR: expected 1024 dimensions, not 768A model change also requires a compatible vector column and freshly generated embeddings. Rebuild into a new table or migrate the data deliberately. The remove-existing-vector-store-table option deletes the existing table, so use it only when that data is intentionally disposable or recoverable.
5.3. More Than 2000 Dimensions with an Index
Some models, such as OpenAI’s text-embedding-3-large (3072), return more than 2000 numbers. We set dimensions=3072 with the HNSW index, and the app failed at startup:
SQL [CREATE INDEX IF NOT EXISTS spring_ai_vector_index ON public.vector_store USING HNSW (embedding vector_cosine_ops)
]; ERROR: column cannot have more than 2000 dimensions for hnsw index
The error shown here concerns indexed columns of pgvector’s vector type. It is not a universal limit on all PostgreSQL vector representations: limits depend on the type and index. For the unchanged example, these options avoid the demonstrated mismatch:
- Use a model with 2000 dimensions or fewer. text-embedding-3-small has 1536.
- Ask the model for shorter embeddings, if it supports it. The OpenAI options have a dimensions setting for this.
- Set index-type=NONE. The search then compares the question with every row, which is fine for a few thousand rows.
5.4. Other Tables Move to Postgres Too
The auto-configured store uses the application’s main DataSource. Other components wired to that same DataSource also follow the PostgreSQL connection settings. To isolate vector storage, configure a separate data source and construct the vector-store bean with its own JdbcTemplate.
6. FAQs
6.1. Do I need a separate vector database if I use PostgreSQL?
You can use pgvector with the PostgreSQL service you already operate if it supports the extension and meets the search workload. Evaluate retrieval scale, indexes, filtering, latency, backups, and isolation before deciding that no separate service is needed.
6.2. Should I use HNSW or IVFFlat?
HNSW is the usual choice. It gives good results without training and works on an empty table. IVFFlat builds faster and uses less memory. But it should be created after the table has data, because it splits the existing vectors into groups.
6.3. Can I use the pgvector extension in a managed database?
Yes, on most cloud Postgres services, such as Amazon RDS, Azure Database for PostgreSQL and Google Cloud SQL. Check the service’s list of extensions and its pgvector version.
6.4. Can I query the vector_store table from my own SQL?
Yes. It is a normal table, so you can join it or count rows by topic. Keep the columns and their types as Spring AI created them, or PgVectorStore may fail to read the rows.
7. Conclusion
The example keeps OrderDesk’s ingestion and search interface while configuring PostgreSQL, pgvector, and a compatible vector index. The embedding model and vector column both use 768 dimensions.
Keep the embedding dimension, column type, and index capabilities aligned. A configuration property does not migrate existing stored embeddings; rebuild or migrate data deliberately when the representation changes.
All articles in order: Spring AI Tutorial
8. References
Drop me your questions related to Spring AI and pgvector in the comments.
Happy Learning !!
