
A vector store keeps document text, metadata, and embeddings, then retrieves documents whose vectors are close to a question’s vector. Spring AI exposes those operations through VectorStore.
In this article, OrderDesk loads store policies into SimpleVectorStore, searches them by meaning, and filters by topic and score. We then configure ChromaDB behind the same application interface and examine what changes in persistence, collections, and setup.
1. What Does a Vector Store Do?
An embedding model turns a text into an array of numbers. Texts with a similar meaning get arrays that sit close to each other. To find the policy section that answers a question, we compare the question’s array with the array of every section and pick the closest ones. This is called similarity search.
The store keeps text and metadata alongside each embedding and uses a configured distance metric to find nearby vectors. Database implementations can add indexes and operational features, but performance still depends on data size, filters, configuration, and the embedding step.
These terms come up in every vector store:
- Document: one piece of text that we store, with its id and metadata. In Spring AI, it is the Document class.
- Metadata: extra key-value pairs on a document, such as topic = returns. We can filter on them, like a WHERE clause in SQL.
- topK: the maximum number of nearest results requested, rather than a guarantee that all returned documents answer the question.
- Similarity threshold: the lowest score that a result may have. Results below it are dropped.
- Collection or index: the place inside the database that holds one set of documents. Each store uses its own word for it.
2. The VectorStore Interface
VectorStore is the Spring AI interface that every store implements. It gives every vector database the same Java methods, so we write the store and search code once. These are its main methods:
| Method | What it does |
|---|---|
| add(List<Document> documents) | Embeds each document with the EmbeddingModel and saves the text, metadata and embedding |
| similaritySearch(String query) | Embeds the query and returns the closest documents, with the default topK of 4 |
| similaritySearch(SearchRequest request) | Same, with our own topK, threshold and metadata filter |
| delete(List<String> ids) | Removes documents by id |
| delete(String filterExpression) | Removes every document whose metadata matches the filter |
The application supplies Document objects rather than precomputing vectors in this example. The configured EmbeddingModel embeds the documents and queries. Returned documents expose their text, metadata, and a retrieval score; score interpretation remains integration-dependent.
Spring AI has implementations for about 20 databases, including Chroma, pgvector, Redis, and Qdrant. SimpleVectorStore is the odd one: it keeps everything in a Java Map and can save it to a JSON file. It’s meant for learning and tests, not for production.
3. The Example App
This article adds one feature to OrderDesk, the support assistant of a demo online store and the app of this series. The code for this article belongs to the com.howtodoinjava.orderdesk.vectorstore and com.howtodoinjava.orderdesk.etl packages. The full app is on GitHub in the orderdesk folder.
OrderDesk runs on Spring Boot 4.1.1, Spring AI 2.0.1, and Java 21, with Ollama 0.40.6. The basic setup (installing Ollama, the Spring Boot project, the Spring AI BOM, and the Ollama starter) is explained in Getting Started with Spring AI. This article adds an embedding model, the policy files, and two dependencies on top of that.
3.1. The Embedding Model
A vector store needs an embedding model to turn texts into arrays. We use nomic-embed-text in Ollama, which returns 768 numbers for any text. Let’s download it:
ollama pull nomic-embed-textThen we name it in application.properties. The Ollama starter creates the EmbeddingModel bean from this property:
# Embedding model for RAG (ollama pull nomic-embed-text)
spring.ai.ollama.embedding.options.model=nomic-embed-text
To learn how embeddings and their scores work, see Spring AI EmbeddingModel: Vector Embedding Example.
3.2. The Policy Files
OrderDesk’s knowledge lives in four Markdown files in src/main/resources/policies. Each file has a few sections with a “##” heading. This is returns.md:
# Returns and Refunds

## Return window

You can return most items within 10 days of delivery. The item must be unused and in its original box with all tags.

## Damaged or wrong items

If an item arrives damaged or is not what you ordered, report it within 48 hours of delivery. Upload a photo of the item and the parcel on the order page. We send a replacement or give a full refund, and you do not pay for the return pickup.

## Items you cannot return

- Earphones and headphones once the seal is opened
- Groceries and other perishable items
- Gift cards

## Refunds

Refunds go back to the original payment method within 5 to 7 working days after we receive the item. If you choose store credit instead, it is added to your OrderDesk wallet at once.
The other three files are on GitHub: shipping.md, warranty.md, and payments.md. Copy them to get the same outputs as this article, or use any Markdown file with “##” sections. The four files have 16 sections in total, and each section becomes one Document in the store.
3.3. The Dependencies
The first part of this article needs two Spring AI modules. The spring-ai-markdown-document-reader module reads the Markdown files, and the spring-ai-vector-store module holds the VectorStore interface and SimpleVectorStore. Add both to pom.xml; the Spring AI BOM sets their versions:
<dependency>
  <groupId>org.springframework.ai</groupId>
  <artifactId>spring-ai-markdown-document-reader</artifactId>
</dependency>
<dependency>
  <groupId>org.springframework.ai</groupId>
  <artifactId>spring-ai-vector-store</artifactId>
</dependency>
The OrderDesk pom.xml on GitHub doesn’t list spring-ai-vector-store itself, because the RAG modules that later articles add bring it in. Section 5 adds the Chroma starter.
New classes go in sub-packages of com.howtodoinjava.orderdesk, the package of the main class OrderDeskApplication, so Spring Boot finds them at startup. If your main class is in another package, put the classes under that package. Start Ollama and the app as shown in Getting Started with Spring AI, and restart the app after adding code.
4. Load Policies, Search, and Apply Filters
Step 1: Create a SimpleVectorStore Bean
SimpleVectorStoreConfig creates a SimpleVectorStore bean (an object that Spring creates and hands to every class that asks for it):
package com.howtodoinjava.orderdesk.vectorstore;

import java.io.File;

import org.springframework.ai.embedding.EmbeddingModel;
import org.springframework.ai.vectorstore.SimpleVectorStore;
import org.springframework.boot.autoconfigure.condition.ConditionalOnProperty;
import org.springframework.context.annotation.Bean;
import org.springframework.context.annotation.Configuration;

@Configuration
@ConditionalOnProperty(name = "spring.ai.vectorstore.type", havingValue = "simple")
public class SimpleVectorStoreConfig {

    // SimpleVectorStore keeps vectors in memory; we save them to this file
    public static final File STORE_FILE = new File("data/vector-store.json");

    @Bean
    SimpleVectorStore vectorStore(EmbeddingModel embeddingModel) {
        SimpleVectorStore store = SimpleVectorStore.builder(embeddingModel).build();
        if (STORE_FILE.exists()) {
            store.load(STORE_FILE);
        }
        return store;
    }
}
Line by line:
- SimpleVectorStore.builder(embeddingModel) gives the store the EmbeddingModel bean, which it uses in add() and similaritySearch().
- STORE_FILE is the JSON file where we save the store. Its path is relative to the folder the app starts in, which is the project folder with mvn spring-boot:run. load() reads the file back at startup, so the documents survive a restart.
- @ConditionalOnProperty creates this bean only when spring.ai.vectorstore.type is simple.
So add this line to application.properties now. Without it, there is no VectorStore bean, and the app doesn’t start:
spring.ai.vectorstore.type=simpleSpring AI reads spring.ai.vectorstore.type to decide which of its vector store auto-configurations runs. The finished OrderDesk app has several vector store starters, so this one property picks the active one.
Spring AI doesn’t know the value simple. We use it for two things: it keeps Spring AI’s stores off, and it turns on our SimpleVectorStoreConfig. An app with a single vector store starter needs neither the property nor the condition.
The class on GitHub also passes an ObservationRegistry to the builder, for metrics and traces. This article doesn’t need it.
Step 2: Load the Policy Files into the Store
Next, we fill the store. PolicyIngestion reads the four files, turns each section into a Document, and adds them to the VectorStore. Reading, preparing, and saving documents like this is called an ETL pipeline (extract, transform, load):
package com.howtodoinjava.orderdesk.etl;

import java.io.IOException;
import java.util.ArrayList;
import java.util.List;

import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
import org.springframework.ai.document.Document;
import org.springframework.ai.reader.markdown.MarkdownDocumentReader;
import org.springframework.ai.reader.markdown.config.MarkdownDocumentReaderConfig;
import org.springframework.ai.transformer.splitter.TokenTextSplitter;
import org.springframework.ai.vectorstore.SimpleVectorStore;
import org.springframework.ai.vectorstore.VectorStore;
import org.springframework.core.io.Resource;
import org.springframework.core.io.support.PathMatchingResourcePatternResolver;
import org.springframework.stereotype.Service;

import com.howtodoinjava.orderdesk.vectorstore.SimpleVectorStoreConfig;

@Service
public class PolicyIngestion {

    private static final Logger log = LoggerFactory.getLogger(PolicyIngestion.class);

    private final VectorStore vectorStore;

    PolicyIngestion(VectorStore vectorStore) {
        this.vectorStore = vectorStore;
    }

    public IngestResult ingest() throws IOException {
        long start = System.currentTimeMillis();

        // Extract: one Document per section of every policy file
        Resource[] files = new PathMatchingResourcePatternResolver()
            .getResources("classpath:policies/*.md");
        List<Document> documents = new ArrayList<>();
        for (Resource file : files) {
            String topic = file.getFilename().replace(".md", "");
            MarkdownDocumentReaderConfig config = MarkdownDocumentReaderConfig.builder()
                .withAdditionalMetadata("topic", topic)
                .withAdditionalMetadata("source", file.getFilename())
                .build();
            documents.addAll(new MarkdownDocumentReader(file, config).get());
        }

        // Transform: put each section's heading back into its text,
        // because MarkdownDocumentReader keeps the heading only in the metadata
        documents = documents.stream()
            .map(d -> new Document(d.getMetadata().get("title") + "\n" + d.getText(),
                d.getMetadata()))
            .toList();

        // Transform: split long sections into chunks the embedding model can take
        TokenTextSplitter splitter = TokenTextSplitter.builder()
            .withChunkSize(300)
            .build();
        List<Document> chunks = splitter.apply(documents);

        // Load: remove the old chunks of each file, then add the new ones
        for (Resource file : files) {
            String topic = file.getFilename().replace(".md", "");
            vectorStore.delete("topic == '" + topic + "'");
        }
        vectorStore.add(chunks);
        if (vectorStore instanceof SimpleVectorStore simple) {
            SimpleVectorStoreConfig.STORE_FILE.getParentFile().mkdirs();
            simple.save(SimpleVectorStoreConfig.STORE_FILE);
        }

        long millis = System.currentTimeMillis() - start;
        log.info("Ingested {} files, {} sections, {} chunks in {} ms",
            files.length, documents.size(), chunks.size(), millis);
        return new IngestResult(files.length, documents.size(), chunks.size(), millis);
    }

    public record IngestResult(int files, int sections, int chunks, long millis) {
    }
}
The parts that matter for the vector store are these:
- MarkdownDocumentReader reads one file and returns one Document per section. We add two metadata keys to every section: topic (such as “returns”) and source (the file name).
- The reader keeps each section’s heading only in the title metadata. We put it back in front of the text, so the heading is embedded too. The stored JSON below shows the result.
- TokenTextSplitter cuts a section into chunks of at most 300 tokens (pieces of words). Our sections are short, so no section is cut.
- vectorStore.delete(“topic == ‘returns'”) removes the old documents of a file before we add it again. Without it, every run would add a second copy. Building this filter from text is safe here, because topic comes from our own file names, not from a request (see Step 4).
To learn each part of this pipeline in depth, see Spring AI ETL Pipeline Example for Data Ingestion. A small controller runs the pipeline on a POST request:
package com.howtodoinjava.orderdesk.etl;

import java.io.IOException;

import org.springframework.web.bind.annotation.PostMapping;
import org.springframework.web.bind.annotation.RestController;

@RestController
public class IngestController {

    private final PolicyIngestion policyIngestion;

    IngestController(PolicyIngestion policyIngestion) {
        this.policyIngestion = policyIngestion;
    }

    @PostMapping("/ingest")
    PolicyIngestion.IngestResult ingest() throws IOException {
        return policyIngestion.ingest();
    }
}
Let’s load the policies:
curl -X POST localhost:8080/ingest{"files":4,"sections":16,"chunks":16,"millis":3127}Each of the 16 sections became one chunk. A second call still leaves 16 documents, because the old ones are deleted first.
This is one stored document, read from data/vector-store.json. The embedding is shortened here; it holds 768 numbers:
{
 "id": "cc29e67b-312b-4a4d-b1fd-b77baca233e3",
 "text": "Failed payments\nIf money is taken from your account but the order is not placed, it is refunded automatically within 3 working days.",
 "metadata": {
  "parent_document_id": "51662816-a0c7-49d3-8165-cc2043ea8cec",
  "category": "header_2",
  "topic": "payments",
  "title": "Failed payments",
  "chunk_index": 0,
  "total_chunks": 1,
  "source": "payments.md"
 },
 "embedding": "768 numbers"
}
Our topic and source keys are there. The Markdown reader and the splitter added the other keys.
Step 3: Search by Meaning
Now we search the store. PolicySearchController builds a SearchRequest from the request parameters:
package com.howtodoinjava.orderdesk.vectorstore;

import java.util.List;

import org.springframework.ai.document.Document;
import org.springframework.ai.vectorstore.SearchRequest;
import org.springframework.ai.vectorstore.VectorStore;
import org.springframework.ai.vectorstore.filter.FilterExpressionBuilder;
import org.springframework.web.bind.annotation.GetMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;

@RestController
public class PolicySearchController {

    private final VectorStore vectorStore;

    PolicySearchController(VectorStore vectorStore) {
        this.vectorStore = vectorStore;
    }

    @GetMapping("/search")
    List<SearchHit> search(@RequestParam String query,
                           @RequestParam(defaultValue = "3") int topK,
                           @RequestParam(defaultValue = "0.0") double threshold,
                           @RequestParam(required = false) String topic) {

        SearchRequest.Builder request = SearchRequest.builder()
            .query(query)
            .topK(topK)
            .similarityThreshold(threshold);
        if (topic != null) {
            // the builder treats topic as a value, never as part of the expression
            request.filterExpression(new FilterExpressionBuilder().eq("topic", topic).build());
        }

        List<Document> documents = vectorStore.similaritySearch(request.build());
        return documents.stream()
            .map(d -> new SearchHit(
                Math.round(d.getScore() * 1000) / 1000.0,
                String.valueOf(d.getMetadata().get("topic")),
                d.getText()))
            .toList();
    }

    record SearchHit(double score, String topic, String text) {
    }
}
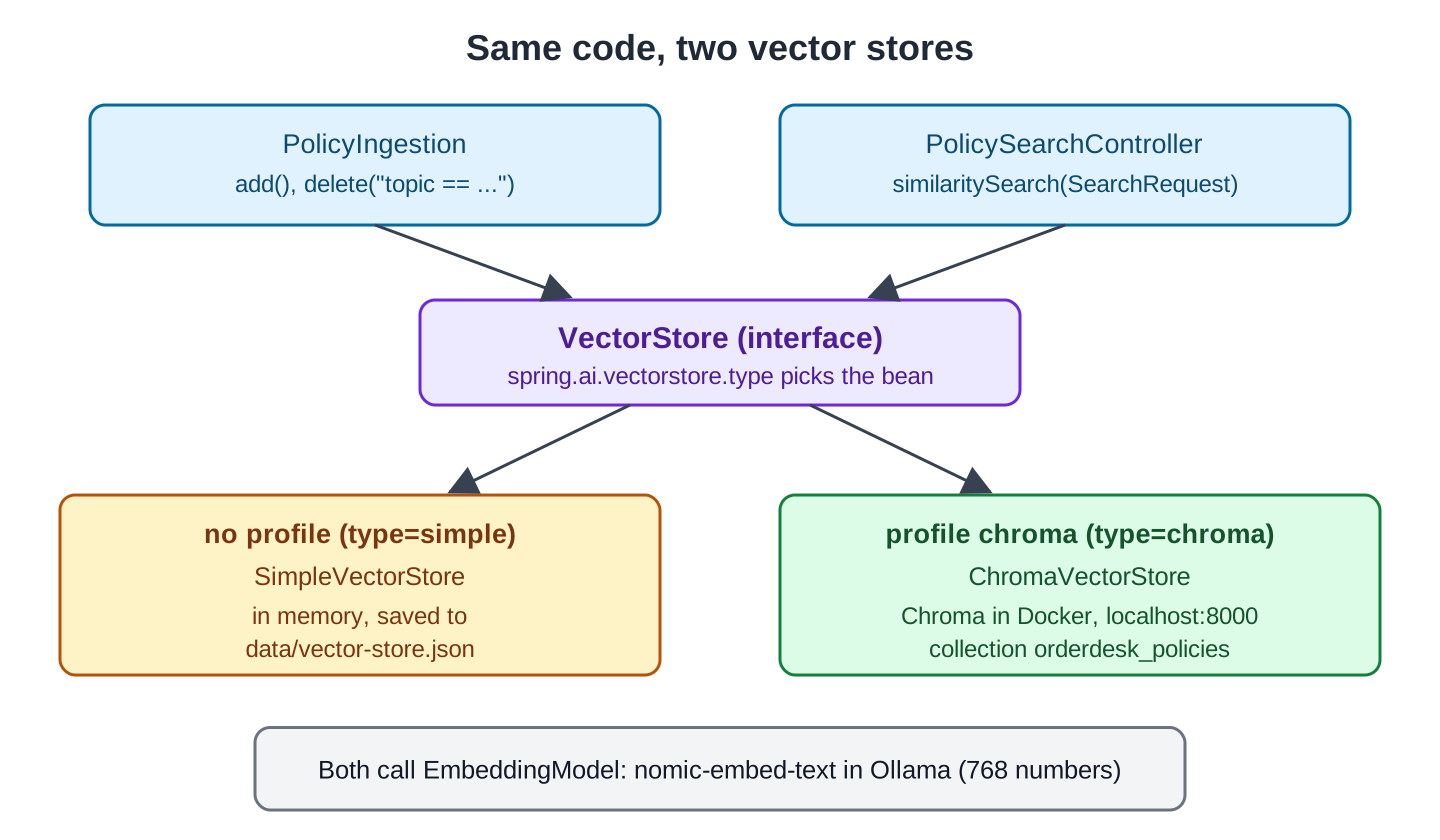
The controller asks only for a VectorStore. It doesn’t know which store is behind it, so it works unchanged with Chroma in Section 5.
Let’s search with words that the policy doesn’t use. The -G option with –data-urlencode makes curl send the query as an encoded URL parameter:
curl -G localhost:8080/search --data-urlencode "query=How many days do I have to send back a jacket?"[{"score":0.667,"topic":"returns","text":"Return window\nYou can return most items within 10 days of delivery. The item must be unused and in its original box with all tags."},{"score":0.644,"topic":"returns","text":"Refunds\nRefunds go back to the original payment method within 5 to 7 working days after we receive the item. If you choose store credit instead, it is added to your OrderDesk wallet at once."},{"score":0.607,"topic":"returns","text":"Damaged or wrong items\nIf an item arrives damaged or is not what you ordered, report it within 48 hours of delivery. Upload a photo of the item and the parcel on the order page. We send a replacement or give a full refund, and you do not pay for the return pickup."}]The question said “send back” and “jacket”, and the store still found “return” and “items”.
Step 4: Filter by Metadata and Score
A filter expression limits results to part of the data. Spring AI converts it to each store’s own query syntax. Here, the topic parameter makes the controller add a filter that keeps only the warranty sections:
curl -G localhost:8080/search --data-urlencode "query=How long does it take?" --data-urlencode "topic=warranty"[{"score":0.541,"topic":"warranty","text":"How to claim\nOpen the order page, choose the item and click Claim Warranty. A pickup is arranged within 3 working days."},{"score":0.456,"topic":"warranty","text":"OrderDesk Care\nOrderDesk Care adds one more year of warranty for INR 299. You can buy it only within 30 days of delivery."},{"score":0.437,"topic":"warranty","text":"Standard warranty\nElectronics sold on OrderDesk come with a 1-year manufacturer warranty from the date of delivery. Keep the invoice from the order page; the service centre asks for it."}]“How long does it take?” alone could be about delivery, refunds, or warranty. With the filter, all three results are warranty sections. A filter can be written as text, such as “topic == ‘warranty'”, or built with FilterExpressionBuilder, as the controller does.
Don’t build the filter text from user input. A user could send warranty’ || topic != ‘x and change the filter, like SQL injection. The builder treats it as a plain value.
The filter language also has !=, >, <, in, nin (not in), && and ||. The builder has a method for each, such as in(“topic”, “returns”, “shipping”).
A question that the policies don’t cover still gets results without a threshold. “Do you sell pizza?” with topK 2 returned the delivery-area section with 0.481 and a returns section with 0.454. With a threshold of 0.5, the same question returned nothing:
curl -G localhost:8080/search --data-urlencode "query=Do you sell pizza?" --data-urlencode "threshold=0.5"[]An empty result means no candidate passed the configured retrieval conditions. It does not prove the knowledge base contains no answer: an overly strict threshold or a poorly phrased query can hide relevant documents. Evaluate both successful matches and missed matches.
5. Replace the In-Memory Store with ChromaDB
SimpleVectorStore keeps its working data in process memory. A saved JSON file can restore a small example after a restart, but is not a coordinated shared database for multiple application instances. Chroma moves document persistence and search into a separate service.
5.1. Starting Chroma in Docker
We run Chroma in Docker (a tool that runs packaged applications in containers), so Docker must be installed. The -p option publishes Chroma’s port 8000 on our computer:
docker run -d --name chroma -p 8000:8000 chromadb/chromaThe untagged command follows the image’s default tag, so a later download may differ from the recorded version. The original example reports Chroma 1.0.0. Pin a compatible image version when reproducing the setup and check its API compatibility with Spring AI.
curl localhost:8000/api/v2/version"1.0.0"The container keeps its data inside itself. It survives docker stop and docker start, but not docker rm. To keep the data in a folder of your computer, add a volume, for example -v ./chroma-data:/data.
5.2. Adding the Chroma Starter and Properties
Next, we add the Chroma starter to pom.xml. It brings ChromaVectorStore and its auto-configuration:
<dependency>
  <groupId>org.springframework.ai</groupId>
  <artifactId>spring-ai-starter-vector-store-chroma</artifactId>
</dependency>
Then we put Chroma’s settings in a profile file, src/main/resources/application-chroma.properties. A Spring profile is a named set of properties that we turn on at startup. Its properties override those in application.properties:
# docker run -d --name chroma -p 8000:8000 chromadb/chroma
spring.ai.vectorstore.type=chroma
spring.ai.vectorstore.chroma.client.host=http://localhost
spring.ai.vectorstore.chroma.client.port=8000
spring.ai.vectorstore.chroma.collection-name=orderdesk_policies
spring.ai.vectorstore.chroma.initialize-schema=true
Line by line:
- spring.ai.vectorstore.type=chroma turns on Chroma’s auto-configuration. It also turns off our SimpleVectorStoreConfig, because the value is no longer simple.
- client.host and client.port point to the Chroma server.
- collection-name names the collection that holds our documents.
- initialize-schema=true lets Spring AI create the collection if it doesn’t exist. It is off by default, so without it the app fails at startup on a new Chroma server.
Chroma’s auto-configuration creates a ChromaVectorStore bean.
5.3. Running OrderDesk with Chroma
We start the app with the chroma profile. With Maven, the profile goes in the spring-boot.run.profiles option:
mvn spring-boot:run -Dspring-boot.run.profiles=chromaChroma starts empty, so we load the policies again, then repeat the search from Step 3:
curl -X POST localhost:8080/ingest
curl -G localhost:8080/search --data-urlencode "query=How many days do I have to send back a jacket?"
{"files":4,"sections":16,"chunks":16,"millis":2625}
[{"score":0.667,"topic":"returns","text":"Return window\nYou can return most items within 10 days of delivery. The item must be unused and in its original box with all tags."},{"score":0.644,"topic":"returns","text":"Refunds\nRefunds go back to the original payment method within 5 to 7 working days after we receive the item. If you choose store credit instead, it is added to your OrderDesk wallet at once."},{"score":0.607,"topic":"returns","text":"Damaged or wrong items\nIf an item arrives damaged or is not what you ordered, report it within 48 hours of delivery. Upload a photo of the item and the parcel on the order page. We send a replacement or give a full refund, and you do not pay for the return pickup."}]Chroma returned the same three sections with the same scores as SimpleVectorStore, and the same warranty-filter results. After an app restart, all 16 documents were still in Chroma.
This diagram shows the two stores behind the same code:
5.4. Looking Inside Chroma
Spring AI doesn’t use Chroma’s default tenant and database. It creates its own, named SpringAiTenant and SpringAiDatabase. So we list the collections there with Chroma’s REST API:
curl localhost:8000/api/v2/tenants/SpringAiTenant/databases/SpringAiDatabase/collectionsThe response shows the collection orderdesk_policies with a dimension of 768 and the metadata hnsw:space: cosine. The dimension matches the size of nomic-embed-text‘s arrays, and the metadata shows the distance that Chroma uses.
To use another tenant or database, set spring.ai.vectorstore.chroma.tenant-name and spring.ai.vectorstore.chroma.database-name.
6. Common Traps
6.1. Chroma Is Not Running
ChromaVectorStore contacts Chroma when the app starts. If Chroma is stopped, the app doesn’t start at all, and the log shows the cause:
I/O error on GET request for "http://localhost:8000/api/v2/tenants/SpringAiTenant/databases/SpringAiDatabase/collections/orderdesk_policies": finishConnect(..) failed with error(-111): Connection refused: localhost/127.0.0.1:8000Start the container with docker start chroma, and start the app again.
6.2. Changing the Embedding Model
The first time we add documents, Chroma fixes the collection’s array size (768 for nomic-embed-text). After that, it accepts only arrays of that size. We pulled all-minilm, a model that returns 384 numbers, set spring.ai.ollama.embedding.options.model=all-minilm, and called /ingest again:
400 Bad Request: "{"error":"InvalidArgumentError","message":"Collection expecting embedding with dimension of 768, got 384"}"Searches failed with the same error, because the question’s embedding also had 384 numbers. When you change the embedding model, set a new collection-name and load all documents again. To drop the old collections too, remove the container with docker rm -f chroma and start a new one; this deletes all Chroma data.
6.3. Looking in the Wrong Tenant
Chroma’s tools look in default_tenant and default_database, so they show no collections even though the app works. Use the URL from Section 5.4, or set the tenant and database properties.
6.4. Losing SimpleVectorStore Data
SimpleVectorStore lives in memory. Without save() and load(), every restart starts with an empty store, and searches return nothing until the next /ingest. OrderDesk saves the file after each ingest and loads it at startup.
7. FAQs
7.1. Do I need to change Java code to switch vector stores?
The application’s add and search calls can remain the same when they depend on VectorStore, as this example demonstrates. The replacement still needs its dependency, connection settings, collection setup, data load, and checks for filtering and score behavior.
7.2. Where does Spring AI compute the embeddings?
Spring AI invokes the configured EmbeddingModel for the document and query vectors. With localhost Ollama, inference runs in that local service; with a hosted embedding provider, the submitted text goes there. The Chroma integration does not rely on Chroma embedding the text itself.
7.3. What does initialize-schema do?
It lets Spring AI create the collection, table or index that the store needs. It is off by default for most stores.
7.4. How many documents can SimpleVectorStore hold?
As many as fit in the app’s memory, and every search compares the question with all of them. That is fine for a few thousand chunks in a test. For more, or for several app instances, use a database store.
7.5. Can I see the scores in Chroma’s own units?
Spring AI converts each store’s distance to a similarity score, where higher means closer. In our run, Chroma and SimpleVectorStore gave the same scores. Some stores report scores on another scale, so check the scores again before you move a threshold from one store to another.
8. Conclusion
VectorStore lets ingestion and retrieval code work against a common interface. The example moves from an in-process store to Chroma while retaining its Java calls. Persistence, collection configuration, and operational behavior still need deliberate setup.
Treat the embedding model as part of the stored-data format. Regenerate vectors for a model change and recheck relevance thresholds after changing either the model or store.
All articles in order: Spring AI Tutorial
9. References
Drop me your questions related to the Spring AI VectorStore in the comments.
Happy Learning !!
