
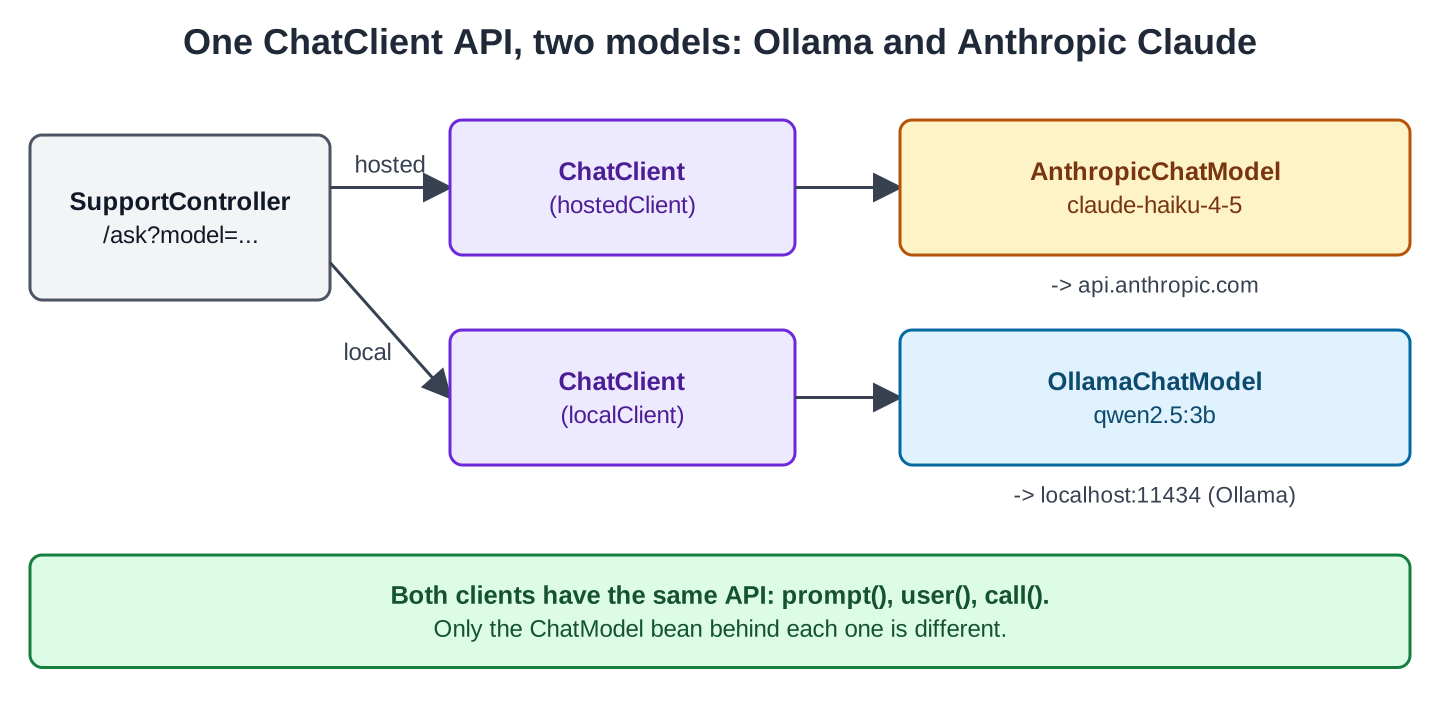
Spring AI can connect a Spring Boot application to Anthropic Claude while retaining a local Ollama backend. The controller uses the same ChatClient API for both and selects a client from a request parameter.
This example covers the Anthropic starter, API-key configuration, response metadata, and extended thinking. The recorded answers come from Ollama. Captured Claude request bodies demonstrate the integration, but no successful Anthropic response was obtained with a valid account key.
1. How Spring AI Connects to Claude and Ollama
Both backends turn messages into a response. Their deployment, capabilities, performance, and costs differ, so compare models using the requests your application actually needs to answer.
- Ollama runs inference on your machine. The local setup avoids a hosted API charge and does not send prompts to Anthropic, while consuming local compute and memory.
- Claude runs through Anthropic’s service. Calls need account access and an API key, send prompts to the provider, and are subject to its pricing and limits.
Keeping both clients in one application lets the caller select a backend without changing the endpoint’s calling code. The example uses explicit selection rather than automatic routing.
If every provider had a different Java API, you’d have to rewrite your code when switching providers. Spring AI avoids this by defining a common interface called ChatModel. Each provider module implements this interface with its own class, such as OllamaChatModel or AnthropicChatModel. ChatClient provides a consistent API for interacting with a ChatModel, so your controller can send a question through ChatClient without depending directly on a particular provider.
This means the code that sends a question can stay the same when you switch providers, as long as the new provider supports the features your application needs. Here’s what that looks like:
The Spring AI chat model overview lists the supported providers. The rest of this article covers the Anthropic parts: the dependency, the API key, the properties, and Claude’s extended thinking.
2. Configure the Spring Boot Application
The example is a Spring Boot 4.1 app called orderdesk-anthropic, and it uses Spring AI 2.0.1 and Java 21. You can find the project in the spring-ai-examples repository on GitHub. If you need help installing Ollama and downloading the qwen2.5:3b model, follow the Getting Started with Spring AI tutorial.
2.1. Dependencies
Here is the full pom.xml. It uses the Spring Boot 4.1.1 parent and imports the Spring AI BOM (bill of materials), which sets the version of every Spring AI module:
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
  xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
  xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 https://maven.apache.org/xsd/maven-4.0.0.xsd">
  <modelVersion>4.0.0</modelVersion>

  <parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>4.1.1</version>
    <relativePath/>
  </parent>

  <groupId>com.howtodoinjava</groupId>
  <artifactId>orderdesk-anthropic</artifactId>
  <version>1.0.0</version>

  <properties>
    <java.version>21</java.version>
  </properties>

  <dependencyManagement>
    <dependencies>
      <dependency>
        <groupId>org.springframework.ai</groupId>
        <artifactId>spring-ai-bom</artifactId>
        <version>2.0.1</version>
        <type>pom</type>
        <scope>import</scope>
      </dependency>
    </dependencies>
  </dependencyManagement>

  <dependencies>
    <dependency>
      <groupId>org.springframework.boot</groupId>
      <artifactId>spring-boot-starter-webmvc</artifactId>
    </dependency>
    <dependency>
      <groupId>org.springframework.ai</groupId>
      <artifactId>spring-ai-starter-model-ollama</artifactId>
    </dependency>
    <dependency>
      <groupId>org.springframework.ai</groupId>
      <artifactId>spring-ai-starter-model-anthropic</artifactId>
    </dependency>
  </dependencies>

  <build>
    <plugins>
      <plugin>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-maven-plugin</artifactId>
      </plugin>
    </plugins>
  </build>
</project>
The spring-ai-starter-model-anthropic starter adds the AnthropicChatModel bean. The spring-boot-starter-webmvc dependency is the Spring Boot 4 name of the web starter.
2.2. Configure the Anthropic API Key
Create a key in the Anthropic Console. Your account may also need credits before the API accepts requests. The key is a secret, so keep it out of your code and your Git repository. Put it in an environment variable instead:
export SPRING_AI_ANTHROPIC_API_KEY=sk-ant-your-keyOn Windows PowerShell, use $env:SPRING_AI_ANTHROPIC_API_KEY=”sk-ant-your-key”. Set it in the same terminal where you start the app, or in your IDE’s run configuration. Spring Boot reads this variable as the spring.ai.anthropic.api-key property. According to the Spring AI Anthropic page, the ANTHROPIC_API_KEY variable also works.
In the recorded configuration, the missing key was detected when the Claude client attempted its first request. Successful application startup alone therefore does not establish that Anthropic access works:
com.anthropic.errors.UnauthorizedException: 401: {"type":"error","error":{"type":"authentication_error","message":"x-api-key header is required"},...}The error comes from Anthropic’s Java SDK, which backs Spring AI’s AnthropicChatModel. A missing credential or invalid key is an authentication problem, rather than evidence of a successful model call. Ollama requests do not use this key.
2.3. Select the Claude Model and Response Limits
Here is the full application.properties:
spring.application.name=orderdesk-anthropic
server.port=8083

# Two chat models in one app, so we build the ChatClients ourselves
spring.ai.chat.client.enabled=false

# The local model, as in the other OrderDesk articles
spring.ai.ollama.base-url=http://localhost:11434
spring.ai.ollama.chat.model=qwen2.5:3b
spring.ai.ollama.chat.temperature=0.2

# The key comes from the environment variable SPRING_AI_ANTHROPIC_API_KEY
spring.ai.anthropic.chat.model=claude-haiku-4-5
spring.ai.anthropic.chat.max-tokens=500
spring.ai.anthropic.chat.temperature=0.2
Port 8083 separates this application from the other examples. The Anthropic options select a model, set a 500-token output limit, and configure sampling temperature. A low temperature can reduce variation where supported, but cannot ensure correct answers.
The sample explicitly selects claude-haiku-4-5. Check Anthropic’s model overview for availability, pricing, and capabilities. Evaluate a different model on your own tasks before treating it as an improvement.
The application creates two clients explicitly, so spring.ai.chat.client.enabled=false disables the auto-configured builder. Each client is bound to its intended model in ChatConfig. The ChatClient reference describes other multiple-model arrangements.
3. Create Separate Claude and Ollama Clients
ChatConfig creates one client per model. Each client gets the same system prompt. A system prompt is an instruction sent with every request, and defaultSystem(…) sets it once for the client:
package com.howtodoinjava.orderdesk.anthropic;

import org.springframework.ai.chat.client.ChatClient;
import org.springframework.ai.ollama.OllamaChatModel;
import org.springframework.ai.anthropic.AnthropicChatModel;
import org.springframework.context.annotation.Bean;
import org.springframework.context.annotation.Configuration;

@Configuration
public class ChatConfig {

    static final String SUPPORT = "You are OrderDesk, the support assistant of an online store. "
        + "Answer in at most three sentences.";

    // The hosted model: for questions that need a stronger model
    @Bean
    ChatClient hostedClient(AnthropicChatModel chatModel) {
        return ChatClient.builder(chatModel).defaultSystem(SUPPORT).build();
    }

    // The local model in Ollama: free, for simple questions
    @Bean
    ChatClient localClient(OllamaChatModel chatModel) {
        return ChatClient.builder(chatModel).defaultSystem(SUPPORT).build();
    }
}
Injecting AnthropicChatModel and OllamaChatModel by concrete type identifies the intended backend. Each ChatClient.builder(chatModel) call then receives its own model without an ambiguous choice between ChatModel beans.
The controller picks a client from a request parameter. It returns the answer, the model name, and the token counts, which change between providers:
package com.howtodoinjava.orderdesk.anthropic;

// The answer plus the facts that differ between models
public record Reply(String model, String answer, Integer inputTokens, Integer outputTokens) {
}
package com.howtodoinjava.orderdesk.anthropic;
import org.springframework.ai.chat.client.ChatClient;
import org.springframework.ai.chat.metadata.ChatResponseMetadata;
import org.springframework.ai.chat.model.ChatResponse;
import org.springframework.beans.factory.annotation.Qualifier;
import org.springframework.web.bind.annotation.GetMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;
@RestController
public class SupportController {
private final ChatClient hostedClient;
private final ChatClient localClient;
SupportController(@Qualifier("hostedClient") ChatClient hostedClient,
@Qualifier("localClient") ChatClient localClient) {
this.hostedClient = hostedClient;
this.localClient = localClient;
}
// model=hosted (default) or model=local
@GetMapping("/ask")
Reply ask(@RequestParam String question,
@RequestParam(defaultValue = "hosted") String model) {
ChatClient client = "local".equals(model) ? localClient : hostedClient;
ChatResponse response = client.prompt().user(question).call().chatResponse();
ChatResponseMetadata metadata = response.getMetadata();
return new Reply(metadata.getModel(), response.getResult().getOutput().getText(),
metadata.getUsage().getPromptTokens(), metadata.getUsage().getCompletionTokens());
}
}@Qualifier tells Spring which bean to inject when multiple beans match the required type. In this example, it identifies the bean by the name of the @Bean method. Any model value other than local selects Claude.
The chatResponse() method returns the full response rather than just the generated text. This lets us access the response metadata, including the model name and token usage through Usage.
4. Call the Endpoint and Inspect the Claude Request
Start Ollama with the configured model, then launch the application with mvn spring-boot:run. Select the local backend for the recorded example:
curl -G localhost:8083/ask --data-urlencode "question=Can I return a kettle after 5 days?" \
  --data-urlencode model=local
{"model":"qwen2.5:3b","answer":"Yes, you can return a kettle within 5 days, but it's best to check your store's specific return policy as some may have different terms.","inputTokens":43,"outputTokens":32}Without model=local, the controller selects Claude. A valid account key is required for a hosted answer. The following body was captured by a recording server at the Anthropic API path /v1/messages. It shows the outgoing request, rather than a Claude-generated response:
{"max_tokens":500,"messages":[{"content":"Can I return a kettle after 5 days?","role":"user"}],"model":"claude-haiku-4-5","system":"You are OrderDesk, the support assistant of an online store. Answer in at most three sentences.","temperature":0.2}Anthropic’s Messages API puts the system prompt in its own system field, not in the messages. Spring AI does this for us.
The prompt does not supply OrderDesk’s ten-day return policy. That business rule must come from application instructions, retrieval, or tools. Changing the backend does not give either model access to the store’s policies.
5. Configure Extended Thinking for One Request
A support decision may involve several policy conditions or calculations. On supported Claude models, extended thinking allocates additional reasoning work before the final answer. It can affect latency and token usage, so enable it where evaluation demonstrates a useful benefit.
The response can contain text blocks, thinking-related blocks, and signatures. Exposed thinking content may be summarized or omitted depending on the model and options; it should not be assumed to reveal every internal reasoning step.
We turn thinking on for one request with AnthropicChatOptions:
package com.howtodoinjava.orderdesk.anthropic;

import org.springframework.ai.anthropic.AnthropicChatOptions;
import org.springframework.ai.chat.client.ChatClient;
import org.springframework.ai.chat.messages.AssistantMessage;
import org.springframework.ai.chat.model.ChatResponse;
import org.springframework.ai.chat.model.Generation;
import org.springframework.beans.factory.annotation.Qualifier;
import org.springframework.web.bind.annotation.GetMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;

@RestController
public class ThinkingController {

    private final ChatClient hostedClient;

    ThinkingController(@Qualifier("hostedClient") ChatClient hostedClient) {
        this.hostedClient = hostedClient;
    }

    // Extended thinking: Claude may use up to 1,024 tokens to reason before it answers
    @GetMapping("/ask/think")
    Thought think(@RequestParam String question) {
        ChatResponse response = hostedClient.prompt()
            .user(question)
            .options(AnthropicChatOptions.builder()
                .thinkingEnabled(1024)
                .maxTokens(2048)
                .temperature(1.0))
            .call()
            .chatResponse();

        // Each thinking block comes back as its own generation, marked with a "signature"
        StringBuilder thinking = new StringBuilder();
        StringBuilder answer = new StringBuilder();
        for (Generation generation : response.getResults()) {
            AssistantMessage message = generation.getOutput();
            if (message.getMetadata().containsKey("signature")) {
                thinking.append(message.getText());
            } else if (message.getText() != null) {
                answer.append(message.getText());
            }
        }
        return new Thought(thinking.toString(), answer.toString());
    }

    record Thought(String thinking, String answer) {
    }
}
In Spring AI 2.0, options(…) takes the options builder, so there is no .build() call. The Spring AI upgrade notes describe this change.
The following settings illustrate the budget-based configuration described in the Spring AI Anthropic reference. Check support for this mode when changing models:
- thinkingEnabled(1024) requests a 1,024-token thinking budget, the documented minimum for this budget-based mode.
- maxTokens(2048) gives a total output allowance greater than the thinking budget.
- temperature(1.0) overrides the ordinary 0.2 setting for the illustrated thinking configuration.
Spring AI exposes response content through Generation objects. The sample iterates over all results and uses the signature metadata key to distinguish a thinking block from final text. More complete handling may also need to account for redacted blocks.
Read the full response for this endpoint. The convenience .content() accessor can select a first result that is not the final answer when thinking-related blocks are present.
This response-handling code follows the documented structure, but was not verified against a successful Claude call. With a valid key and compatible model, the endpoint can be requested as follows:
curl -G localhost:8083/ask/think \
  --data-urlencode "question=A customer got the wrong colour and wants a refund and a discount. What should we offer?"
The captured body confirms serialization of the options. It does not establish that Anthropic accepts them for the chosen account and model:
{"max_tokens":2048,"messages":[{"content":"A customer got the wrong colour and wants a refund and a discount. What should we offer?","role":"user"}],"model":"claude-haiku-4-5","system":"You are OrderDesk, the support assistant of an online store. Answer in at most three sentences.","temperature":1.0,"thinking":{"budget_tokens":1024,"type":"enabled"}}The example separates thinking content from final text to demonstrate response handling. A customer-facing application should normally show the final answer and decide deliberately whether auxiliary content needs to be retained. Additional reasoning can increase latency and token usage.
6. Deployment Considerations
A few things change when real customers start using the hosted model:
- Monitor token usage, request volume, and model pricing. An output cap helps bound a response, but does not provide complete budget control.
- Handle authentication errors, throttling, timeouts, and outages. Local fallback requires explicit implementation and a product decision; this controller does not provide it.
- Customer messages leave your machine. Check that this is allowed for your data, and don’t send what you don’t need.
- Keep the model name in application.properties, so moving to a newer Claude model is a configuration change.
The shared ChatModel and ChatClient APIs reduce provider-specific calling code. Features and options still depend on the model, so check compatibility when moving other OrderDesk functionality to Claude.
All articles in order: Spring AI Tutorial
Drop me your questions related to Spring AI with Anthropic Claude in the comments.
Happy Learning !!
