
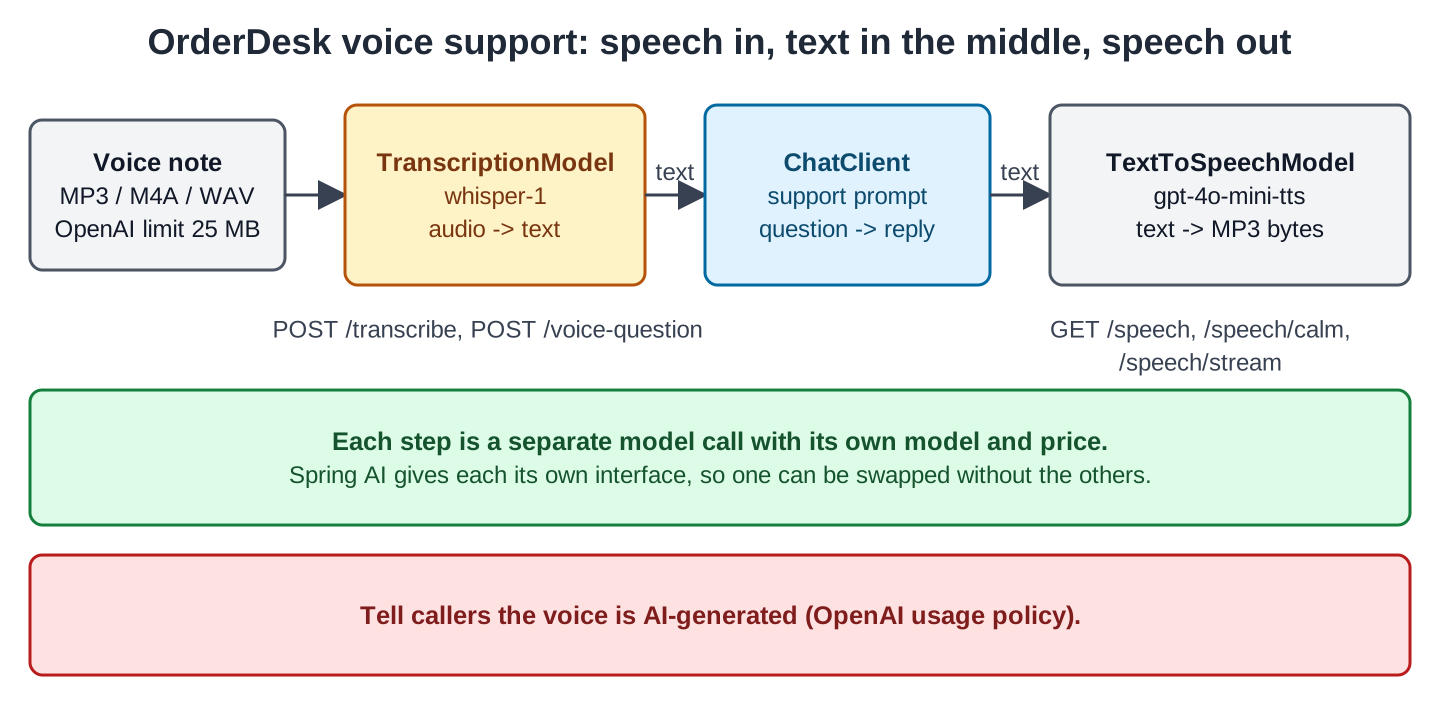
TranscriptionModel submits recorded audio and returns recognized text. The transcript can then become the input to a separate ChatClient request, giving a voice note the same support flow as a typed question.
This example uses Spring AI 2.0.1 and whisper-1 in a separate media application. It shows upload handling, transcription options, and a two-step voice-question endpoint, but includes no successful account-backed transcription. OpenAI lists whisper-1 for shutdown on February 26, 2027; see the current transcription guide before choosing it for a new deployment.
1. From an Audio Upload to Text
The basic transcription path sends an audio resource and request options to the model integration, then reads the returned text. These three types describe that exchange:
- AudioTranscriptionPrompt holds the audio as a Spring Resource (any readable file or upload) plus options such as the language.
- TranscriptionModel is the interface that sends it to a provider. With the OpenAI starter, the bean is OpenAiAudioTranscriptionModel.
- AudioTranscriptionResponse holds the result; getResult().getOutput() returns the text.
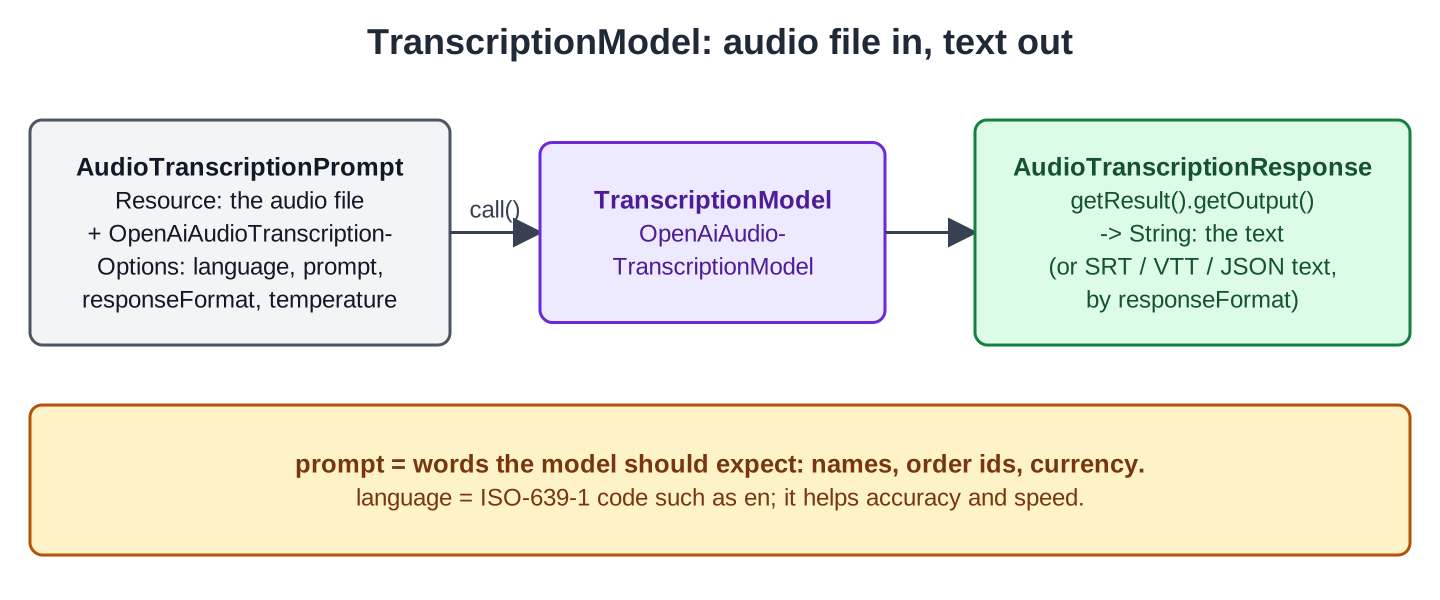
The text is a plain String, so OrderDesk passes it to ChatClient, the Spring AI API for chat models, which writes the support answer:
Spring AI 2.0.1 has transcription models for OpenAI and Azure OpenAI. Ollama has none, so this article needs an OpenAI API key. We compiled the code but didn’t run it against OpenAI. Step 2 shows what we checked instead.
2. The Example App
This article is part of the OrderDesk series, but its code lives in orderdesk-media, a new Spring Boot application that we create here. All its classes belong to the com.howtodoinjava.orderdesk.media package, and it runs on port 8082.
The separate project isolates the hosted media configuration from the Ollama-based support app. Adding multiple providers to one application is possible, but requires deliberate bean and model selection. Keeping this example separate makes its credentials and backend choices clear.
2.1. Create the Project
Create a new Maven project with this pom.xml. It uses Java 21, Spring Boot 4.1.1 as the parent, and two starters. The Spring AI version comes from the BOM (bill of materials), a Maven file that fixes the versions of all Spring AI modules:
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
  xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
  xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 https://maven.apache.org/xsd/maven-4.0.0.xsd">
  <modelVersion>4.0.0</modelVersion>

  <parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>4.1.1</version>
    <relativePath/>
  </parent>

  <groupId>com.howtodoinjava</groupId>
  <artifactId>orderdesk-media</artifactId>
  <version>1.0.0</version>
  <name>orderdesk-media</name>

  <properties>
    <java.version>21</java.version>
  </properties>

  <dependencyManagement>
    <dependencies>
      <dependency>
        <groupId>org.springframework.ai</groupId>
        <artifactId>spring-ai-bom</artifactId>
        <version>2.0.1</version>
        <type>pom</type>
        <scope>import</scope>
      </dependency>
    </dependencies>
  </dependencyManagement>

  <dependencies>
    <dependency>
      <groupId>org.springframework.boot</groupId>
      <artifactId>spring-boot-starter-web</artifactId>
    </dependency>
    <dependency>
      <groupId>org.springframework.ai</groupId>
      <artifactId>spring-ai-starter-model-openai</artifactId>
    </dependency>
  </dependencies>

  <build>
    <plugins>
      <plugin>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-maven-plugin</artifactId>
      </plugin>
    </plugins>
  </build>
</project>
The OpenAI starter supplies the integrations used by the application. Model auto-configuration can also be enabled or disabled independently; the transcription endpoint does not require using every model type.
The main class MediaApplication goes in com.howtodoinjava.orderdesk.media:
package com.howtodoinjava.orderdesk.media;

import org.springframework.boot.SpringApplication;
import org.springframework.boot.autoconfigure.SpringBootApplication;

@SpringBootApplication
public class MediaApplication {

    public static void main(String[] args) {
        SpringApplication.run(MediaApplication.class, args);
    }
}
2.2. The API Key and Properties
Create an API key on the OpenAI API keys page. The key goes into an environment variable, never into a file that ends up in Git:
export SPRING_AI_OPENAI_API_KEY=sk-your-key
mvn spring-boot:run
On Windows, use set SPRING_AI_OPENAI_API_KEY=sk-your-key in the Command Prompt. In PowerShell, use $env:SPRING_AI_OPENAI_API_KEY=”sk-your-key”. Spring Boot reads this variable as the property spring.ai.openai.api-key. Without a key, the application doesn’t start:
Caused by: java.lang.IllegalStateException: At least one credential source must be specified: credential (apiKey), workloadIdentity, or adminApiKeyThe message names two other credential types, but an API key is all we need.
The application.properties lines this article uses:
spring.application.name=orderdesk-media
server.port=8082

spring.ai.openai.audio.transcription.model=whisper-1
spring.ai.openai.audio.transcription.language=en

spring.servlet.multipart.max-file-size=10MB
The configuration explicitly selects whisper-1 and the language hint en. Its upload-size setting allows files up to 10 MB. File size, accepted media formats, response formats, and model lifecycle are separate constraints to check.
3. Transcribing a Voice Note
We write one endpoint that returns the transcript, then a second one that answers the voice note with ChatClient.
Step 1: Write the Transcription Endpoint
Let’s start with the /transcribe endpoint. It takes an uploaded audio file and returns the text. Spring MVC gives us the upload as a MultipartFile, and getResource() turns it into the Resource that AudioTranscriptionPrompt expects:
package com.howtodoinjava.orderdesk.media;

import org.springframework.ai.audio.transcription.AudioTranscriptionPrompt;
import org.springframework.ai.audio.transcription.AudioTranscriptionResponse;
import org.springframework.ai.audio.transcription.TranscriptionModel;
import org.springframework.ai.chat.client.ChatClient;
import org.springframework.ai.openai.OpenAiAudioTranscriptionOptions;
import org.springframework.web.bind.annotation.PostMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;
import org.springframework.web.multipart.MultipartFile;

import com.openai.models.audio.AudioResponseFormat;

@RestController
public class TranscriptionController {

    private final TranscriptionModel transcriptionModel;
    private final ChatClient chatClient;

    TranscriptionController(TranscriptionModel transcriptionModel, ChatClient.Builder builder) {
        this.transcriptionModel = transcriptionModel;
        this.chatClient = builder
            .defaultSystem("You are OrderDesk, the support assistant of an online store. "
                + "Answer in at most three sentences.")
            .build();
    }

    // Turns a customer's voice note into text
    @PostMapping("/transcribe")
    String transcribe(@RequestParam("audio") MultipartFile audio) {
        AudioTranscriptionPrompt prompt = new AudioTranscriptionPrompt(audio.getResource(),
            OpenAiAudioTranscriptionOptions.builder()
                .language("en")
                .prompt("OrderDesk, order ids such as ORD-1042, INR")
                .responseFormat(AudioResponseFormat.TEXT)
                .temperature(0f)
                .build());
        AudioTranscriptionResponse response = transcriptionModel.call(prompt);
        return response.getResult().getOutput();
    }
}
The constructor also builds a ChatClient with a default system prompt; Step 3 uses it. The options set four things for this request:
| Option | Value | Effect |
|---|---|---|
| language | en | Tells the model the spoken language, instead of detecting it |
| prompt | OrderDesk, order ids such as ORD-1042, INR | Words the model should expect, so it spells them right |
| responseFormat | AudioResponseFormat.TEXT | Plain text; other values are JSON, VERBOSE_JSON, SRT, VTT and DIARIZED_JSON |
| temperature | 0 | The least random output |
AudioResponseFormat comes from OpenAI’s official openai-java SDK (package com.openai.models.audio), which the OpenAI starter uses since Spring AI 2.0. Options passed in the prompt override the application.properties values for this call only.
Step 2: Send an Audio File
Next, we send a voice note to the endpoint. Record a short one on your phone, such as “Hi, my order ORD-1042 arrived without the charger, can you send it?”. Then send it with curl -F, which builds a multipart upload:
curl -F "audio=@voice-note.m4a" localhost:8082/transcribeA successful provider call would return the transcript as text. No such output is included here, because the original example did not use valid provider credentials.
The original check points the client at a local recording server. It captures a multipart request and returns an error, so it demonstrates the transmitted fields rather than speech-recognition quality. The captured request includes these parts:
file             (filename="note.mp3", the uploaded bytes)
model            whisper-1
language         en
prompt           OrderDesk, order ids such as ORD-1042, INR
response_format  text
temperature      0
Keep an extension-bearing filename and a suitable content type with the uploaded bytes. Also validate the actual file and its size. The sample’s 10 MB application limit is lower than the documented 25 MB file limit for this provider workflow.
Step 3: Answer the Voice Note
The /voice-question endpoint performs two separate calls: transcription first, then chat generation using the transcript. A recognition mistake can therefore affect the generated answer. Inspect or confirm critical extracted values before using them to look up an order.
    // Voice note in, written support answer out
    @PostMapping("/voice-question")
    String voiceQuestion(@RequestParam("audio") MultipartFile audio) {
        String question = transcribe(audio);
        return chatClient.prompt().user(question).call().content();
    }
curl -F "audio=@voice-note.m4a" localhost:8082/voice-questionThe response is the written support answer. We didn’t run this against OpenAI either, so no output is shown.
The chat step also uses the OpenAI integration in this separate application. Select its model explicitly for a deployment instead of relying on an integration default. Supplying the transcript alone does not provide the store’s policies or authorization rules.
4. Options Worth Knowing
The spring.ai.openai.audio.transcription. properties set defaults for every call, and OpenAiAudioTranscriptionOptions overrides them per call:
| Property | What it does |
|---|---|
| model | whisper-1 (default), gpt-4o-transcribe, gpt-4o-mini-transcribe or gpt-4o-transcribe-diarize |
| language | ISO-639-1 code of the spoken language |
| prompt | Words or text style to expect; for whisper-1 up to 224 tokens (a token is a word piece) |
| response-format | text (default), json, verbose_json, srt, vtt, diarized_json |
| temperature | 0 to 1; 0 by default |
| timestamp-granularities | word or segment; needs response-format verbose_json |
SRT and VTT are subtitle formats: the text with start and end times per line. For subtitles of a product video, set responseFormat(AudioResponseFormat.SRT) and save the returned string as a .srt file.
Speaker annotations require a compatible model and response format. The options enum contains formats for several model capabilities; not every listed value is supported by whisper-1.
5. Common Traps
5.1. Upload Larger Than 1 MB
Without spring.servlet.multipart.max-file-size, Spring Boot rejects any upload above 1 MB with a MaxUploadSizeExceededException, before our code runs. One minute of phone audio is often bigger than that, so our app sets max-file-size=10MB.
A second property, spring.servlet.multipart.max-request-size, limits the whole request and is 10 MB by default. To accept files above 10 MB (OpenAI allows up to 25 MB), raise both properties, for example to 25MB.
5.2. Order Ids and Product Names Spelled Wrong
Order IDs and product names can be misrecognized. A vocabulary hint may improve spelling, but a matching regular expression proves only the format, not that the value was heard correctly. Confirm the value against authorized application data or ask the customer when it is ambiguous.
5.3. Old Property Names
Articles written for Spring AI 1.0 use spring.ai.openai.audio.transcription.options.language. In 2.0.1, these .options. names still work but are deprecated, and the new names drop options, as in Section 2.2.
6. FAQs
6.1. Can I transcribe audio with Ollama?
Not through Spring AI 2.0.1: it has no Ollama transcription model. But you can point spring.ai.openai.audio.transcription.base-url to any server that offers the same API as OpenAI’s /v1/audio/transcriptions. Unlike spring.ai.openai.base-url, this property changes the address for transcription only.
6.2. How do I transcribe a file from disk instead of an upload?
Pass any Resource, such as new FileSystemResource(“calls/2026-10-18.mp3”), to AudioTranscriptionPrompt. The rest of the code stays the same.
6.3. Can I translate the audio to English?
OpenAI has a separate translation endpoint for whisper-1, but Spring AI 2.0.1’s TranscriptionModel doesn’t call it. So transcribe in the original language, then translate the text with ChatClient.
6.4. What does a transcription cost?
OpenAI prices transcription per minute of audio, and the price depends on the model; see the OpenAI pricing page.
7. Conclusion
Pass a validated audio Resource and model-compatible options to TranscriptionModel. Use the returned text as a separate input to support processing, with checks for important identifiers and recognition errors. Configure both application upload limits and provider limits, and review the selected model’s retirement schedule.
All articles in order: Spring AI Tutorial
8. References
Drop me your questions related to Spring AI speech to text in the comments.
Happy Learning !!
