
TextToSpeechModel converts application text into audio data. OrderDesk’s media example uses it to return an MP3 reply, apply different voice options, and write an incremental audio response from Spring MVC.
The code uses Spring AI 2.0.1 and the Speech API model gpt-4o-mini-tts. Recorded checks use local stub responses, not generated provider audio. OpenAI now marks this model and Speech API workflow for shutdown on January 6, 2027; consult the current speech guide before adopting this existing-integration example.
1. Understand Speech Requests and Audio Responses
A speech model turns text into audio in one call. Spring AI wraps it in three types:
- TextToSpeechPrompt holds the text and, optionally, options such as the voice and the speed.
- TextToSpeechModel is the interface that sends it to a provider. With the OpenAI starter, the bean is OpenAiAudioSpeechModel.
- TextToSpeechResponse holds the result; getResult().getOutput() returns the audio as a byte[].
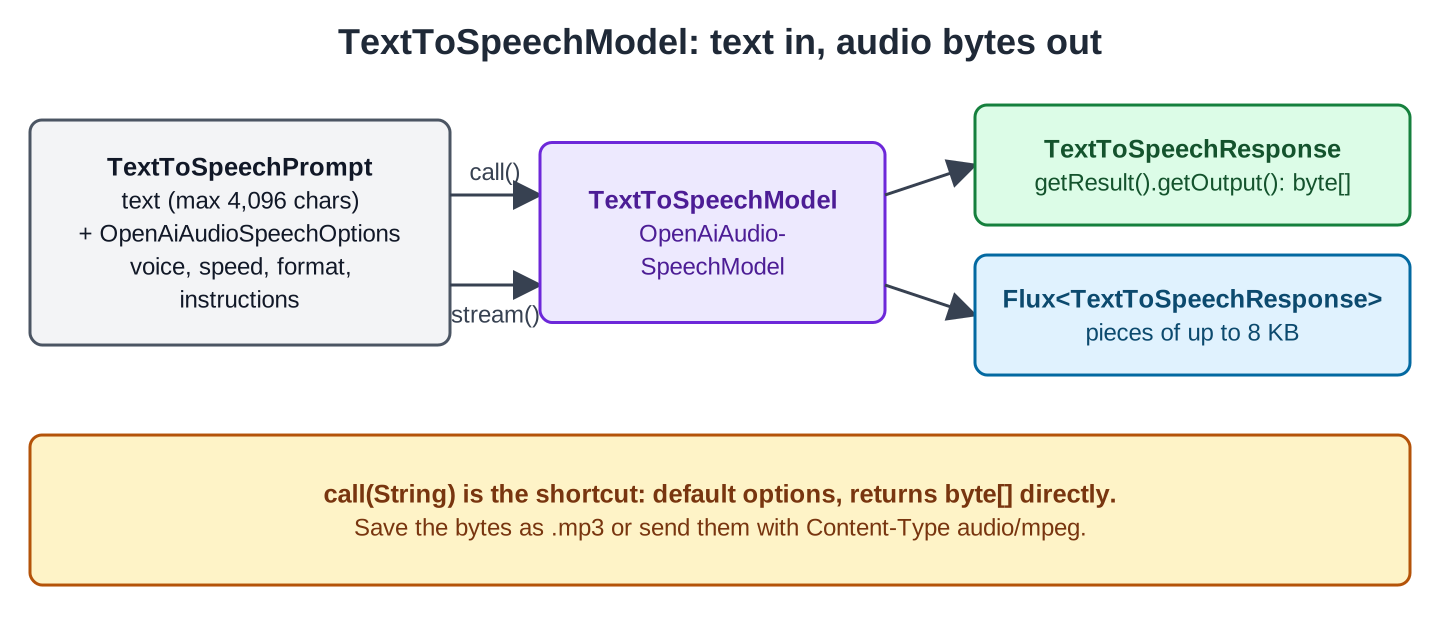
The synchronous path returns completed audio. The streaming path exposes arriving data through Reactor so the HTTP response can start before all audio is available. Whether a player starts immediately also depends on buffering and the chosen format.
A voice-support flow has separate transcription, answer-generation, and speech-generation steps. Each can use its own model and configuration. This article covers the last step only: its endpoints receive the text to speak rather than generating a support answer themselves.
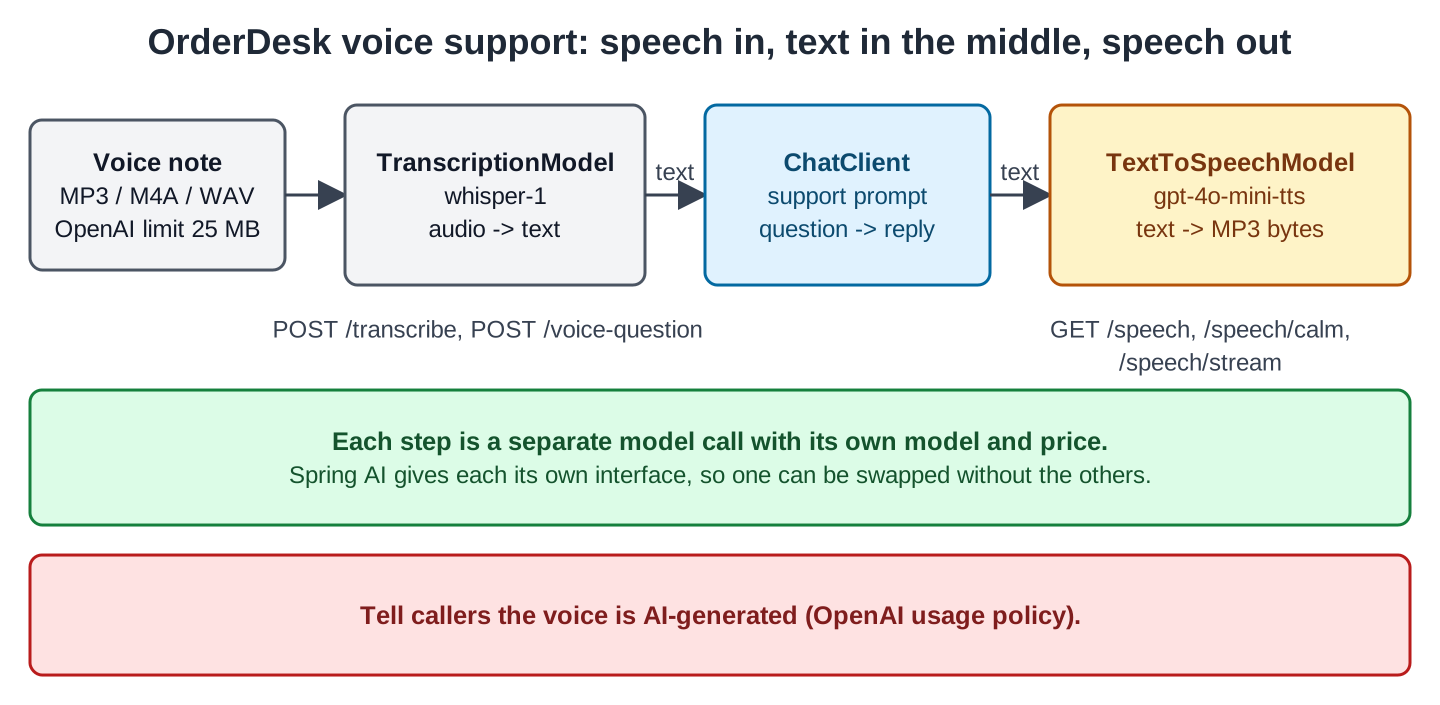
Spring AI 2.0.1 has speech models for OpenAI and ElevenLabs, but none for Ollama, so this article needs an OpenAI API key. We compiled the code but didn’t run it against OpenAI. FAQ 6.4 lists what we checked.
2. The Example App
The example keeps audio code in a separate orderdesk-media application on port 8082. This avoids changing the Ollama-only configuration of the main app. Multiple providers can coexist, but their model and ChatClient beans need explicit configuration rather than accidental auto-configuration choices.
2.1. Create the Project
The project uses Spring Boot 4.1.1, Java 21, and two starters. The Spring AI version comes from the BOM (bill of materials), a Maven file that fixes the versions of all Spring AI modules. Here’s the complete pom.xml:
<?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
  xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
  xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 https://maven.apache.org/xsd/maven-4.0.0.xsd">
  <modelVersion>4.0.0</modelVersion>

  <parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>4.1.1</version>
    <relativePath/>
  </parent>

  <groupId>com.howtodoinjava</groupId>
  <artifactId>orderdesk-media</artifactId>
  <version>1.0.0</version>
  <name>orderdesk-media</name>

  <properties>
    <java.version>21</java.version>
  </properties>

  <dependencyManagement>
    <dependencies>
      <dependency>
        <groupId>org.springframework.ai</groupId>
        <artifactId>spring-ai-bom</artifactId>
        <version>2.0.1</version>
        <type>pom</type>
        <scope>import</scope>
      </dependency>
    </dependencies>
  </dependencyManagement>

  <dependencies>
    <dependency>
      <groupId>org.springframework.boot</groupId>
      <artifactId>spring-boot-starter-web</artifactId>
    </dependency>
    <dependency>
      <groupId>org.springframework.ai</groupId>
      <artifactId>spring-ai-starter-model-openai</artifactId>
    </dependency>
  </dependencies>

  <build>
    <plugins>
      <plugin>
        <groupId>org.springframework.boot</groupId>
        <artifactId>spring-boot-maven-plugin</artifactId>
      </plugin>
    </plugins>
  </build>
</project>
The spring-ai-starter-model-openai starter registers a bean for every OpenAI model type, including TextToSpeechModel. It also brings Project Reactor, so Flux needs no extra dependency.
The main class goes in the package com.howtodoinjava.orderdesk.media, and so does every class in this article:
package com.howtodoinjava.orderdesk.media;

import org.springframework.boot.SpringApplication;
import org.springframework.boot.autoconfigure.SpringBootApplication;

@SpringBootApplication
public class MediaApplication {

    public static void main(String[] args) {
        SpringApplication.run(MediaApplication.class, args);
    }
}
2.2. The API Key and Properties
Create the API key on the OpenAI platform (platform.openai.com). The account needs credit because every speech request is billed. Keep the key in an environment variable, not in a file that ends up in Git:
export SPRING_AI_OPENAI_API_KEY=sk-your-key
mvn spring-boot:run
On Windows, use set SPRING_AI_OPENAI_API_KEY=sk-your-key in the Command Prompt, or $env:SPRING_AI_OPENAI_API_KEY=”sk-your-key” in PowerShell. Spring Boot maps the variable to the property spring.ai.openai.api-key. Without a key, the application doesn’t start:
Caused by: java.lang.IllegalStateException: At least one credential source must be specified: credential (apiKey), workloadIdentity, or adminApiKeyWith a wrong key, the application starts, but the first call fails. The com.openai error comes from OpenAI’s openai-java SDK, which Spring AI 2.0 uses:
com.openai.errors.UnauthorizedException: 401: Incorrect API key provided: sk-place**lder.The speech lines in application.properties:
spring.application.name=orderdesk-media
server.port=8082

spring.ai.openai.audio.speech.model=gpt-4o-mini-tts
spring.ai.openai.audio.speech.voice=alloy
spring.ai.openai.audio.speech.response-format=mp3
The properties make this example’s selected model, voice, and audio format explicit. Review these choices and the model’s lifecycle before deployment.
3. Reading Replies Aloud
We build one controller, SpeechController, with three endpoints: a plain MP3, an MP3 with another voice, and a streamed MP3.
Step 1: Return an MP3 from a Text
Let’s start with the shortest call, call(String). It uses the default options and returns the audio bytes directly. The controller returns them with the content type audio/mpeg, so a browser plays them:
package com.howtodoinjava.orderdesk.media;

import org.springframework.ai.audio.tts.TextToSpeechModel;
import org.springframework.ai.audio.tts.TextToSpeechPrompt;
import org.springframework.ai.audio.tts.TextToSpeechResponse;
import org.springframework.ai.openai.OpenAiAudioSpeechOptions;
import org.springframework.http.MediaType;
import org.springframework.http.ResponseEntity;
import org.springframework.web.bind.annotation.GetMapping;
import org.springframework.web.bind.annotation.RequestParam;
import org.springframework.web.bind.annotation.RestController;
import org.springframework.web.servlet.mvc.method.annotation.StreamingResponseBody;

import reactor.core.publisher.Flux;

@RestController
public class SpeechController {

    private final TextToSpeechModel speechModel;

    SpeechController(TextToSpeechModel speechModel) {
        this.speechModel = speechModel;
    }

    // Reads a support reply aloud and returns an MP3 file
    @GetMapping(value = "/speech", produces = "audio/mpeg")
    byte[] speak(@RequestParam String text) {
        return speechModel.call(text);
    }
}
The other imports are for Steps 2 and 3. Save the audio to a file with curl -o:
curl -G localhost:8082/speech -o reply.mp3 \
  --data-urlencode "text=Your refund for order ORD-1042 is on its way."
No provider-generated MP3 is included. The original local stub records the outgoing request and returns an error, which demonstrates serialization rather than speech quality. Its temporary localhost base URL is only for that check. The captured body at /v1/audio/speech is:
{"input":"Your refund is on its way.","model":"gpt-4o-mini-tts","voice":"alloy","response_format":"mp3","speed":1.0}The model, voice and format come from application.properties, and the speed is the default 1.0.
Step 2: Change the Voice for One Request
Next, we change the voice and tone for one reply, such as an apology. For that, we pass OpenAiAudioSpeechOptions in a TextToSpeechPrompt. Add this method to SpeechController:
    // The same with options for one request: another voice, slower, with a tone
    @GetMapping(value = "/speech/calm", produces = "audio/mpeg")
    byte[] speakCalm(@RequestParam String text) {
        TextToSpeechResponse response = speechModel.call(new TextToSpeechPrompt(text,
            OpenAiAudioSpeechOptions.builder()
                .voice(OpenAiAudioSpeechOptions.Voice.NOVA)
                .speed(0.9)
                .instructions("Speak in a calm, friendly customer support tone.")
                .build()));
        return response.getResult().getOutput();
    }
For the text “Hello”, the stub received these values, merged with the defaults from the properties:
{"input":"Hello","model":"gpt-4o-mini-tts","voice":"nova","instructions":"Speak in a calm, friendly customer support tone.","response_format":"mp3","speed":0.9}The options do three things:
| Option | Value | Effect |
|---|---|---|
| voice | Voice.NOVA | One of the built-in voices, such as ALLOY, ASH, CORAL, ECHO, NOVA or SAGE |
| speed | 0.9 | 0.25 to 4.0; 1.0 is normal speed |
| instructions | a sentence | Tone, accent or pace in plain words; only gpt-4o-mini-tts reads it, not tts-1 or tts-1-hd |
A string-based voice option can express names absent from the integration’s enum. Confirm that the selected model supports the voice before using it; accepting a String in Java does not validate provider availability.
Step 3: Stream the Audio
Finally, we stream the audio. A long reply takes a few seconds to generate, and call() returns only when the whole file is ready. The stream(String) method returns a Flux<byte[]> that delivers the audio in pieces as they arrive. Add this method to SpeechController:
    // Writes each piece of audio to the response as soon as it arrives
    @GetMapping("/speech/stream")
    ResponseEntity<StreamingResponseBody> stream(@RequestParam String text) {
        Flux<byte[]> pieces = speechModel.stream(text);
        StreamingResponseBody body = out -> {
            for (byte[] piece : pieces.toIterable()) {
                out.write(piece);
                out.flush();
            }
        };
        return ResponseEntity.ok()
            .contentType(MediaType.parseMediaType("audio/mpeg"))
            .body(body);
    }
StreamingResponseBody is a Spring MVC callback that writes to the response after the controller method returns. The toIterable() method turns the Flux into a loop that waits for each piece, and flush() sends each piece to the client right away. Returning the Flux directly doesn’t work in Spring MVC (see Section 5.1).
For streaming, Spring AI adds “stream_format”:”audio” to the request, so OpenAI sends the audio in pieces. Save the stream with curl as before:
curl -G localhost:8082/speech/stream -o reply.mp3 \
  --data-urlencode "text=Your refund for order ORD-1042 is on its way."
The recorded streaming check uses a local stub that emits five pieces half a second apart. First-byte timings of 1.1 seconds versus 2.5 seconds describe that artificial response, not OpenAI inference performance. Both application paths returned the same stub bytes.
4. Options and Formats
The spring.ai.openai.audio.speech. properties set defaults for every call, and OpenAiAudioSpeechOptions overrides them per call:
| Property | What it does |
|---|---|
| model | gpt-4o-mini-tts (default), tts-1 (faster), tts-1-hd (higher quality) |
| voice | alloy (default) or another built-in voice |
| response-format | mp3 (default), opus, aac, flac, wav, pcm |
| speed | 0.25 to 4.0; 1.0 by default |
| instructions | Tone and style; gpt-4o-mini-tts only |
MP3 suits a browser or a phone. According to OpenAI’s documentation, WAV and PCM arrive fastest because they aren’t compressed. Use them when the audio must play at once, such as in a voice bot. If you change the format, change the content type of the endpoint too, such as audio/wav.
5. Common Traps
5.1. Returning Flux<byte[]> from Spring MVC
The first version of Step 3 returned the Flux directly:
@GetMapping(value = "/speech/stream", produces = MediaType.APPLICATION_OCTET_STREAM_VALUE)
Flux<byte[]> stream(@RequestParam String text) {
    return speechModel.stream(text);
}
It compiles, but the request fails with HTTP 500. The log shows HttpMessageNotWritableException: No converter for [class … from DefaultHandlerExceptionResolver. Spring MVC streams a Flux only for text formats such as Server-Sent Events. For other content types, it collects the pieces into a list and finds no converter that writes that list as bytes. The fix is the StreamingResponseBody in Step 3.
5.2. Input Longer Than the Model Allows
Speech input limits are model-specific. Validate against the chosen model’s documented limit and split longer text at meaningful boundaries when needed. Do not assume that a limit expressed in characters applies to every model or replacement workflow.
5.3. Generating the Same Audio Again
Repeated calls can incur repeated charges, even when the text is unchanged. Cache reusable recordings by text, voice, format, and relevant options. A generated recording may also vary between calls, so save the version the application intends to serve.
5.4. Not Saying the Voice Is Generated
OpenAI’s usage policies require that we tell listeners the voice is AI-generated, not a human. Put a short line before the first audio reply in the app, such as “Replies are read by a computer voice.”
5.5. Old Class and Property Names
Spring AI 1.0 code uses SpeechModel, SpeechPrompt and spring.ai.openai.audio.speech.options.voice. In 2.0, the classes are TextToSpeechModel and TextToSpeechPrompt in the org.springframework.ai.audio.tts package. The speed option is a Double instead of a Float. The .options. property names are deprecated; use the names in Section 2.2.
6. FAQs
6.1. Can I generate speech with Ollama?
No, see Section 1. Use ElevenLabs, which has its own Spring AI starter, or a local server that offers the same /v1/audio/speech endpoint as OpenAI. Set spring.ai.openai.audio.speech.base-url to its address. This property changes the address for the speech model only, while spring.ai.openai.base-url changes it for every OpenAI model.
6.2. How do I save the audio to a file in Java?
The call() method returns a byte[], so Files.write(Path.of(“reply.mp3”), speechModel.call(text)) writes it. The file extension should match the response-format.
6.3. Which voice should I pick?
Generate the same support sentence with three or four voices and listen to them. The voices are tuned for English; for another language, test the voice with real replies first.
6.4. What was checked without an API key?
The original checks compiled the example and captured outgoing requests using placeholder configuration and local stubs. A second stub exercised delivery of incremental bytes. These checks do not verify provider-generated speech, pronunciation, voice quality, or a successful hosted response.
7. Conclusion
Use TextToSpeechModel for the speech request and select options compatible with that model. The MVC example writes streamed bytes through StreamingResponseBody. Validate input limits, preserve the audio format, and distinguish stub transport timings from real inference. Review the provider’s retirement schedule before relying on this existing workflow.
All articles in order: Spring AI Tutorial
8. References
- Spring AI Reference: OpenAI Text-to-Speech
- Spring AI Reference: Text-to-Speech API
- OpenAI: Text to speech
Drop me your questions related to Spring AI text to speech in the comments.
Happy Learning !!
